claude-opus-5-5Claude Opus 5.5 is the first model in Anthropic's Claude 5.5 family, released on 22 September 2026, and on APIMODELS it costs $2.40 per 1M input tokens and $12.00 per 1M output — 40% below Anthropic's $4 / $20 list — with prompt-cache reads at $0.12 and cache writes at $3.00. Anthropic's own framing: it performs at the level of Claude Fable 5.1 on most work while costing 40% less to run than Opus 5 on typical workloads, and it is built for long-running agentic coding and knowledge work. The specifications match Fable 5.1: a 1M-token context window, 128K max output, text and image input, and a reliable knowledge cutoff of June 2026. Adaptive thinking is always on and cannot be disabled — you steer depth with the effort parameter (default medium) — and four breaking changes carry over from Fable 5.1: forced tool use returns an error, thinking blocks are tied to the model that produced them, the older computer_20251124 tool is not accepted, and text between tool calls comes back inside thinking blocks. Call it through /v1/messages or the OpenAI-compatible /v1/chat/completions with one key; failed requests are not charged.
View complete API reference with all parameters and examples.
Enable real-time streaming responses with Server-Sent Events.
{
  "model": "claude-opus-5-5",
  "stream": true,
  "max_tokens": 1024,
  "messages": [...]
}Enable Claude to use tools and call functions.
{
  "model": "claude-opus-5-5",
  "max_tokens": 1024,
  "tools": [{
    "name": "get_weather",
    "description": "Get current weather for a location",
    "input_schema": {
      "type": "object",
      "properties": {
        "location": {"type": "string", "description": "City name"}
      },
      "required": ["location"]
    }
  }],
  "tool_choice": {"type": "auto"},
  "messages": [{"role": "user", "content": "What's the weather in Tokyo?"}]
}Analyze PDF documents by sending them as base64 encoded content.
{
  "model": "claude-opus-5-5",
  "max_tokens": 1024,
  "messages": [{
    "role": "user",
    "content": [{
      "type": "document",
      "source": {
        "type": "base64",
        "media_type": "application/pdf",
        "data": "<base64_encoded_pdf>"
      }
    }, {
      "type": "text",
      "text": "Summarize this document."
    }]
  }]
}Get structured JSON responses that match your schema.
{
  "model": "claude-opus-5-5",
  "max_tokens": 1024,
  "output_format": {
    "type": "json_schema",
    "schema": {
      "type": "object",
      "properties": {
        "name": {"type": "string"},
        "age": {"type": "integer"}
      },
      "required": ["name", "age"]
    }
  },
  "messages": [{"role": "user", "content": "Extract info: John is 30 years old"}]
}Enable Claude to search the web for up-to-date information.
{
  "model": "claude-opus-5-5",
  "max_tokens": 1024,
  "tools": [{
    "type": "web_search_20250305",
    "name": "web_search",
    "max_uses": 5
  }],
  "messages": [{"role": "user", "content": "What's the latest news about AI?"}]
}| Parameter | Type | Required | Description |
|---|---|---|---|
| model | string | Yes | Model identifier (e.g., claude-opus-5-5) |
| messages | array | Yes | Array of message objects with role and content |
| max_tokens | integer | Yes | Maximum tokens in the response (1 - 128000) |
| system | string | No | System prompt to set context |
| stream | boolean | No | Enable streaming responses (SSE) |
| temperature | number | No | Sampling temperature (0.0 - 1.0) |
| top_p | number | No | Nucleus sampling threshold (0.0 - 1.0) |
| top_k | integer | No | Top-k sampling (0 - infinity) |
| stop_sequences | array | No | Sequences that stop generation |
| tools | array | No | Function calling tools definition |
| tool_choice | object | No | Tool selection strategy (auto/any/tool) |
| thinking | object | No | Enable extended thinking mode |
| output_format | object | No | Structured output with JSON schema |
View complete API reference with streaming, thinking, and more.
Billing: Cost = (input_tokens * input_price + output_tokens * output_price) / 1,000,000
$2.40 / $12.00 per 1M tokens against Anthropic's $4 / $20 list; cache reads $0.12
Anthropic: Fable 5.1-level results on most work, 40% less to run than Opus 5
Same window as Fable 5.1; text and image input; knowledge cutoff June 2026
Cannot be disabled — steer depth with effort (default medium); forced tool use now errors
Claude Opus 5.5 is a Large Language Model API provided by Anthropic. Claude Opus 5.5 is the first model in Anthropic's Claude 5.5 family, released on 22 September 2026, and on APIMODELS it costs $2.40 per 1M input tokens and $12.00 per 1M output — 40% below Anthropic's $4 / $20 list — with prompt-cache reads at $0.12 and cache writes at $3.00. Anthropic's own framing: it performs at the level of Claude Fable 5.1 on most work while costing 40% less to run than Opus 5 on typical workloads, and it is built for long-running agentic coding and knowledge work. The specifications match Fable 5.1: a 1M-token context window, 128K max output, text and image input, and a reliable knowledge cutoff of June 2026. Adaptive thinking is always on and cannot be disabled — you steer depth with the effort parameter (default medium) — and four breaking changes carry over from Fable 5.1: forced tool use returns an error, thinking blocks are tied to the model that produced them, the older computer_20251124 tool is not accepted, and text between tool calls comes back inside thinking blocks. Call it through /v1/messages or the OpenAI-compatible /v1/chat/completions with one key; failed requests are not charged. Through APIMODELS platform, you can access this model via a unified API with transparent pay-as-you-go pricing. Current pricing: Input: $2.40, Output: $12.00 per 1M tokens.
Build intelligent conversational systems to automatically answer user queries and improve service efficiency.
Automatically write articles, emails, ad copy, and other text content to boost productivity.
Assist with code writing, debugging, and code review to accelerate software development.
Understand and analyze unstructured data, extract key insights, and generate summary reports.
Claude Opus 5.5 is available through APIMODELS at: Input: $2.40, Output: $12.00 per 1M tokens. Billing is pay-as-you-go — you only pay for what you generate.
Sign up at APIMODELS, get your API key, and call our unified API endpoint. We provide detailed API documentation with code examples in cURL, Python, and Node.js.
APIMODELS offers the same Claude Opus 5.5 model through our aggregation platform. We provide a unified API interface so you do not need separate accounts for each provider - one API key to access all models.
$2.40 per 1M input tokens and $12.00 per 1M output, with cache reads at $0.12 and cache writes at $3.00. Anthropic lists $4 / $20 with cache reads at $0.20, so we are 40% below. Billing is per actual token, failed requests are free, and there is no monthly minimum.
Anthropic's own positioning: Opus 5.5 performs at the level of Fable 5.1 on most work while costing 40% less to run than Opus 5 on typical workloads. Here Opus 5.5 is $2.40 / $12.00, Opus 5 is $3 / $15 and Fable 5.1 is $5 / $25 — unless you have verified that a task only comes out right on Fable 5.1, starting on Opus 5.5 is the better default. All three share the same specs: 1M context, 128K output.
Change the model name to claude-opus-5-5, then watch four breaking changes: adaptive thinking is always on and can no longer be disabled (steer depth with effort, default medium); forced tool use — tool_choice naming a specific tool — returns an error; thinking blocks are tied to the model that produced them, so a conversation cannot carry old thinking blocks across models; and the older computer_20251124 tool is not accepted. Text between tool calls also comes back inside thinking blocks, so apps that stream it as progress need to set display.
Both work: the native Anthropic POST https://api.apimodels.app/v1/messages, or the OpenAI-compatible /v1/chat/completions, with model claude-opus-5-5 and Authorization: Bearer your apimodels key. Streaming, tool calling and image input are supported; prompt caching follows Anthropic's cache_control usage and hits bill at $0.12.
On APIMODELS, Claude Opus 5.5 runs alongside 60+ models on one API key and one balance, so choosing is about fit, not lock-in. It supports 40% Below Official, 1M Context, Agentic Coding, Adaptive Thinking, and you can weigh it on price and capability against other Large Language Model models, then switch by changing a single model-name string — no new account or integration. Browse every Large Language Model option with live pricing at apimodels.app/models.
Claude Opus 5.5 supports: 40% Below Official, 1M Context, Agentic Coding, Adaptive Thinking. See the APIMODELS docs for full parameters and call examples.
Yes. APIMODELS exposes Claude Opus 5.5 through a single unified API and one key — no separate provider accounts, and no need to handle each provider's regional network access yourself.
We support Stripe (Visa, Mastercard, and other international cards) and Alipay. Credits are available instantly after payment.
Opus 5.5 does not output video. It writes a program that draws every frame, and you turn those frames into an MP4. We ran the whole pipeline once through apimodels.app on 30 September 2026: one API call, a 12-second 1280x720 promo, 360 frames rendered with headless Chrome, encoded with ffmpeg. This is exactly what we did and what it cost.
The one rule that makes everything else work: the page must expose window.renderFrame(t) and draw frame t from scratch, with no clock, no randomness and no state carried between calls. Then a script can ask for frame 0, frame 1 … frame 359 in any order and get the same picture every time, which is what a video encoder needs. A page that animates itself with requestAnimationFrame looks fine in a browser but cannot be exported frame-accurately. We also fixed the rhythm in the prompt (120 BPM, a beat every 0.5 s) and asked the model to list its beat plan as a comment; it did, 24 beats, and every cut landed on one.
Describe what happens in each time window (problem, turn, payoff) before any visual detail. Name the labels you want on screen and say what must not appear (we asked for plain rounded labels instead of real company logos). Style comes last and stays short: one accent colour, which easing functions, and an explicit "no clutter in the last 3 seconds". The full prompt we sent is below, unedited.
The prompt we sent (verbatim)
You are writing a program that renders a video. Output one complete, self-contained HTML file and nothing else.

Rules for the program (these make it renderable frame by frame):
1. A single <canvas> of exactly 1280x720, no CSS scaling, black page background.
2. Expose a global function window.renderFrame(t) that draws the frame at time t (seconds, 0 <= t < 12) from scratch. Everything on screen must be a pure function of t: no Date.now, no performance.now, no Math.random (use a seeded PRNG if you need noise), no accumulated state between calls, no requestAnimationFrame loop.
3. Also expose window.DURATION = 12 and window.FPS = 30. When the page is opened normally, play it once in a loop with requestAnimationFrame by calling renderFrame, so a human can preview it.
4. No external assets, fonts, images or libraries. Use system-ui for text.
5. The rhythm is 120 BPM: a beat every 0.5 s. Put every major cut, text entrance and impact on a beat time (a multiple of 0.5). List the beat plan as a comment at the top of the script.

The story (tell this, then decide the visuals):
A 12-second promo for "APIMODELS", an API gateway. Problem, then turn, then payoff:
- 0-3 s: a developer's screen is cluttered with many different API keys and SDK logos flying in from every side, overlapping, getting chaotic (draw them as simple rounded labels such as "image", "video", "LLM", "audio", "key_1", "key_2", "sdk", not real company logos).
- 3-4.5 s: everything snaps together on a beat and collapses into one glowing key.
- 4.5-9 s: from that one key, lines fan out to a grid of model cards that light up one per beat (label them "145 models", "image", "video", "LLM", "audio", "one endpoint").
- 9-12 s: clean end card: the word APIMODELS, the line "One key. Every model.", and "apimodels.app" small underneath; hold still for the last second.

Style: dark background, one accent colour (electric violet #7c5cff) plus white, motion with easing (easeOutCubic / easeInOutQuad written by you), subtle depth (scale and blur fall-off), no clutter in the final 3 seconds.

Before the code, do not explain. Return only the HTML.Opus 5.5 thinks before it writes, and the thinking counts as output. On this prompt the first character of the answer arrived after 110 seconds and the whole reply took 6 minutes 37 seconds: 31,786 output tokens for about 16,000 characters of HTML. Stream the request so the connection stays alive, and do not send a small max_tokens; the gateway forwards none when you omit it, so the model uses its own limit. The call cost $0.368 at $2.40 / $12 per million tokens, and the exact amount is returned by GET /v1/records/{id}.
curl https://api.apimodels.app/v1/chat/completions \
  -H "Authorization: Bearer $APIMODELS_API_KEY" \
  -H "Content-Type: application/json" \
  -d "$(jq -n --rawfile p prompt.md \
        '{model:"claude-opus-5-5", stream:true, messages:[{role:"user", content:$p}]}')" \
  --no-buffer > stream.txt
# no max_tokens on purpose: this run used 31,786 output tokens, mostly thinkingOpen the page, stop its preview loop, then call renderFrame(i / 30) for every frame and read the canvas back as a PNG. 360 frames took 14 seconds on a laptop and the page threw no errors. Encoding to H.264 with faststart gave a 1.8 MB file that plays everywhere.
// render.mjs — pnpm add puppeteer-core; uses the Chrome you already have
import puppeteer from 'puppeteer-core'
import { mkdirSync, writeFileSync } from 'node:fs'

mkdirSync('frames', { recursive: true })
const browser = await puppeteer.launch({
  executablePath: '/Applications/Google Chrome.app/Contents/MacOS/Google Chrome',
})
const page = await browser.newPage()
await page.setViewport({ width: 1280, height: 720 })
await page.goto('file://' + process.cwd() + '/promo.html')
await page.evaluate(() => { window.requestAnimationFrame = () => 0 }) // stop the preview loop
const { DURATION, FPS } = await page.evaluate(() => ({ DURATION, FPS }))
for (let i = 0; i < DURATION * FPS; i++) {
  const png = await page.evaluate((t) => {
    window.renderFrame(t)
    return document.querySelector('canvas').toDataURL('image/png')
  }, i / FPS)
  writeFileSync(`frames/f${String(i).padStart(4, '0')}.png`, Buffer.from(png.split(',')[1], 'base64'))
}
await browser.close()
ffmpeg -framerate 30 -i frames/f%04d.png -c:v libx264 -pix_fmt yuv420p -crf 20 -movflags +faststart promo.mp4
# add a soundtrack afterwards if you have one:
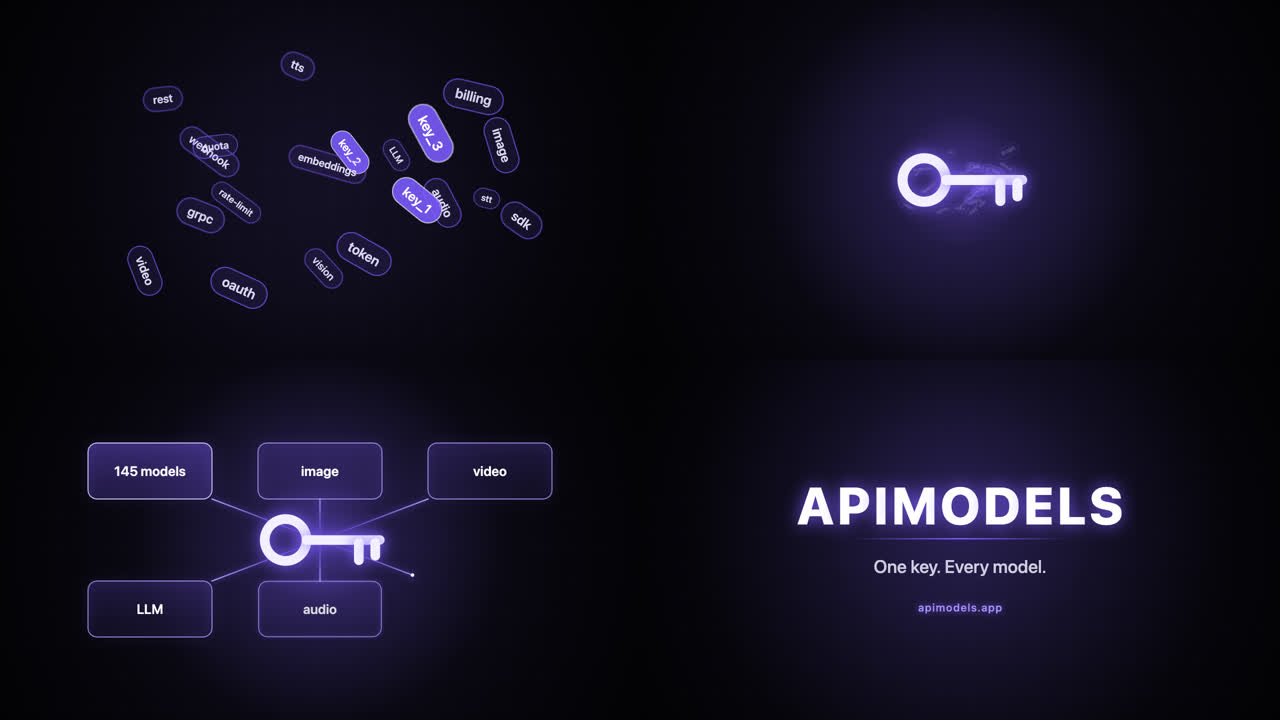
# ffmpeg -i promo.mp4 -i beat.mp3 -c:v copy -shortest promo-with-audio.mp4Pull a few frames at the story beats into one contact sheet and compare them with the brief: here 2.3 s (the clutter), 3.5 s (one key), 7.2 s (cards lighting up) and 11.3 s (end card). All four matched on the first try. To change something, ask for it by timecode and beat ("at 7.5 s the sixth card should light up with a pulse"), and ask for the whole file back so the frame contract stays intact.
Idea credit: the workflow was inspired by EianLu’s article on making motion videos with Opus 5.5 on X. Everything on this page (prompt, code, video, numbers) comes from our own run. Read the original article on X
How to get access, regional availability, and how this model compares with its alternatives.
