qwen3-imageAlibaba Qwen Image 3.0 — text-to-image and image editing in one model, chosen automatically by whether the request carries reference images. Prompts up to 4.5k tokens with dense in-image text layout, 10px small-text rendering, 12 languages and 20+ native fonts. Output 1K or 2K in eight aspect ratios (1:1, 3:2, 2:3, 4:3, 3:4, 16:9, 9:16, 21:9), PNG. Flat $0.035 per image at either resolution; each reference image adds $0.004. Async — create then poll.
Generated image will appear here
Enter a prompt and click Generate
Text-to-image and image editing on one model name — add reference images and it edits, omit them and it generates
Up to 4.5k-token prompts and 10px small-text rendering — newspapers, storyboards, menus and exam sheets in a single pass
Native multilingual and multi-font rendering, legible for infographics and UI mockups straight out
$0.035 per image at 1K or 2K; each reference image adds $0.004. Failures are never charged
High-volume posters, web and UI layouts, and text-heavy designs where small type must stay legible
Qwen Image 3.0 é uma API de geração de imagens da Alibaba. Alibaba Qwen Image 3.0 — text-to-image and image editing in one model, chosen automatically by whether the request carries reference images. Prompts up to 4.5k tokens with dense in-image text layout, 10px small-text rendering, 12 languages and 20+ native fonts. Output 1K or 2K in eight aspect ratios (1:1, 3:2, 2:3, 4:3, 3:4, 16:9, 9:16, 21:9), PNG. Flat $0.035 per image at either resolution; each reference image adds $0.004. Async — create then poll. Pela plataforma APIMODELS, você acessa este modelo por uma API unificada com preços transparentes de pagamento por uso. Preço atual: 1K: $0.035, 2K: $0.035.
Modelo relacionado: qwen3-image-pro — the higher-fidelity tier of the same model — micro-expressions, pores and hair strands near real photography, 1K $0.037 / 2K $0.075
Modelo relacionado: gpt-image-2 — stronger on general in-image text and the only one here with native 4K — 1K $0.025, 2K $0.03, 4K $0.05
Modelo relacionado: nanobananapro — Gemini 3 Pro Image — reach for it when the subject is a realistic portrait rather than a text-heavy layout
Prompts de até 4.5k tokens e texto de 10px — jornais, storyboards, menus e provas são gerados como um layout estruturado, não uma imagem com texto colado.
Renderização multilíngue nativa, boa para infográficos, mockups de UI e materiais de marketing legíveis de imediato.
Entende instruções complexas e organiza muitos elementos em páginas web, painéis e interfaces em uma única passagem.
Coloque imagens em image_urls e ele edita — troca elementos, muda o estilo ou repinta mantendo o sujeito; omita-as para texto para imagem.
$0.035 por imagem em 1K e 2K, mais $0.004 por imagem de referência. Falhas nunca são cobradas, e uma única API key da apimodels.app também chama imagem, vídeo, LLM e áudio.
O Qwen Image 3.0 está disponível pela APIMODELS a: 1K: $0.035, 2K: $0.035. A cobrança é por uso — você paga apenas pelo que gera.
Cadastre-se na APIMODELS, obtenha sua chave de API e chame nosso endpoint unificado. Oferecemos documentação detalhada com exemplos em cURL, Python e Node.js.
A APIMODELS oferece o mesmo modelo Qwen Image 3.0 pela nossa plataforma de agregação. Fornecemos uma interface de API unificada, então você não precisa de contas separadas por provedor: uma única chave para acessar todos os modelos.
Qwen Image 3.0 is Alibaba's image generation model, strong at realistic images, structured layouts, dense in-image text and high-quality typography. On apimodels.app text-to-image and image editing are one model, chosen automatically by whether you pass reference images — omit them and it generates, include them and it edits. 1K/2K, flat $0.035 per image, plus $0.004 per reference image.
Standard Qwen Image 3.0 is the everyday tier: clear instruction following (prompts up to 4.5k tokens), stable text rendering (10px small text, 12 languages, 20+ fonts), flat $0.035 at 1K or 2K — built for posters, web pages and UI mockups at volume. Pro (qwen3-image-pro) is the higher-fidelity tier: micro-expressions, pores and hair strands near real photography, 1K $0.037 / 2K $0.075 — for hero shots, portraits and layouts that need the extra detail.
Per image by resolution, pay-as-you-go: standard is $0.035 at both 1K and 2K; each reference image (for editing) adds $0.004. Failures are never charged. Example: a 1K text-to-image is $0.035; editing with one reference image is $0.035 + $0.004 = $0.039.
Put reference images in image_urls and the backend routes to image-to-image automatically. Pass several to swap elements, change style, or repaint while keeping the subject. Omit image_urls for pure text-to-image. One model name, both modes — no endpoint switching.
This is one of its standout strengths: up to 4.5k-token prompts and dense in-image layout let it generate newspapers, storyboards, menus and exam sheets in a single pass, with 10px small text rendered legibly. 12 languages and 20+ fonts render natively, so infographics and UI mockups are usable straight out — no post-hoc text overlays.
Native rendering across 12 languages and 20+ fonts, with stable mixed-script and multilingual UI layouts. Prompts accept both Chinese and English. That makes it a good fit for multilingual marketing assets, educational content and web / game / livestream interface mockups.
1K or 2K, in eight aspect ratios: 1:1, 3:2, 2:3, 4:3, 3:4, 16:9, 9:16, 21:9. Output is PNG. Reference images are up to 10MB each, in common formats (jpeg / png / webp).
Up to 3. Multiple references support multi-image fusion or tighter constraints when editing. Each reference image costs $0.004, so fusing three 1K images is $0.035 + 3×$0.004 = $0.047.
Async: create a task, get a taskId, and poll — or pass a callBackUrl for a completion webhook. Results are transloaded to our own storage and returned as stable download links.
Qwen Image 3.0 leads on dense in-image text, multilingual typesetting and structured layouts (newspapers / menus / UI / exam sheets), at a lower price (from $0.035). gpt-image-2 is stronger on general in-image text and native 4K. Nano Banana (Gemini) is handy for realistic portraits and fast iteration. For text-dense, layout-heavy, multilingual work, reach for Qwen Image 3.0.
Sign up at apimodels.app, grab one API key, set model to qwen3-image — the same key also calls image, video, LLM and audio models. No juggling multiple providers or separate accounts; failures are never charged, billing is per image with no monthly fee.
Measured percentiles from our own production traffic: the standard tier has a median of 73s, with 90% finishing inside 96s and the fastest seen at 36s. A 3-minute polling window is plenty. If you cut the client request off after a few tens of seconds, the "stuck" task you see is your own timeout — the job is still running on our side and polling will flip state to completed. A genuine problem shows up as state=failed with a reason in failMsg.
No charge. Only state=completed is billed; a failed task costs nothing and you can retry the exact same request. The most common failure is an upstream busy signal (UPSTREAM_BUSY), which usually clears on retry. Content-moderation and invalid-parameter failures will not improve on retry — change the prompt or the parameters instead.
Result files are kept for 7 days and then deleted automatically. Download and re-host them yourself if you need them longer — do not treat our URLs as permanent image hosting in your own database or pages.
Neither, to be blunt. No Qwen Image 3.0 tier goes above 2K — for native 4K use gpt-image-2 ($0.05 per 4K image). There is also no mask/inpainting parameter: the way to edit a region is to pass the original through image_urls and describe the change in the prompt. It follows that kind of instruction well, but it is not pixel-level mask control.
Same model, different name. Our model string is qwen3-image (or qwen3-image-pro), which maps to Alibaba's qwen-image-3.0 and qwen-image-3.0-pro. Send ours, with no prefix.
Legible is not the same as character-accurate. The small text it renders really is sharp, but spelling, formulas, prices, barcodes and dates — anything where one wrong character matters — need a human pass before you ship. Use it as a typesetting capability, not as a text-entry tool.
Na APIMODELS, o Qwen Image 3.0 roda junto com mais de 60 modelos usando uma única chave de API e um único saldo, então escolher é questão de adequação, não de dependência. Ele suporta Text to Image, Image Editing, Dense Text Layout, 12 Languages, 20+ Fonts, 1K/2K, Async e você pode avaliá-lo em preço e capacidade frente a outros modelos de geração de imagens, trocando ao alterar uma única string com o nome do modelo — sem nova conta ou integração. Veja todas as opções de geração de imagens com preços ao vivo em apimodels.app/models.
O Qwen Image 3.0 suporta: Text to Image, Image Editing, Dense Text Layout, 12 Languages, 20+ Fonts, 1K/2K, Async. Consulte a documentação da APIMODELS para todos os parâmetros e exemplos de chamada.
Sim. A APIMODELS expõe o Qwen Image 3.0 por uma única API unificada e uma só chave, sem contas separadas por provedor e sem precisar lidar com o acesso de rede regional de cada provedor.
Aceitamos Stripe (Visa, Mastercard e outros cartões internacionais) e Alipay. O saldo fica disponível imediatamente após o pagamento.
Prompts shared by their authors — copy and adapt them. Each one credits its author and links back to the original post.
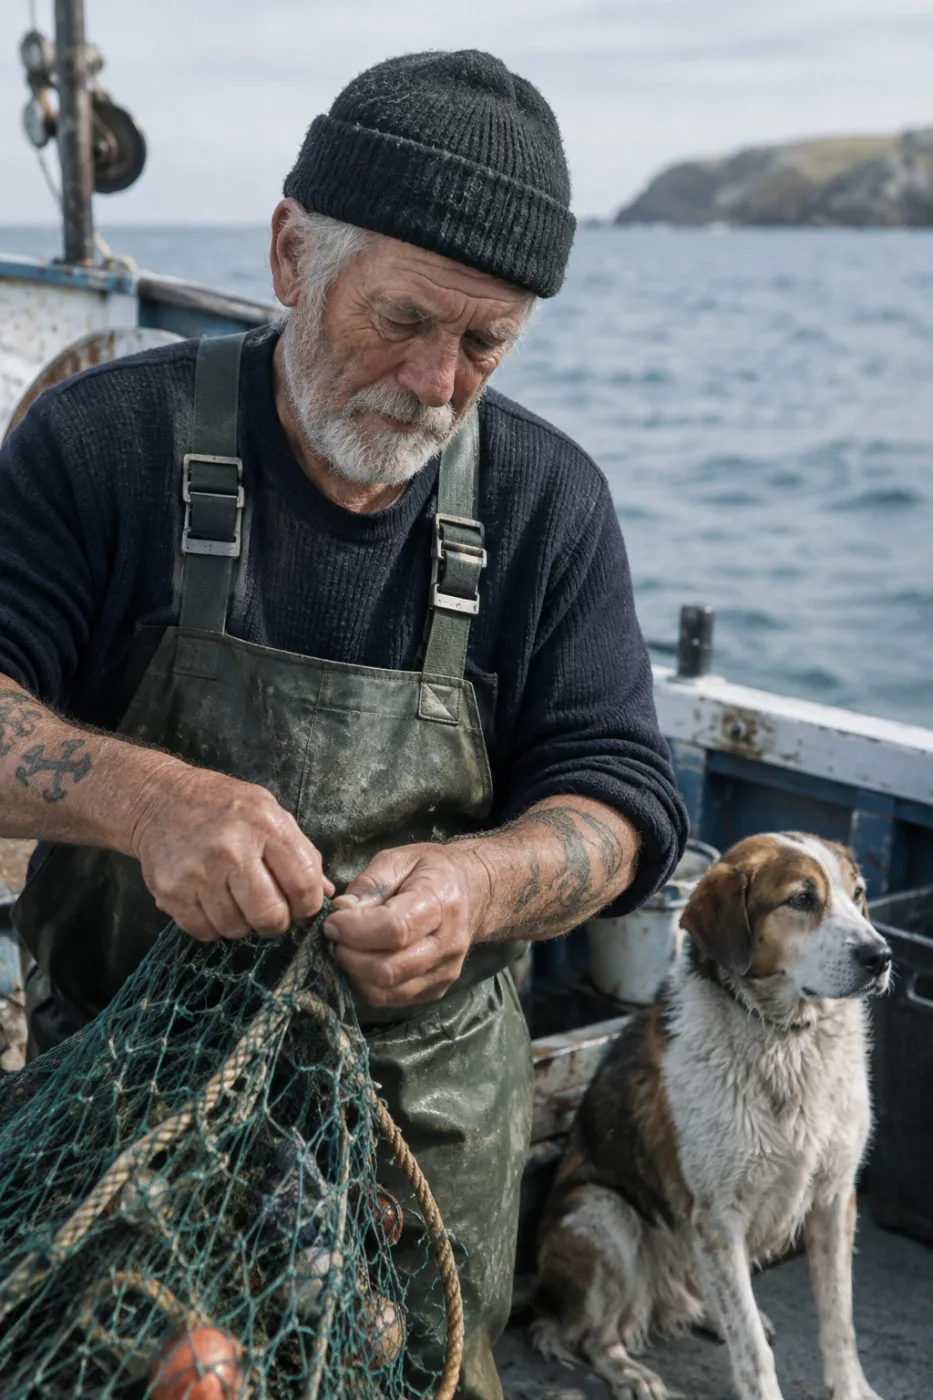
Weathered sailor on a fishing boat
Create a photorealistic candid photograph of an elderly sailor standing on a small fishing boat. He has weathered skin with visible wrinkles, pores, and sun texture, and a few faded traditional sailor tattoos on his arms. He is calmly adjusting a net while his dog sits nearby on the deck. Shot like a 35mm film photograph, medium close-up at eye level, using a 50mm lens. Soft coastal daylight, shallow depth of field, subtle film grain, natural color balance. The image should feel honest and unposed, with real skin texture, worn materials, and everyday detail. No glamorization, no heavy retouching.
by OpenAI
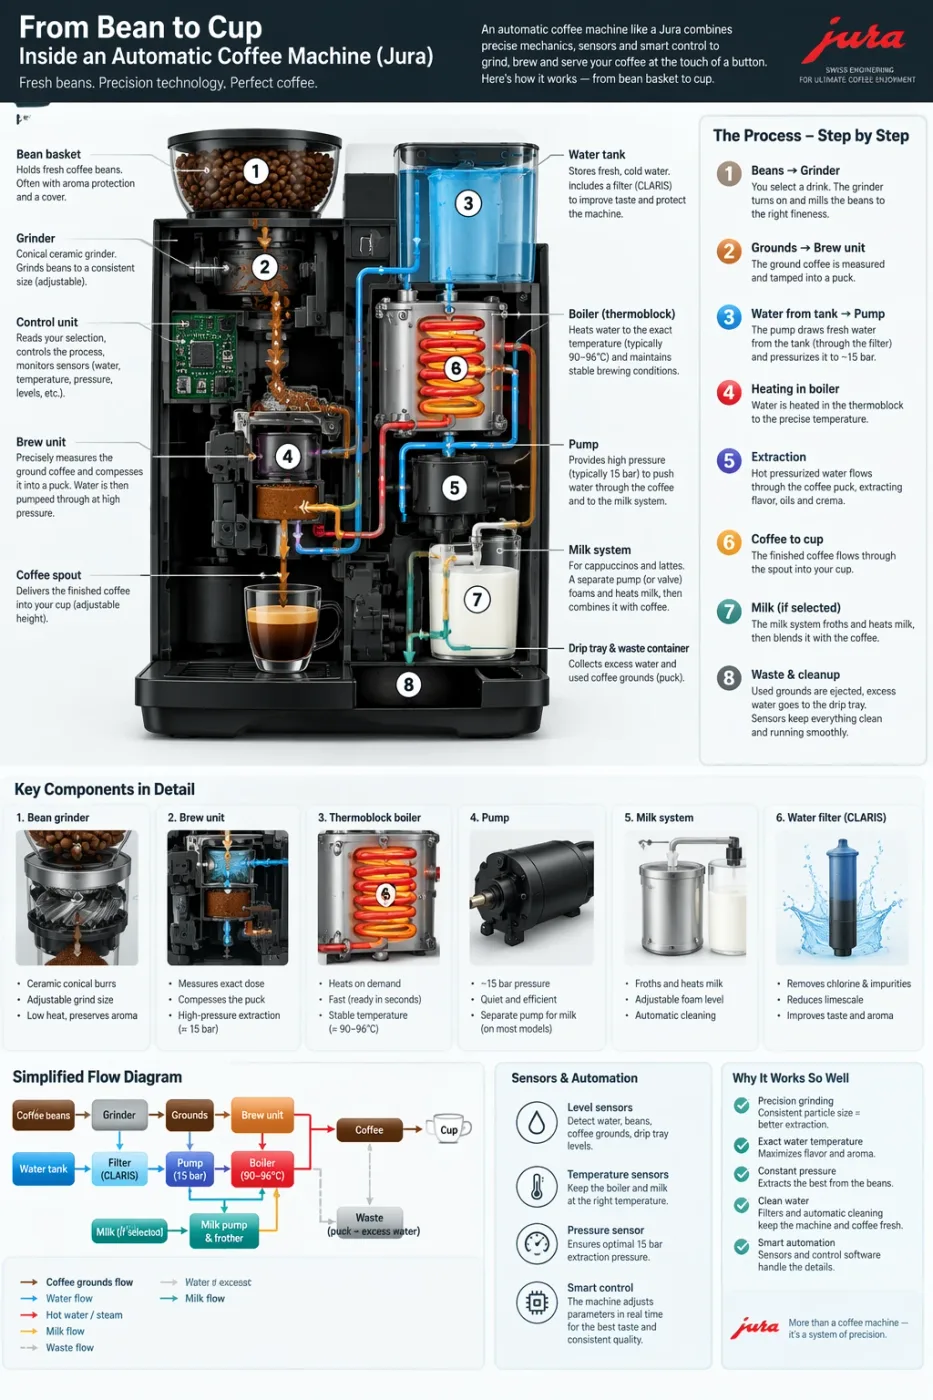
Automatic coffee machine workflow infographic
Create a detailed Infographic of the functioning and flow of an automatic coffee machine like a Jura. From bean basket, to grinding, to scale, water tank, boiler, etc. I'd like to understand technically and visually the flow.
by OpenAI
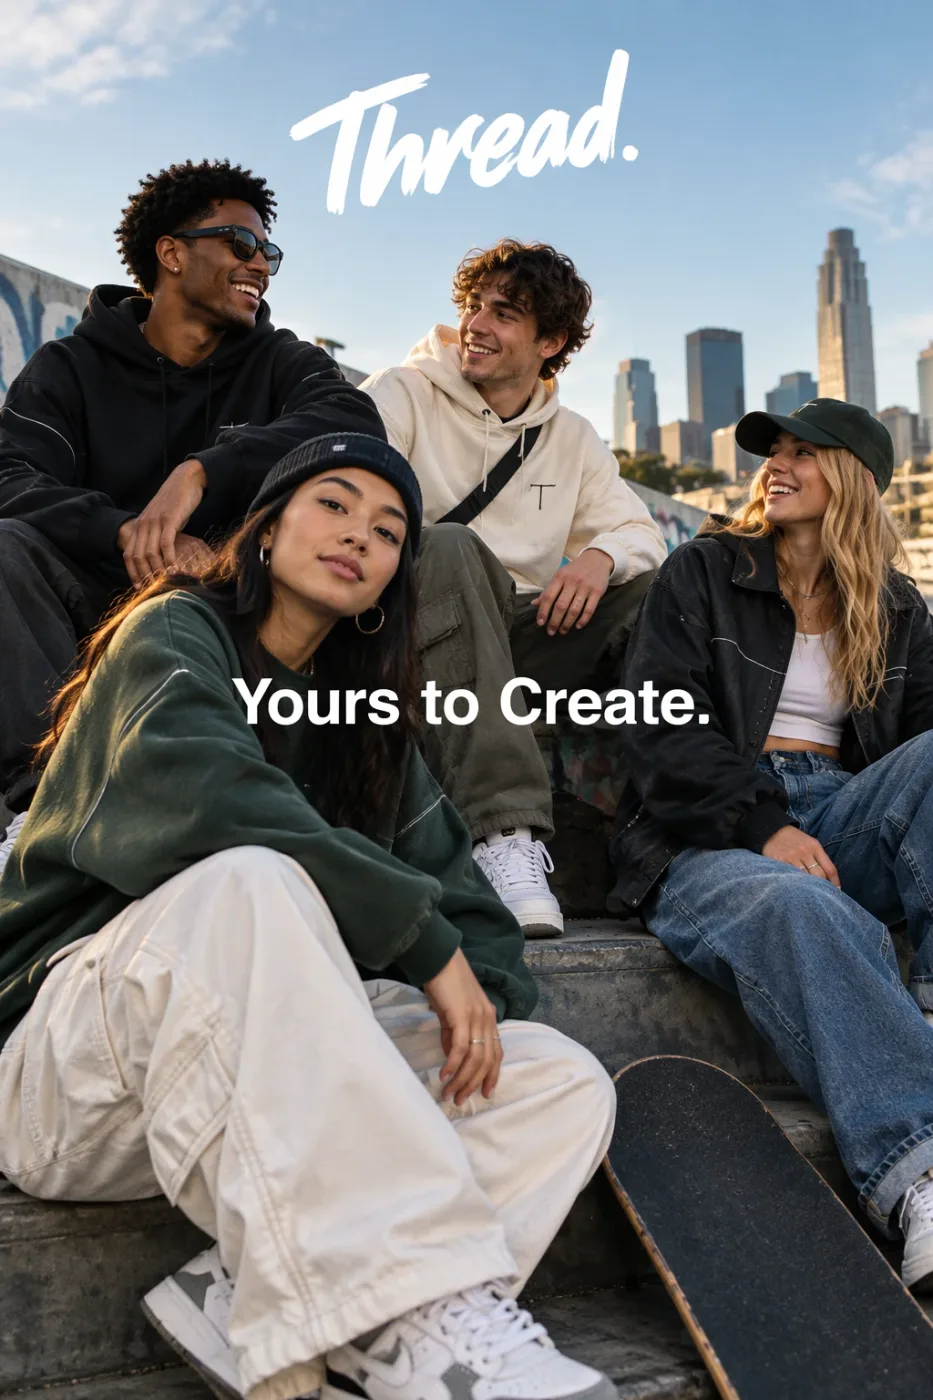
Thread streetwear ad with exact typography
Give me a cool in culture ad / fashion shot for a brand called Thread. It's a hip young street brand. The ad shows a group of friends hanging out together with the tagline "Yours to Create." Make it feel like a polished campaign image for a youth streetwear audience: stylish, contemporary, energetic, and tasteful. Use clean composition, strong color direction, natural poses, and premium fashion photography cues. Render the tagline exactly once, clearly and legibly, integrated into the ad layout. No extra text, no watermarks, no unrelated logos.
by OpenAI
We curate copy-ready prompt libraries — every entry shows its full text and a sample result, ready to adapt.
How to get access, regional availability, and how this model compares with its alternatives.
