qwen3-imageAlibaba Qwen Image 3.0 — text-to-image and image editing in one model, chosen automatically by whether the request carries reference images. Prompts up to 4.5k tokens with dense in-image text layout, 10px small-text rendering, 12 languages and 20+ native fonts. Output 1K or 2K in eight aspect ratios (1:1, 3:2, 2:3, 4:3, 3:4, 16:9, 9:16, 21:9), PNG. Flat $0.035 per image at either resolution; each reference image adds $0.004. Async — create then poll.
Generated image will appear here
Enter a prompt and click Generate
Text-to-image and image editing on one model name — add reference images and it edits, omit them and it generates
Up to 4.5k-token prompts and 10px small-text rendering — newspapers, storyboards, menus and exam sheets in a single pass
Native multilingual and multi-font rendering, legible for infographics and UI mockups straight out
$0.035 per image at 1K or 2K; each reference image adds $0.004. Failures are never charged
High-volume posters, web and UI layouts, and text-heavy designs where small type must stay legible
Qwen Image 3.0은(는) Alibaba의 이미지 생성 API입니다. Alibaba Qwen Image 3.0 — text-to-image and image editing in one model, chosen automatically by whether the request carries reference images. Prompts up to 4.5k tokens with dense in-image text layout, 10px small-text rendering, 12 languages and 20+ native fonts. Output 1K or 2K in eight aspect ratios (1:1, 3:2, 2:3, 4:3, 3:4, 16:9, 9:16, 21:9), PNG. Flat $0.035 per image at either resolution; each reference image adds $0.004. Async — create then poll. APIMODELS 플랫폼을 거치면 통합 API와 투명한 종량 과금으로 이 모델을 호출할 수 있습니다. 현재 가격: 1K: $0.035, 2K: $0.035.
관련 모델: qwen3-image-pro — the higher-fidelity tier of the same model — micro-expressions, pores and hair strands near real photography, 1K $0.037 / 2K $0.075
관련 모델: gpt-image-2 — stronger on general in-image text and the only one here with native 4K — 1K $0.025, 2K $0.03, 4K $0.05
관련 모델: nanobananapro — Gemini 3 Pro Image — reach for it when the subject is a realistic portrait rather than a text-heavy layout
Up to 4.5k-token prompts and 10px small-text rendering — newspapers, storyboards, menus and exam sheets generate as one structured layout, not a picture with text pasted on.
Native multilingual and multi-font rendering, so infographics, UI mockups and multilingual marketing assets come out legible and usable straight away.
Understands complex instructions and organizes many elements into web pages, dashboards, game and livestream UIs in a single pass.
Pass reference images in image_urls and it edits — swap elements, restyle, or repaint while keeping the subject; omit them for pure text-to-image. One model, both modes.
Flat $0.035 per image at 1K and 2K, plus $0.004 per reference image. Failures are never charged, and one apimodels.app key also calls image, video, LLM and audio.
Qwen Image 3.0은(는) APIMODELS를 통해 1K: $0.035, 2K: $0.035에 이용할 수 있습니다. 과금은 종량제라서 생성한 만큼만 냅니다.
APIMODELS에 가입해 API 키를 받고 통합 엔드포인트를 호출하면 됩니다. cURL / Python / Node.js 예제를 담은 상세 문서를 제공합니다.
APIMODELS는 같은 Qwen Image 3.0을(를) 집약 플랫폼을 통해 제공합니다. API 인터페이스가 통합되어 있어 공급자마다 계정을 만들 필요가 없고, 키 하나로 모든 모델에 닿습니다.
Qwen Image 3.0 is Alibaba's image generation model, strong at realistic images, structured layouts, dense in-image text and high-quality typography. On apimodels.app text-to-image and image editing are one model, chosen automatically by whether you pass reference images — omit them and it generates, include them and it edits. 1K/2K, flat $0.035 per image, plus $0.004 per reference image.
Standard Qwen Image 3.0 is the everyday tier: clear instruction following (prompts up to 4.5k tokens), stable text rendering (10px small text, 12 languages, 20+ fonts), flat $0.035 at 1K or 2K — built for posters, web pages and UI mockups at volume. Pro (qwen3-image-pro) is the higher-fidelity tier: micro-expressions, pores and hair strands near real photography, 1K $0.037 / 2K $0.075 — for hero shots, portraits and layouts that need the extra detail.
Per image by resolution, pay-as-you-go: standard is $0.035 at both 1K and 2K; each reference image (for editing) adds $0.004. Failures are never charged. Example: a 1K text-to-image is $0.035; editing with one reference image is $0.035 + $0.004 = $0.039.
Put reference images in image_urls and the backend routes to image-to-image automatically. Pass several to swap elements, change style, or repaint while keeping the subject. Omit image_urls for pure text-to-image. One model name, both modes — no endpoint switching.
This is one of its standout strengths: up to 4.5k-token prompts and dense in-image layout let it generate newspapers, storyboards, menus and exam sheets in a single pass, with 10px small text rendered legibly. 12 languages and 20+ fonts render natively, so infographics and UI mockups are usable straight out — no post-hoc text overlays.
Native rendering across 12 languages and 20+ fonts, with stable mixed-script and multilingual UI layouts. Prompts accept both Chinese and English. That makes it a good fit for multilingual marketing assets, educational content and web / game / livestream interface mockups.
1K or 2K, in eight aspect ratios: 1:1, 3:2, 2:3, 4:3, 3:4, 16:9, 9:16, 21:9. Output is PNG. Reference images are up to 10MB each, in common formats (jpeg / png / webp).
Up to 3. Multiple references support multi-image fusion or tighter constraints when editing. Each reference image costs $0.004, so fusing three 1K images is $0.035 + 3×$0.004 = $0.047.
Async: create a task, get a taskId, and poll — or pass a callBackUrl for a completion webhook. Results are transloaded to our own storage and returned as stable download links.
Qwen Image 3.0 leads on dense in-image text, multilingual typesetting and structured layouts (newspapers / menus / UI / exam sheets), at a lower price (from $0.035). gpt-image-2 is stronger on general in-image text and native 4K. Nano Banana (Gemini) is handy for realistic portraits and fast iteration. For text-dense, layout-heavy, multilingual work, reach for Qwen Image 3.0.
Sign up at apimodels.app, grab one API key, set model to qwen3-image — the same key also calls image, video, LLM and audio models. No juggling multiple providers or separate accounts; failures are never charged, billing is per image with no monthly fee.
Measured percentiles from our own production traffic: the standard tier has a median of 73s, with 90% finishing inside 96s and the fastest seen at 36s. A 3-minute polling window is plenty. If you cut the client request off after a few tens of seconds, the "stuck" task you see is your own timeout — the job is still running on our side and polling will flip state to completed. A genuine problem shows up as state=failed with a reason in failMsg.
No charge. Only state=completed is billed; a failed task costs nothing and you can retry the exact same request. The most common failure is an upstream busy signal (UPSTREAM_BUSY), which usually clears on retry. Content-moderation and invalid-parameter failures will not improve on retry — change the prompt or the parameters instead.
Result files are kept for 7 days and then deleted automatically. Download and re-host them yourself if you need them longer — do not treat our URLs as permanent image hosting in your own database or pages.
Neither, to be blunt. No Qwen Image 3.0 tier goes above 2K — for native 4K use gpt-image-2 ($0.05 per 4K image). There is also no mask/inpainting parameter: the way to edit a region is to pass the original through image_urls and describe the change in the prompt. It follows that kind of instruction well, but it is not pixel-level mask control.
Same model, different name. Our model string is qwen3-image (or qwen3-image-pro), which maps to Alibaba's qwen-image-3.0 and qwen-image-3.0-pro. Send ours, with no prefix.
Legible is not the same as character-accurate. The small text it renders really is sharp, but spelling, formulas, prices, barcodes and dates — anything where one wrong character matters — need a human pass before you ship. Use it as a typesetting capability, not as a text-entry tool.
APIMODELS에서는 Qwen Image 3.0이(가) 60개가 넘는 모델과 같은 API 키, 같은 잔액 위에 나란히 놓입니다. 그래서 선택은 궁합의 문제이지 종속의 문제가 아닙니다. Text to Image、Image Editing、Dense Text Layout、12 Languages, 20+ Fonts、1K/2K、Async을(를) 지원하며 다른 이미지 생성 모델과 가격·성능을 나란히 놓고 따져볼 수 있습니다. 갈아타기는 모델 이름 문자열 하나만 바꾸면 되고 새 계정도 추가 작업도 필요 없습니다. 이미지 생성 선택지와 실시간 가격은 apimodels.app/models에서 볼 수 있습니다.
Qwen Image 3.0은(는) 다음을 지원합니다: Text to Image、Image Editing、Dense Text Layout、12 Languages, 20+ Fonts、1K/2K、Async. 전체 파라미터와 호출 예제는 APIMODELS 문서를 참고하세요.
네. APIMODELS는 Qwen Image 3.0을(를) 하나의 통합 API와 키 한 개로 제공합니다. 공급자별 계정도 필요 없고, 각 공급자의 지역별 네트워크 경로를 직접 챙길 필요도 없습니다.
Stripe(Visa, Mastercard 등 해외 카드)와 Alipay를 지원합니다. 결제 후 잔액은 즉시 반영됩니다.
Prompts shared by their authors — copy and adapt them. Each one credits its author and links back to the original post.
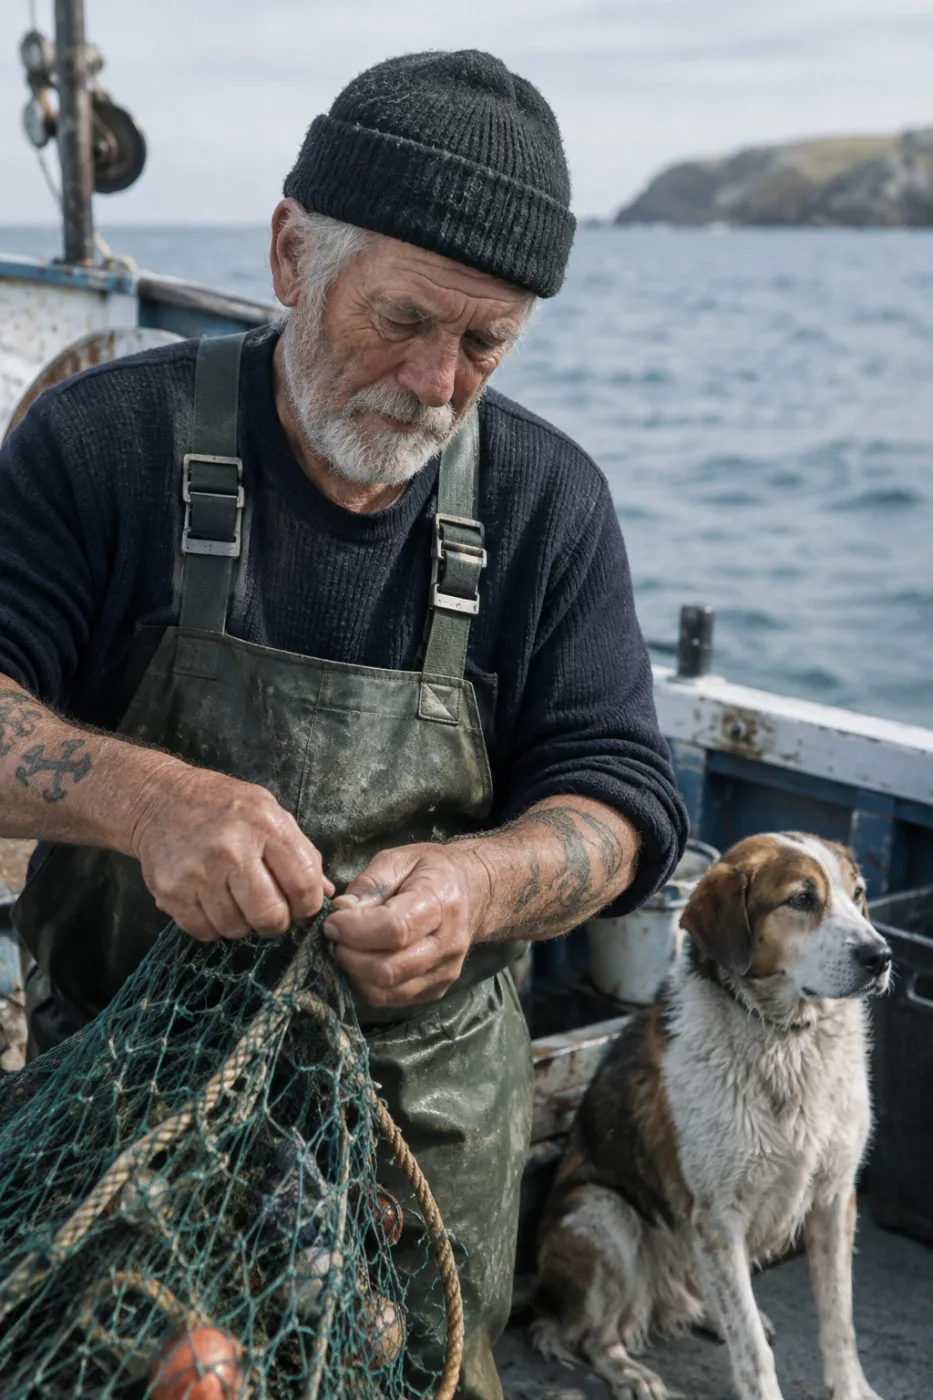
Weathered sailor on a fishing boat
Create a photorealistic candid photograph of an elderly sailor standing on a small fishing boat. He has weathered skin with visible wrinkles, pores, and sun texture, and a few faded traditional sailor tattoos on his arms. He is calmly adjusting a net while his dog sits nearby on the deck. Shot like a 35mm film photograph, medium close-up at eye level, using a 50mm lens. Soft coastal daylight, shallow depth of field, subtle film grain, natural color balance. The image should feel honest and unposed, with real skin texture, worn materials, and everyday detail. No glamorization, no heavy retouching.
by OpenAI
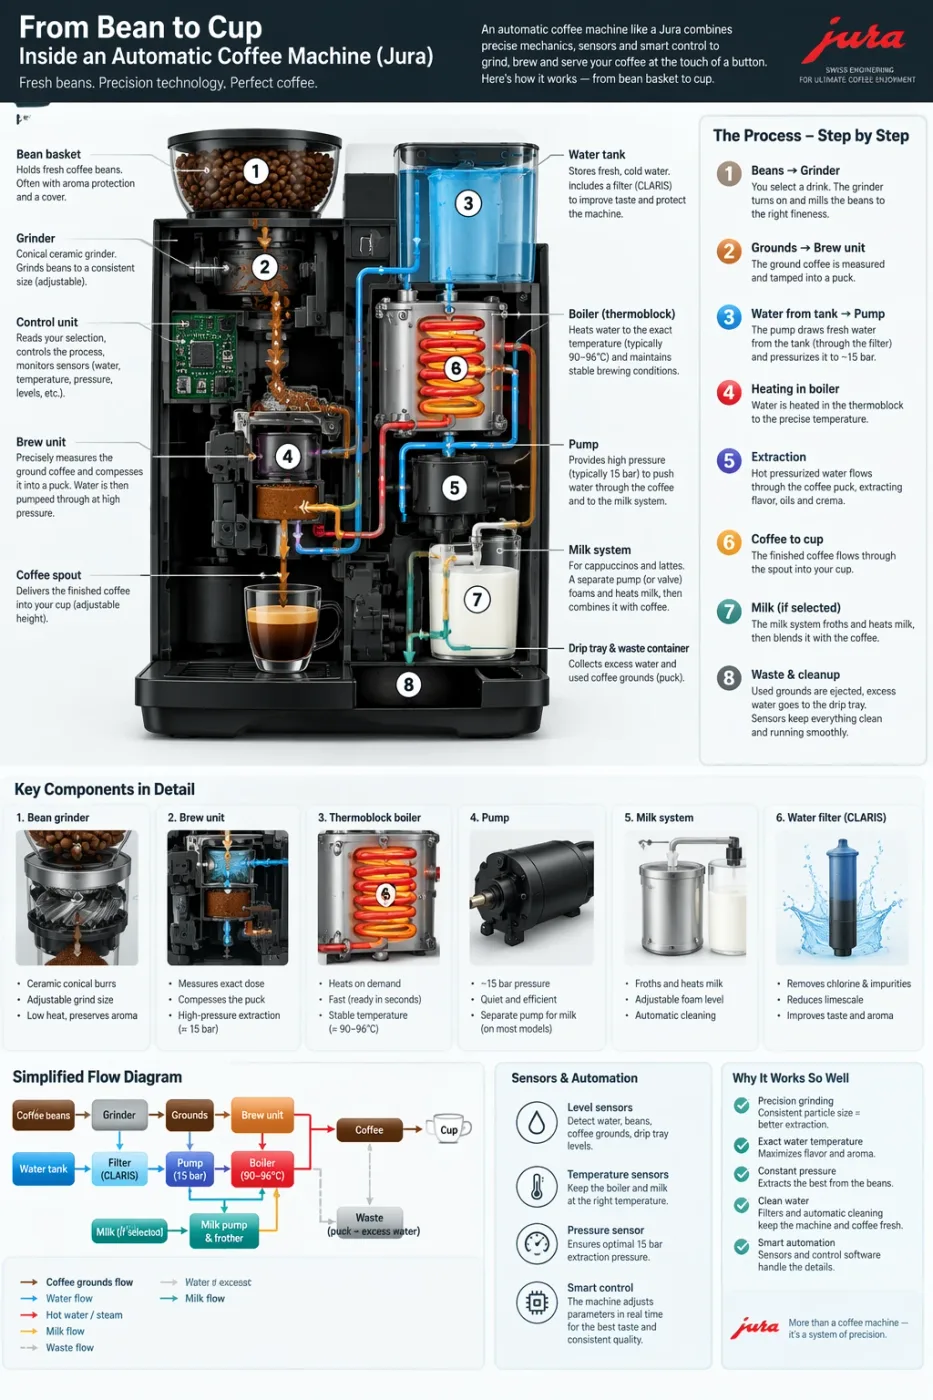
Automatic coffee machine workflow infographic
Create a detailed Infographic of the functioning and flow of an automatic coffee machine like a Jura. From bean basket, to grinding, to scale, water tank, boiler, etc. I'd like to understand technically and visually the flow.
by OpenAI
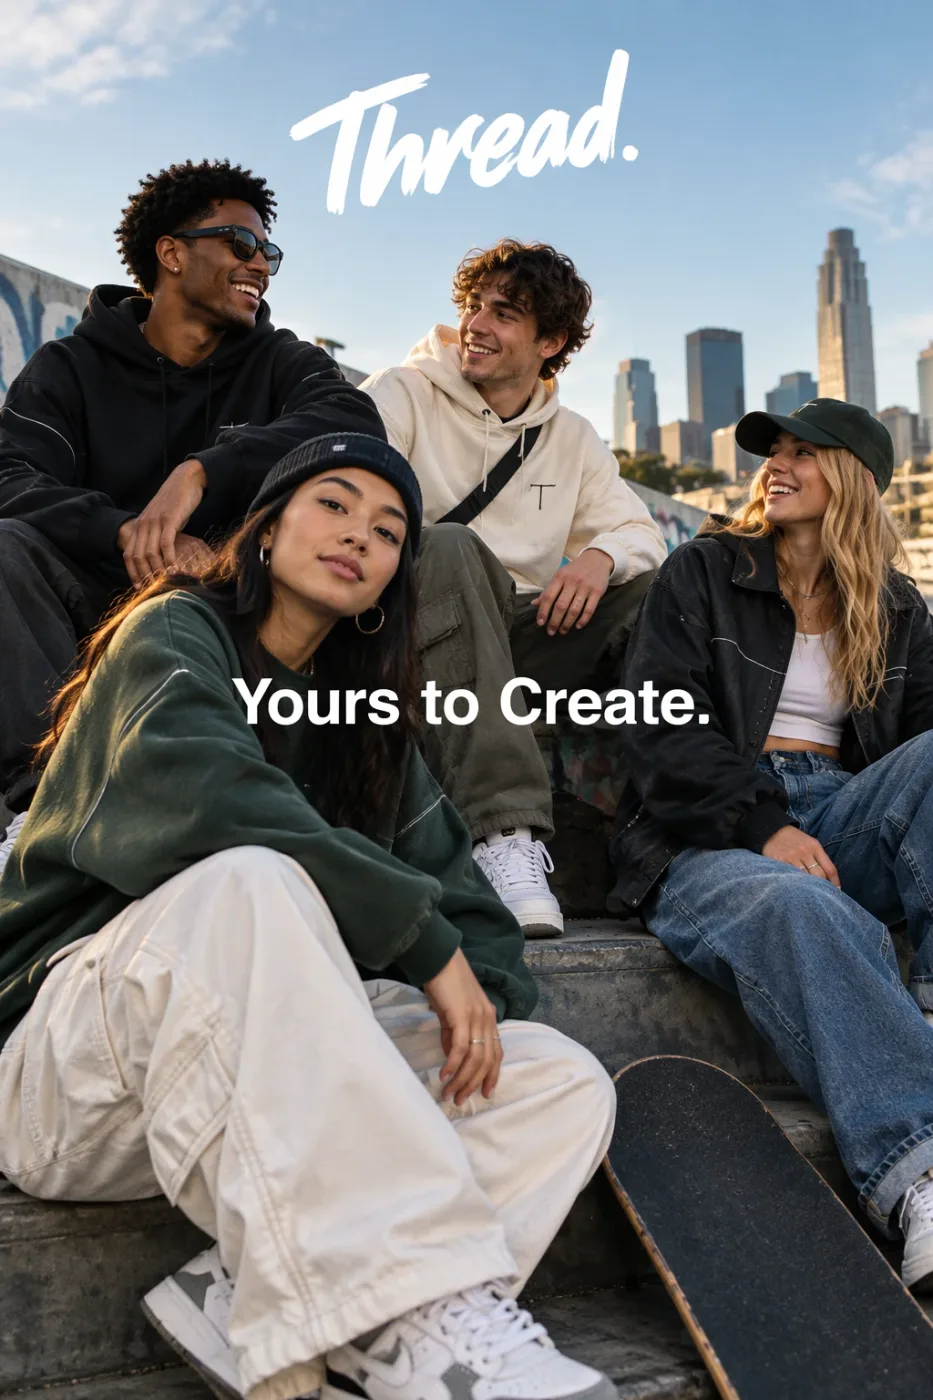
Thread streetwear ad with exact typography
Give me a cool in culture ad / fashion shot for a brand called Thread. It's a hip young street brand. The ad shows a group of friends hanging out together with the tagline "Yours to Create." Make it feel like a polished campaign image for a youth streetwear audience: stylish, contemporary, energetic, and tasteful. Use clean composition, strong color direction, natural poses, and premium fashion photography cues. Render the tagline exactly once, clearly and legibly, integrated into the ad layout. No extra text, no watermarks, no unrelated logos.
by OpenAI
We curate copy-ready prompt libraries — every entry shows its full text and a sample result, ready to adapt.
How to get access, regional availability, and how this model compares with its alternatives.
