gpt-image-2OpenAI의 GPT Image 2 API——최대 16장의 참조 이미지를 이용한 텍스트-이미지 생성과 이미지 편집을 지원하며, 네이티브 1K / 2K / 4K를 장당 $0.025 / $0.03 / $0.05에 제공합니다. 하나의 API Key로 직접 이용보다 훨씬 저렴하고, OpenAI 조직 인증도 필요 없으며, 어디서든 즉시 접근할 수 있습니다.
Auto follows your reference image when editing. With text-to-image there is nothing to follow, so it renders square (1:1) — pick a ratio here if you want a shape. Widest available is 21:9; asking for a ratio in the prompt has no effect.
Generated image will appear here
Enter a prompt and click Generate
최근 30일 실측 기준, 이 채널에서 상위 안전 시스템에 거부된 요청은 0.93%였고 gpt-image-2-all은 8.0%였습니다. 밑단은 같은 모델이고 심사 기준만 다릅니다. 저쪽에서 계속 막히는 프롬프트라면 여기부터 시도해 보세요. 거부된 요청은 과금되지 않습니다
API 키 하나로 GPT Image 2를 호출합니다. OpenAI 조직 인증도, 신원 확인도, 대기자 명단도 없고 중국 본토를 포함해 어디서든 연결됩니다
OpenAI의 최신 이미지 모델로, 프롬프트 반영도가 동급 최고 수준입니다
요청당 참조 이미지 최대 16장
1:1, 2:3, 3:2, 4:5, 5:4, 4:3, 3:4, 16:9, 9:16, 21:9 (5:4와 4:5는 1K에서만)
1K / 2K / 4K에 각각 $0.025 / $0.03 / $0.05 (medium 품질). low와 high 품질 등급도 쓸 수 있습니다
여러 상위 채널로 자동 장애 조치해 가용성을 지킵니다
작업 엔드포인트를 폴링해 결과를 받습니다. 보통 40-90초
GPT Image 2은(는) OpenAI의 이미지 생성 API입니다. OpenAI의 GPT Image 2 API——최대 16장의 참조 이미지를 이용한 텍스트-이미지 생성과 이미지 편집을 지원하며, 네이티브 1K / 2K / 4K를 장당 $0.025 / $0.03 / $0.05에 제공합니다. 하나의 API Key로 직접 이용보다 훨씬 저렴하고, OpenAI 조직 인증도 필요 없으며, 어디서든 즉시 접근할 수 있습니다. APIMODELS 플랫폼을 거치면 통합 API와 투명한 종량 과금으로 이 모델을 호출할 수 있습니다. 현재 가격: 1K: $0.025, 2K: $0.03, 4K: $0.05.
관련 모델: gpt-image-2-all — same model, but you pick the quality tier — low / medium / high × 1K/2K/4K, and OpenAI-SDK compatible (images.generate / images.edit) so Codex and Cursor can call it directly
Posters, ad creatives, covers and packaging where the words are part of the artwork — this is the most reliable in-image text renderer we carry, so headlines come out set, not smeared.
Pass up to 16 reference images to hold a character, product or style steady across a whole batch, instead of re-rolling until two frames happen to match.
Change a background, recolor, swap an element — the rest of the frame stays where it was. Editing is a first-class path here, not a prompt trick.
1K, 2K and 4K come out of the model at that resolution — nothing is upscaled after the fact, so fine detail and small type survive at $0.05 for 4K.
Price depends on resolution alone ($0.025 / $0.03 / $0.05); quality never moves it. Multiply images by tier and you have the exact spend before the first call.
GPT Image 2은(는) APIMODELS를 통해 1K: $0.025, 2K: $0.03, 4K: $0.05에 이용할 수 있습니다. 과금은 종량제라서 생성한 만큼만 냅니다.
APIMODELS에 가입해 API 키를 받고 통합 엔드포인트를 호출하면 됩니다. cURL / Python / Node.js 예제를 담은 상세 문서를 제공합니다.
APIMODELS는 같은 GPT Image 2을(를) 집약 플랫폼을 통해 제공합니다. API 인터페이스가 통합되어 있어 공급자마다 계정을 만들 필요가 없고, 키 하나로 모든 모델에 닿습니다.
OpenAI의 차세대 이미지 모델입니다. 이미지 내 타이포그래피가 더 선명해지고, 픽셀 단위 편집이 더 안정적이며, 세계 지식도 강화되었습니다. 생성 속도가 빠르고 프롬프트 충실도도 높은 것이 특징입니다.
네. apimodels.app에 가입해 API Key를 발급받으면 바로 gpt-image-2를 호출할 수 있습니다($0.025/장부터, 1K/2K/4K 단계별: $0.025/$0.03/$0.05, 요청당 최대 16장의 참조 이미지 지원).
둘 다 지원합니다. 단일 엔드포인트가 참조 이미지 유무에 따라 자동으로 라우팅합니다. 종횡비로 출력 구도를 제어하며, 한 번의 요청에서 최대 16장의 참조 이미지를 합성할 수 있습니다.
이커머스 상품 이미지 편집, 마케팅 비주얼 일괄 생성, AI 이미지 생성기 / 편집기 SaaS, 디자인 시스템의 생산 레이어, 다국어 현지화 비주얼, 교육 콘텐츠용 일러스트, 그리고 텍스트와 이미지를 시각적 결과물로 바꾸는 모든 워크플로에 활용할 수 있습니다.
네. 다국어 텍스트 렌더링은 핵심 개선 항목 중 하나입니다. 다중 피사체 프롬프트와 계층적 장면에 대한 지시 이행력 향상과 맞물려 복잡한 레이아웃과 이미지 내 텍스트가 눈에 띄게 깔끔하게 나옵니다.
네. gpt-image-2는 요청당 최대 16장의 참조 이미지를 지원하여 룩북 생성, 모델 가상 착용, 패키지 합성 등 다중 참조가 필요한 시나리오에 적합합니다.
하나의 API Key로 모든 모델을 이용할 수 있고, cURL / Python / Node.js 예제가 포함된 완전한 API 문서, 실패 시 무과금, 결과물의 R2 호스팅, 그리고 여러 상류 채널 간 자동 페일오버로 안정성을 확보합니다.
apimodels.app에서 gpt-image-2는 해상도별 단계 요금제로, 1K / 2K / 4K가 $0.025 / $0.03 / $0.05입니다. 최소 사용액도 월 요금도 없고 실패 시 과금되지 않습니다. 덕분에 GPT Image 2 API를 호출하는 가장 저렴한 방법 중 하나입니다.
https://api.apimodels.app/v1/images/generations로 POST하고, 헤더에 Authorization: Bearer <your API key>를 넣습니다. JSON 본문에서 model을 "gpt-image-2"로 설정하고 prompt를 지정합니다. 편집 시에는 image_url(단일) 또는 image_urls(최대 16장)를 추가하세요. 복사해서 바로 쓸 수 있는 curl과 Python(requests / OpenAI SDK 호환 방식) 예제는 모델 페이지 문서에 있습니다.
동일한 OpenAI gpt-image-2 모델이므로 화질은 같습니다. 차이는 접근 방식에 있습니다. apimodels.app을 통하면 하나의 API Key로 $0.025/장부터(해상도별 단계제) 사용할 수 있고, OpenAI 조직 인증(org verification)도 필요 없으며, 어디서든 접근할 수 있습니다. OpenAI를 직접 연결하는 것보다 저렴하고 간편합니다.
네. apimodels.app에 가입하면 하나의 API Key가 생깁니다. OpenAI 계정이나 조직 인증이 필요 없고, 엔드포인트는 중국을 포함한 어디에서든 접근 가능합니다. 생성된 이미지는 당사 R2에 호스팅되어 바로 다운로드할 수 있습니다.
gpt-image-2는 요청당 최대 16장의 참조 이미지를 사용한 멀티 이미지 합성·편집을 지원하고, 출력은 1K / 2K / 4K, 화질은 low / medium / high 3단계(기본값 medium)입니다. 종횡비(1:1, 2:3, 3:2, 4:5, 16:9, 9:16 등. 5:4와 4:5는 1K 전용으로 2K/4K에서는 미지원)로 구도를 제어할 수 있습니다. 요금은 해상도 × 화질에 따른 단계제이며, medium은 1K / 2K / 4K가 $0.025 / $0.03 / $0.05입니다.
고를 수 없습니다. 항상 medium 등급으로 동작하며 quality 필드를 보내도 아무 효과가 없습니다. 의도한 설계입니다. 모델 이름 하나, 해상도 파라미터 하나로 정할 것이 하나 줄고, 요금은 해상도만으로 결정됩니다(1K / 2K / 4K가 $0.025 / $0.03 / $0.05). 화질을 직접 고르고 싶다면 gpt-image-2-all을 쓰세요. 속은 같은 모델이지만 해상도 × 화질의 전체 조합(1K/2K/4K × low/medium/high, 그리고 auto)이 그대로 열려 있습니다. 1K의 low는 $0.01이고, 디테일을 최대로 뽑고 싶을 때는 high도 고를 수 있습니다. 이쪽은 OpenAI SDK 호환 동기 채널이기도 해서 Codex와 Cursor는 base_url만 바꾸면 호출할 수 있습니다. 링크는 이 페이지 아래쪽 관련 모델에 있습니다.
최근 30일 외부 프로덕션 트래픽 24,208건 기준 **인프라 성공률은 98.9%**입니다. 여기에는 저희가 고쳐야 할 실패만 들어갑니다. 타임아웃 119건, 업스트림 혼잡 66건, 업스트림이 이미지를 반환하지 않은 경우 15건으로 모두 200건입니다. OpenAI 콘텐츠 정책 거부와 잘못된 입력은 제외했습니다. 프롬프트나 파라미터를 고치면 통과하고, 애초에 과금되지도 않기 때문입니다. 정리하면, 프롬프트가 OpenAI 콘텐츠 정책을 통과한다면 이미지는 안정적으로 전달됩니다. 짚고 넘어갈 점이 있습니다. **이 업계에서 성공률을 공개하는 곳은 사실상 없습니다.** 다른 API 페이지에 적힌 것은 「안정적」「고가용성」처럼 확인할 방법이 없는 형용사뿐입니다. 저희는 30일치 실제 수치를 계산 방식과 함께 공개합니다. 같은 질문을 어느 업체에나 그대로 해 보셔도 됩니다.
30일간 프로덕션 실측으로 중앙값 60초, p95는 157초입니다. 절반은 1분 안에, 95%는 2분 30초 안에 돌아옵니다. 동기 방식(`size`를 넘기고 `callback_url`은 넘기지 않음)은 이미지가 준비될 때까지 연결을 유지합니다. 긴 연결을 들고 있기 싫다면 태스크 방식으로 폴링하거나 `callback_url`을 쓰세요. 클라이언트 타임아웃은 180초보다 길게 잡아 두시기 바랍니다.
실패는 절대 과금되지 않습니다. 타임아웃도, 업스트림 혼잡도, 콘텐츠 정책 거부도 비용이 0이고 실제로 전달된 이미지에 대해서만 지불합니다. gpt-image-2와 gpt-image-2-all은 서로 다른 업스트림 어댑터를 타기 때문에 한쪽에 문제가 생겨도 다른 쪽은 멀쩡하고, 모델 이름만 바꿔 재시도할 수 있습니다. 크레딧은 미리 예약되었다가 작업이 실패하면 자동으로 반환됩니다.
구독도, 월 요금도, 최소 사용액도 없고 장당 과금입니다. 최소 충전은 $10이며 API 키 하나로 플랫폼의 모든 모델(이미지·영상·오디오·LLM이 같은 달러 잔액을 공유)을 쓸 수 있어 모델 공급사마다 계정을 열 필요가 없습니다. 일반 이메일 도메인으로 가입한 신규 계정에는 $0.10의 무료 크레딧이 지급되며, 기본 화질 1K 이미지 4장을 만들기에 충분합니다. 돈을 쓰기 전에 결과물 품질을 확인해 볼 수 있다는 뜻입니다. OpenAI 계정이나 조직 인증도 필요 없고, 중국 본토에서도 접속됩니다.
Stripe(카드), PayPal, Alipay를 지원합니다. **Stripe로 결제하면 결제 화면에서 법인의 세무 번호(EU VAT 등)를 입력할 수 있고, 결제 후 양측 세무 정보가 담긴 정식 인보이스 PDF가 자동 생성되어 이메일로 발송됩니다**. 번호는 저장되어 이후의 모든 인보이스에 자동으로 들어갑니다. PayPal은 세무 번호를 수집하지 않아 수동 발행이며, support@apimodels.app으로 회사명·주소·세무 번호를 보내 주세요. 판매 주체는 영국 법인이므로 EU 기업 대상 판매는 리버스 차지가 적용됩니다.
계정은 선불 잔액제입니다. 잔액이 바닥나면 호출이 계속 과금되는 대신 402를 반환하므로 상한이 단단하고 초과 지출이 생기지 않습니다. 여기에 잔액 부족 webhook(기준치 아래로 떨어지면 고객사 서비스로 알림)과 자동 충전(실패 횟수 카운트와 잠금이 있어 재시도가 폭주하지 않습니다)도 설정할 수 있습니다. 호출마다 실제 과금액, 입력 파라미터, 결과가 콘솔에 건별로 남기 때문에 월말에 대사할 일이 없습니다.
현실적인 통로는 셋입니다. OpenAI 공식 API(같은 정가의 Azure OpenAI 포함), APIMODELS 같은 독립 게이트웨이, 그리고 범용 애그리게이터입니다. 표시 가격 대신 네 가지를 보세요. ① **실제 성공률과 그 계산 방식** —— 분모에 콘텐츠 정책 거부가 들어가는지 물어보십시오. 두 정의는 비교 자체가 되지 않습니다. ② 실패에 과금하는지. ③ 요금이 예측 가능한지 —— 공식 API는 이미지를 출력 토큰으로 과금하므로 장당 비용이 숫자가 아니라 구간입니다. ④ 애초에 쓸 수 있는지 —— OpenAI는 이미지 모델을 조직 인증 뒤에 두고 있습니다. 저희 수치는 불리한 것까지 이 페이지에 적어 두었습니다. 같은 네 가지 질문을 어느 업체에나 해 보시면 됩니다.
이 모델에서는 가능합니다. 저렴함이 무언가를 낮춰서 얻은 것이 아니기 때문입니다. 결과물은 진짜 OpenAI 이미지 파이프라인에서 나오고, 저희는 그것을 장당 고정가(1K / 2K / 4K에 $0.025 / $0.03 / $0.05)로 매길 뿐입니다. 공식 API는 출력 토큰으로 과금해 기본 화질 1024x1024가 대략 $0.053입니다. 인프라 성공률은 98.9%이고 실패는 과금되지 않습니다. 진짜 트레이드오프는 다른 곳에 있습니다. 파이프라인이 픽셀 단위 크기를 보장받아야 하거나, DPA와 SOC 2 체인처럼 직접 계약에서만 나오는 컴플라이언스 문서가 필요하다면 공식으로 가십시오.
거부하는 쪽은 저희가 아니라 OpenAI의 콘텐츠 정책이며, 실무에서는 흔한 일입니다. 최근 30일 24,208건 중 6,007건이 여기에 걸렸고 **대략 네 번에 한 번**꼴입니다. 흔한 유발 요인은 실존 인물의 이름이나 외모, 브랜드와 저작권 있는 캐릭터, 폭력·성인 표현, 그리고 위조 문서로 읽히는 레이아웃 요청입니다. 해결책은 보통 사람 이름을 외모 묘사로 바꾸고, 브랜드명을 제품 카테고리로 바꾸고, 여권·신분증·면허증 같은 단어를 피하는 것입니다. 거부된 요청은 과금되지 않습니다.
과금되지 않습니다. 호출 기록에는 CONTENT_MODERATION 실패로 남고 예약된 크레딧은 자동으로 해제됩니다. 이런 거부는 「인프라 성공률」에도 넣지 않습니다. 98.9%가 세는 것은 타임아웃, 업스트림 혼잡, 이미지 미반환 세 가지뿐이며, 프롬프트를 바꿔도 해결되지 않는 실패가 바로 그것들이기 때문입니다.
저희 약관상 제출한 입력과 생성한 출력에 대한 권리는 고객에게 남으며 상업적 이용도 허용됩니다. 다만 두 가지는 알아 두셔야 합니다. 최종 사용은 여전히 OpenAI 콘텐츠 정책의 적용을 받고(위의 거부 항목과 이어집니다), AI 생성 이미지에 저작권이 인정되는지 자체가 나라마다 다릅니다. 브랜드 자산으로 쓰거나 배타적 권리를 주장하기 전에 자체 법무 검토를 받으시길 권합니다.
결과 파일은 저희 오브젝트 스토리지에 **7일** 보관된 뒤 삭제되니, 필요한 것은 내려받거나 자체 스토리지로 옮겨 두세요. 프롬프트와 호출 기록은 콘솔에 장기간 남아 파라미터를 언제든 다시 확인할 수 있습니다. 하나 구분해 둘 점은, 업로드용 presigned URL의 유효 시간이 10분이라는 것입니다. 이는 소재를 올릴 때 쓰는 것으로, 결과물의 7일 보관과는 별개입니다.
APIMODELS에서는 GPT Image 2이(가) 60개가 넘는 모델과 같은 API 키, 같은 잔액 위에 나란히 놓입니다. 그래서 선택은 궁합의 문제이지 종속의 문제가 아닙니다. Text to Image、Image Editing、Multi-Image、1K/2K/4K、Async을(를) 지원하며 다른 이미지 생성 모델과 가격·성능을 나란히 놓고 따져볼 수 있습니다. 갈아타기는 모델 이름 문자열 하나만 바꾸면 되고 새 계정도 추가 작업도 필요 없습니다. 이미지 생성 선택지와 실시간 가격은 apimodels.app/models에서 볼 수 있습니다.
GPT Image 2은(는) 다음을 지원합니다: Text to Image、Image Editing、Multi-Image、1K/2K/4K、Async. 전체 파라미터와 호출 예제는 APIMODELS 문서를 참고하세요.
네. APIMODELS는 GPT Image 2을(를) 하나의 통합 API와 키 한 개로 제공합니다. 공급자별 계정도 필요 없고, 각 공급자의 지역별 네트워크 경로를 직접 챙길 필요도 없습니다.
Stripe(Visa, Mastercard 등 해외 카드)와 Alipay를 지원합니다. 결제 후 잔액은 즉시 반영됩니다.
이 모델에 가장 많이 들어오는 요청이 글자 교체이고, 동시에 프롬프트로 맞추기가 가장 어려운 작업입니다. 새 문구가 원본과 같은 서체, 같은 크기, 같은 배경 위에 앉아야 하기 때문입니다. 직접 만들기 부담스럽다면 EditTextImage가 같은 모델을 쓰는 자체 프런트엔드입니다. 이미지와 지금 적힌 문구, 바꿀 문구만 있으면 됩니다. 스크린샷 글자 편집하는 방법과 원본과 같은 글꼴 유지하는 방법을 따로 정리해 두었는데, 손으로 쓴 프롬프트가 무너지는 건 대개 후자입니다.
APIMODELS makes the GPT Image 2 API easier to access for image generation, image editing, text-rich visuals, and higher-quality commercial image workflows.
GPT Image-2 API turns written prompts into polished visual output for marketing creatives, product concepts, social media visuals, ad images, illustrations, and branded design assets. The prompt-based workflow gives developers a flexible way to build AI Image Generator experiences for fast visual ideation and refined output.
GPT-Image-2 API also works from existing images, fitting style changes, background replacement, product recoloring, subject enhancement, and composition cleanup — controlled edits that preserve important parts of the original image. For AI Image Editor products, it delivers cleaner transformations with stronger visual control.
Long phrases, multi-word labels, clearer punctuation, and casing consistency — valuable for storefront mockups, posters, UI concepts, infographics, packaging, and branded marketing assets. Typography is no longer the weakest part of the image.
Change one part of an image without disrupting the rest: product recoloring, object replacement, background updates, local scene refinements. Original lighting, shadows, textures, and surrounding style stay coherent — cleaner than broad full-image regeneration.
Better for tasks where visual credibility matters — maps, anatomy diagrams, historical reconstructions, architectural scenes, educational visuals. Complex scenes and object relationships are interpreted more faithfully, making results more believable.
High-quality output at a ~3s generation pace (end-to-end 10-40s async). Stronger instruction following for multi-subject prompts, layered scene detail, and tighter layout control — practical for complex visual creation at scale.
Localized ads, international packaging, interface mockups, educational graphics, branded campaign assets — text inside images is part of the design, not a placeholder. Language accuracy and visual polish delivered together.
Create or log into your APIMODELS account and generate your API Key in the console. This key authenticates all requests and connects GPT Image 2 API to your application or internal workflow.
Use the Playground to evaluate before integrating. Test prompt behavior, compare text-to-image vs image-to-image, review output quality, and validate fit before moving into code.
Connect to your backend service with authenticated requests. Set request parameters, define prompt handling, validate image inputs, and parse returned outputs so the model runs reliably in your application.
Process generated assets, store output files, manage returned URLs or object storage, and define how results flow back to users or downstream services. A clean pipeline turns the API into a usable production component.
Prepare stable production operation: concurrency planning, retry logic, timeout handling, moderation flow, logging, cost control, plus product-specific rules. With these in place, the API can reliably power AI Image Generator and AI Image Editor products.
For teams that need steady volumes of polished campaign visuals across channels: ad images, paid social creatives, promotional banners, launch graphics, seasonal assets. Faster from concept to usable output, closer to real campaign-ready creative from the start.
Fits e-commerce and merchandising where updates are controlled (not one-off concept art): change backgrounds, recolor, refine listing images, test packaging, swap hero visuals — without rebuilding the scene each time. Directly affects conversion and content velocity.
Works as a production layer inside a broader content pipeline rather than a standalone feature: presentation graphics, editorial visuals, UI mockups, blog assets, infographics, concept frames, branded support images — aligned with a larger communication system.
Highly relevant across regions, languages, and audience segments: localized campaigns, multilingual packaging, region-specific promos, educational graphics, interface assets. Visual adaptation, language accuracy, and creative consistency advance together.
Affordable pricing for teams that want to build with a stronger OpenAI image model without pushing costs too high too early. Frequent generation, prompt testing, batch visual creation, and large-scale editing workflows all depend on price — now under tighter control.
Complete documentation covers setup, testing, and deployment. Request structure, input handling, output delivery, authentication, and integration logic — all spelled out for both first-time implementation and long-term iteration.
GPT Image 2, Gemini, Claude, Kling, SparkPix and more are all callable through one unified API and one key — no need to register on separate platforms. Transparent pay-as-you-go pricing, ideal for indie devs and startups.
state=failed tasks are not billed, so retries are safe. Successful results are hosted on our R2 and URLs are directly consumable — still recommended to persist to your own storage within 24h as defense-in-depth.
Prompts shared by their authors — copy and adapt them. Each one credits its author and links back to the original post.
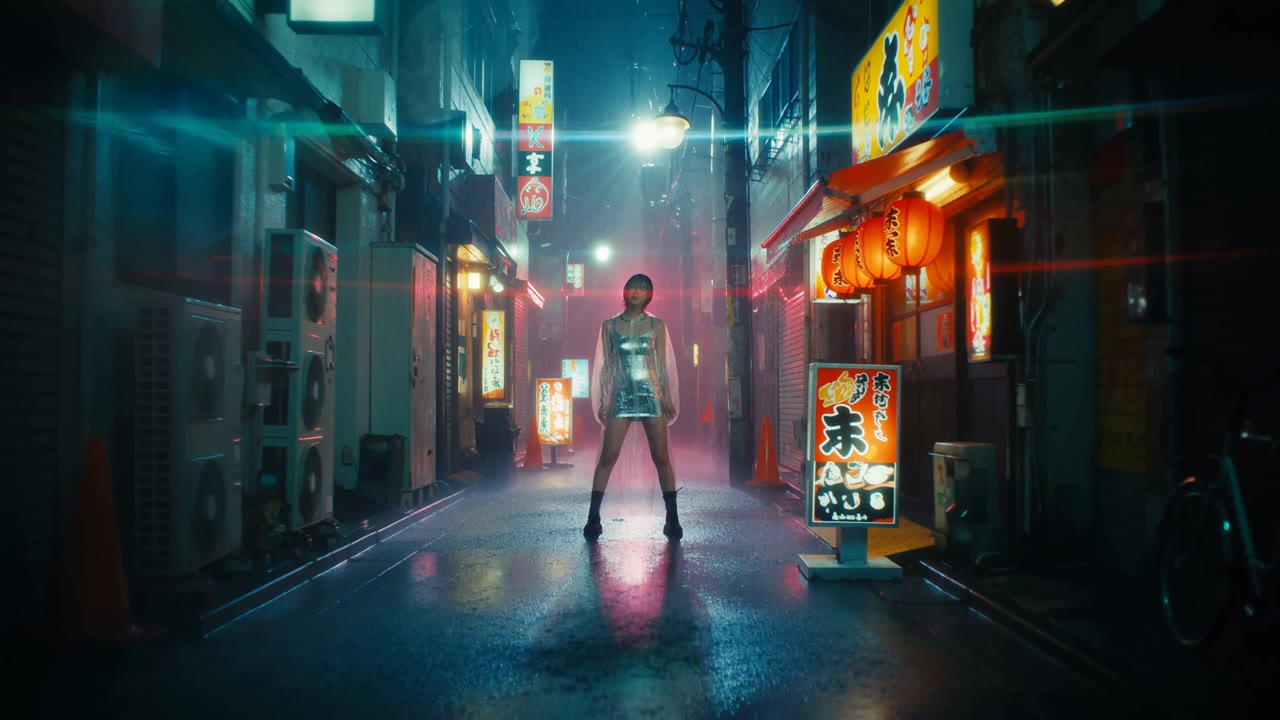
Neon Tokyo Music Video (native stereo audio)
Music video. The soundtrack is a high-energy city-pop / synthwave track with a driving bassline, punchy live drums and a bright analog synth hook, playing continuously from the first frame. Neon-lit Tokyo backstreet at night in the rain. A young female singer in an oversized translucent raincoat performs straight to camera under a red izakaya lantern, singing the hook in sync with the music. Fast cuts landing on the beat: wide shot down the alley with neon reflected in puddles; tight close-up of her face with magenta rim light and rain on her cheek; low-angle push as she walks toward camera when the bass drops; quick insert of rain hitting a buzzing neon sign; back to a wide performance shot as the hook repeats. Anamorphic lens flares, shallow depth of field, 35mm film grain, teal and magenta palette, cinematic colour grade. No on-screen text.
by APIMODELS
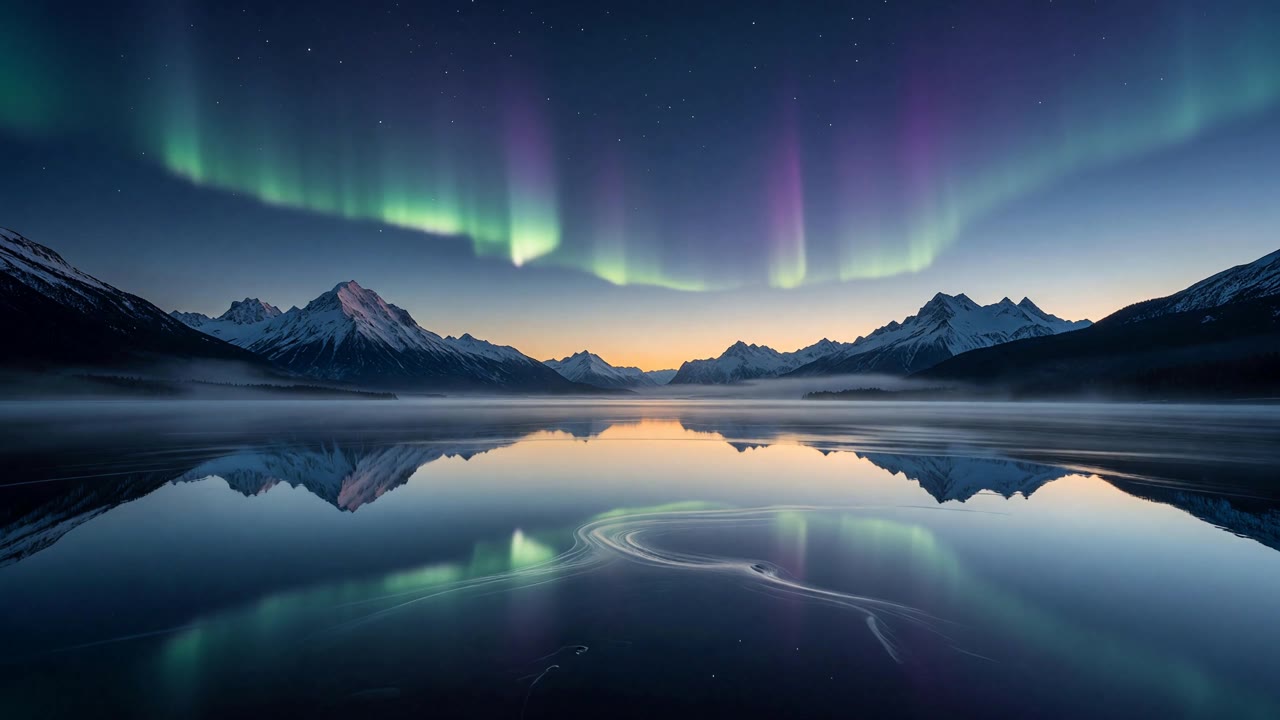
Living Wallpaper: Aurora Lake (locked camera)
Locked-off static camera. No zoom, no pan, no dolly, no parallax. Only ambient atmosphere moves: the aurora ribbons drift and undulate slowly across the night sky, thin low mist creeps gently across the lake, the water surface breathes with extremely subtle ripples while keeping the mirror reflection intact, faint stars shimmer. Calm, continuous, seamless ambient loop. Nothing enters or leaves the frame, no new objects, no people, no text.
by APIMODELS

Condor Heroes characters teach English word dream
神雕侠侣主角趣味讲单词 dream 教程
by @nicekate8888
We curate copy-ready prompt libraries — every entry shows its full text and a sample result, ready to adapt.
How to get access, regional availability, and how this model compares with its alternatives.
