gpt-image-2OpenAI の GPT Image 2 API——最大 16 枚の参照画像を使ったテキストからの画像生成と画像編集に対応し、ネイティブの 1K / 2K / 4K を 1 枚あたり $0.025 / $0.03 / $0.05 で提供します。1 つの API Key で、直接利用よりはるかに安く、OpenAI の組織認証も不要、どこからでもすぐにアクセスできます。
Auto follows your reference image when editing. With text-to-image there is nothing to follow, so it renders square (1:1) — pick a ratio here if you want a shape. Widest available is 21:9; asking for a ratio in the prompt has no effect.
Generated image will appear here
Enter a prompt and click Generate
直近30日の実測で、上流の安全システムに拒否されたリクエストはこのチャネルで0.93%、gpt-image-2-allでは8.0%でした。中身は同じモデルで、審査の基準だけが違います。あちらで同じプロンプトが何度も弾かれるなら、まずこちらを試してください。拒否されたリクエストは課金されません
APIキー1本でGPT Image 2を呼べます。OpenAIの組織認証も本人確認も順番待ちも要らず、中国本土を含めどこからでも接続できます
OpenAI最新の画像モデル。プロンプト追従性は同クラス最高水準です
1リクエストにつき参照画像は最大16枚
1:1、2:3、3:2、4:5、5:4、4:3、3:4、16:9、9:16、21:9(5:4と4:5は1Kのみ)
1K / 2K / 4Kでそれぞれ$0.025 / $0.03 / $0.05(medium品質)。lowとhighの品質帯も選べます
複数の上流チャネルを自動フェイルオーバーし、止まりにくくしています
タスクのエンドポイントをポーリングして結果を受け取ります。通常40-90秒です
GPT Image 2 は OpenAI の画像生成 API です。OpenAI の GPT Image 2 API——最大 16 枚の参照画像を使ったテキストからの画像生成と画像編集に対応し、ネイティブの 1K / 2K / 4K を 1 枚あたり $0.025 / $0.03 / $0.05 で提供します。1 つの API Key で、直接利用よりはるかに安く、OpenAI の組織認証も不要、どこからでもすぐにアクセスできます。 APIMODELS のプラットフォーム経由なら、統一 API と明朗な従量課金でこのモデルを呼び出せます。 現在の料金: 1K: $0.025, 2K: $0.03, 4K: $0.05。
関連モデル: gpt-image-2-all — same model, but you pick the quality tier — low / medium / high × 1K/2K/4K, and OpenAI-SDK compatible (images.generate / images.edit) so Codex and Cursor can call it directly
Posters, ad creatives, covers and packaging where the words are part of the artwork — this is the most reliable in-image text renderer we carry, so headlines come out set, not smeared.
Pass up to 16 reference images to hold a character, product or style steady across a whole batch, instead of re-rolling until two frames happen to match.
Change a background, recolor, swap an element — the rest of the frame stays where it was. Editing is a first-class path here, not a prompt trick.
1K, 2K and 4K come out of the model at that resolution — nothing is upscaled after the fact, so fine detail and small type survive at $0.05 for 4K.
Price depends on resolution alone ($0.025 / $0.03 / $0.05); quality never moves it. Multiply images by tier and you have the exact spend before the first call.
GPT Image 2 は APIMODELS 経由で 1K: $0.025, 2K: $0.03, 4K: $0.05 で利用できます。課金は従量制で、生成した分だけの支払いです。
APIMODELS に登録して API キーを取得し、統一エンドポイントを呼ぶだけです。cURL / Python / Node.js のサンプルを含む詳しいドキュメントを用意しています。
APIMODELS は同じ GPT Image 2 を集約プラットフォーム経由で提供します。統一された API インターフェースなので、プロバイダごとにアカウントを作る必要はありません。キー 1 本ですべてのモデルに届きます。
OpenAI の次世代画像モデルです。画像内タイポグラフィがより鮮明になり、ピクセル単位の編集がより安定し、世界知識も強化されました。生成は高速で、プロンプトへの忠実度も高いのが特徴です。
はい。apimodels.app に登録して API Key を取得すれば、すぐに gpt-image-2 を呼び出せます($0.025/枚から、1K/2K/4K の段階制:$0.025/$0.03/$0.05、1 リクエストあたり最大 16 枚の参照画像に対応)。
両方に対応しています。単一のエンドポイントが参照画像の有無に応じて自動でルーティングします。アスペクト比で出力の構図を制御でき、1 リクエストで最大 16 枚の参照画像を融合できます。
EC の商品画像編集、マーケティング用ビジュアルの一括生成、AI 画像ジェネレーター / エディター SaaS、デザインシステムの生産レイヤー、多言語ローカライズ用ビジュアル、教育コンテンツ向けイラスト、そしてテキストと画像をビジュアル出力に変えるあらゆるワークフローに使えます。
はい。多言語テキストのレンダリングは重点的に改善されたポイントの一つです。複数被写体のプロンプトや階層的なシーンへの指示追従性の向上と相まって、複雑なレイアウトや画像内テキストが目に見えてきれいに仕上がります。
はい。gpt-image-2 は 1 リクエストあたり最大 16 枚の参照画像に対応しており、ルックブック生成、モデル着せ替え、パッケージ合成など、複数参照が必要なシーンに適しています。
1 つの API Key ですべてのモデルを利用でき、cURL / Python / Node.js のサンプル付きの充実した API ドキュメント、失敗時は課金なし、結果は当社の R2 にホスティング、さらに複数の上流チャネル間で自動フェイルオーバーする信頼性を備えています。
apimodels.app では gpt-image-2 は解像度による段階制で、1K / 2K / 4K が $0.025 / $0.03 / $0.05。最低利用額も月額料金もなく、失敗時は課金されません。これにより、GPT Image 2 API を呼び出す最も割安な方法の一つとなっています。
https://api.apimodels.app/v1/images/generations に POST し、ヘッダーに Authorization: Bearer <your API key> を付けます。JSON ボディで model を "gpt-image-2" に設定し、prompt を指定。編集時は image_url(1 枚)または image_urls(最大 16 枚)を追加します。コピペで使える curl と Python(requests / OpenAI SDK 互換の書き方)のサンプルはモデルページのドキュメントにあります。
同じ OpenAI gpt-image-2 モデルなので、画質は同一です。違いはアクセス方法にあります。apimodels.app 経由なら 1 つの API Key で $0.025/枚から(解像度による段階制)利用でき、OpenAI の組織認証(org verification)も不要、どこからでもアクセス可能。OpenAI を自分で直接つなぐより安く、手間もかかりません。
はい。apimodels.app に登録すれば 1 つの API Key が手に入ります。OpenAI アカウントや組織認証は不要で、エンドポイントは中国からでもどこからでもアクセスできます。生成された画像は当社の R2 にホスティングされ、そのままダウンロードできます。
gpt-image-2 は 1 リクエストあたり最大 16 枚の参照画像を使ったマルチ画像の融合・編集に対応し、出力は 1K / 2K / 4K、画質は low / medium / high の 3 段階(デフォルトは medium)。アスペクト比(1:1、2:3、3:2、4:5、16:9、9:16 など。5:4 と 4:5 は 1K のみで、2K/4K では非対応)で構図を制御できます。料金は解像度 × 画質による段階制で、medium は 1K / 2K / 4K が $0.025 / $0.03 / $0.05 です。
選べません。常に medium で動作し、quality フィールドを送っても効果はありません。これは意図的な設計です。モデル名は 1 つ、解像度パラメータも 1 つ、決めることが 1 つ減り、料金は解像度だけで決まります(1K / 2K / 4K で $0.025 / $0.03 / $0.05)。画質を自分で選びたい場合は gpt-image-2-all をお使いください。中身は同じモデルですが、解像度 × 画質のフルマトリクス(1K/2K/4K × low/medium/high、さらに auto)がそのまま開いています。1K の low は $0.01、最大限のディテールが必要なときは high も選べます。こちらは OpenAI SDK 互換の同期チャネルでもあるので、Codex や Cursor は base_url を変えるだけで呼び出せます。リンクはこのページ下部の関連モデルにあります。
直近 30 日の外部本番トラフィック、24,208 回の呼び出しで **インフラ成功率は 98.9%** です。この数字が数えているのは当社側で直すべき失敗だけで、タイムアウト 119 件、上流混雑 66 件、上流が画像を返さなかったもの 15 件、合計 200 件。OpenAI のコンテンツポリシー拒否とパラメータ不正は含めていません。どちらもプロンプトやパラメータを直せば通るうえ、そもそも課金されないからです。要するに、プロンプトが OpenAI のコンテンツポリシーを通るなら、画像はきちんと返ってきます。 はっきり書いておきます。**この業界には、そもそも成功率を公開している事業者がほとんどいません。** 他社の API ページに並ぶのは「安定」「高可用」といった、検証のしようがない形容詞です。当社は 30 日間の実数を算出方法とセットで公開しています。同じ質問は、どの事業者にもぶつけてみてください。
30 日間の本番実測で中央値 60 秒、p95 は 157 秒です。半数は 1 分以内、95% は 2 分半以内に返ります。同期モード(`size` を渡し、`callback_url` は渡さない)は画像ができるまで接続を保持します。長い接続を抱えたくなければ、タスクモードでポーリングするか `callback_url` を指定してください。クライアント側のタイムアウトは 180 秒より長めに設定してください。
失敗は一切課金されません。タイムアウトも上流の混雑もコンテンツポリシー拒否も費用はゼロで、実際に届いた画像の分だけ支払う形です。gpt-image-2 と gpt-image-2-all は別々の上流アダプタを通るので、片方の不調がもう片方に波及せず、モデル名を変えるだけで再試行できます。残高は先に予約され、ジョブが失敗すると自動的に解放されます。
サブスクリプションも月額も最低利用額もなく、1 枚ごとの従量課金です。最低チャージは $10 で、API キー 1 本でプラットフォーム上のすべてのモデル(画像・動画・音声・LLM が同じドル残高を共有)を使えるため、モデルベンダーごとに契約を結ぶ必要がありません。一般的なメールドメインで登録した新規アカウントには $0.10 の無料クレジットが付き、既定画質の 1K 画像を 4 枚生成できます。お金を払う前に出力品質を確かめられるということです。OpenAI アカウントや組織認証も不要で、中国本土からも到達できます。
Stripe(カード)、PayPal、Alipay に対応しています。**Stripe で支払う場合は決済画面で法人の税番号(EU VAT など)を入力でき、支払い後に双方の税務情報を記載した正式な請求書 PDF が自動生成されてメールで届きます**。税番号は保存されるので、以降の請求書にも自動で載ります。PayPal は税番号を収集しないため手動発行となり、support@apimodels.app に会社名・住所・税番号をお送りください。販売主体は英国法人なので、EU 域内の法人向け販売はリバースチャージの扱いになります。
アカウントはプリペイド残高制です。残高が尽きると、呼び出しは課金を続けるのではなく 402 を返すので、上限は物理的に固く、使いすぎは起こりません。加えて、残高低下 webhook(しきい値を下回るとお客様のサービスに通知)と自動チャージ(失敗回数のカウントとロック付きで、再試行の暴走を防ぎます)も設定できます。呼び出しごとの実際の課金額・入力パラメータ・結果はコンソールに 1 件ずつ明細として残るため、月末に突き合わせる作業は要りません。
現実的な入口は 3 つです。OpenAI 公式 API(および同じ定価の Azure OpenAI)、APIMODELS のような独立ゲートウェイ、そして汎用のアグリゲータ。表示価格ではなく、次の 4 点で比べてください。① **実際の成功率と、その計算方法** —— 分母にコンテンツポリシー拒否が入るかどうかを確認すること。2 つの定義は比較になりません。② 失敗が課金されるか。③ 価格が読めるか —— 公式 API は画像を出力トークンとして課金するため、1 枚あたりの費用は数字ではなく幅になります。④ そもそも使えるか —— OpenAI は画像モデルを組織認証の先に置いています。当社の数字は不利なものも含めてこのページに出しています。同じ 4 つの質問を、どの事業者にもしてみてください。
このモデルでは両立します。安さが何かを削って作られたものではないからです。出力は本物の OpenAI 画像パイプラインから出ており、当社はそれを 1 枚いくらの固定料金(1K / 2K / 4K で $0.025 / $0.03 / $0.05)にしているだけです。公式 API は出力トークン課金で、既定画質の 1024x1024 はおよそ $0.053 になります。インフラ成功率は 98.9%、失敗は課金されません。本当に検討すべきトレードオフは別のところにあります。ピクセル単位の寸法保証がパイプラインに必要な場合、あるいは DPA や SOC 2 のチェーンのように直接契約でしか得られないコンプライアンス文書が必要な場合は、公式を選んでください。
拒否しているのは当社ではなく OpenAI のコンテンツポリシーで、実運用ではよく起こります。直近 30 日の 24,208 回のうち 6,007 回がこれに当たり、**おおよそ 4 回に 1 回**の割合です。よくある引き金は、実在人物の氏名や容姿、ブランドと著作権のあるキャラクター、暴力・成人向け表現、そして偽造文書と読めるレイアウト指定です。直し方はたいてい、人名を容姿の描写に置き換える、ブランド名を製品カテゴリに置き換える、パスポート・身分証・免許証といった語を避ける、の 3 つです。拒否されたリクエストは課金されません。
課金されません。呼び出しログには CONTENT_MODERATION の失敗として記録され、予約されていた残高は自動的に解放されます。この種の拒否は「インフラ成功率」にも入れていません。98.9% が数えているのはタイムアウト・上流混雑・画像が返らなかったケースだけで、それらこそプロンプトを変えても解決しない失敗だからです。
当社の利用規約では、送信した入力と生成された出力についての権利はお客様に残り、商用利用も認められています。ただし 2 点。最終的な利用は引き続き OpenAI のコンテンツポリシーに従います(上の拒否の話につながります)。そして AI 生成画像にそもそも著作権が発生するかは、国・地域によって判断が分かれます。ブランド資産として使う前、あるいは独占的な権利を主張する前に、ご自身の法務にご相談ください。
結果ファイルは当社のオブジェクトストレージに **7 日間** 保管され、その後削除されます。必要なものはダウンロードするか、ご自身の側に保存し直してください。プロンプトと呼び出し記録はコンソールに長期間残るので、パラメータは後からいつでも確認できます。1 つだけ区別しておきたい点があります。アップロード用の presigned URL の有効期限は 10 分ですが、これは素材をアップロードするためのもので、結果ファイルの 7 日間保持とは別の話です。
APIMODELS では GPT Image 2 が 60 以上のモデルと同じ API キー・同じ残高の上に並んでいるので、選択は「相性」の問題であって「囲い込み」の問題ではありません。Text to Image、Image Editing、Multi-Image、1K/2K/4K、Async に対応しており、他の画像生成モデルと価格・機能を並べて評価できます。乗り換えはモデル名の文字列を 1 つ書き換えるだけ。新しいアカウントも追加の実装も要りません。画像生成の選択肢と最新価格は apimodels.app/models で確認できます。
GPT Image 2 は次に対応しています: Text to Image、Image Editing、Multi-Image、1K/2K/4K、Async。パラメータの全一覧と呼び出し例は APIMODELS のドキュメントをご覧ください。
はい。APIMODELS は GPT Image 2 を単一の統一 API とキー 1 本で提供します。プロバイダごとのアカウントも、各社の地域ごとのネットワーク経路を自分で面倒みる必要もありません。
Stripe(Visa、Mastercard などの国際カード)と Alipay に対応しています。支払い後、残高はすぐ反映されます。
このモデルにいちばん多く寄せられる用途が文字の差し替えで、同時にプロンプトで最も再現しにくい処理でもあります。新しい文字を、元のフォント・サイズ・背景にそのまま載せなければならないからです。自分で組みたくない場合は、EditTextImage が同じモデルを使った自社フロントエンドです。必要なのは画像と、今の文字と、直したい文字だけ。スクショの文字を差し替える手順と、元と同じフォントを保つ解説があり、手書きプロンプトが崩れるのはたいてい後者です。
APIMODELS makes the GPT Image 2 API easier to access for image generation, image editing, text-rich visuals, and higher-quality commercial image workflows.
GPT Image-2 API turns written prompts into polished visual output for marketing creatives, product concepts, social media visuals, ad images, illustrations, and branded design assets. The prompt-based workflow gives developers a flexible way to build AI Image Generator experiences for fast visual ideation and refined output.
GPT-Image-2 API also works from existing images, fitting style changes, background replacement, product recoloring, subject enhancement, and composition cleanup — controlled edits that preserve important parts of the original image. For AI Image Editor products, it delivers cleaner transformations with stronger visual control.
Long phrases, multi-word labels, clearer punctuation, and casing consistency — valuable for storefront mockups, posters, UI concepts, infographics, packaging, and branded marketing assets. Typography is no longer the weakest part of the image.
Change one part of an image without disrupting the rest: product recoloring, object replacement, background updates, local scene refinements. Original lighting, shadows, textures, and surrounding style stay coherent — cleaner than broad full-image regeneration.
Better for tasks where visual credibility matters — maps, anatomy diagrams, historical reconstructions, architectural scenes, educational visuals. Complex scenes and object relationships are interpreted more faithfully, making results more believable.
High-quality output at a ~3s generation pace (end-to-end 10-40s async). Stronger instruction following for multi-subject prompts, layered scene detail, and tighter layout control — practical for complex visual creation at scale.
Localized ads, international packaging, interface mockups, educational graphics, branded campaign assets — text inside images is part of the design, not a placeholder. Language accuracy and visual polish delivered together.
Create or log into your APIMODELS account and generate your API Key in the console. This key authenticates all requests and connects GPT Image 2 API to your application or internal workflow.
Use the Playground to evaluate before integrating. Test prompt behavior, compare text-to-image vs image-to-image, review output quality, and validate fit before moving into code.
Connect to your backend service with authenticated requests. Set request parameters, define prompt handling, validate image inputs, and parse returned outputs so the model runs reliably in your application.
Process generated assets, store output files, manage returned URLs or object storage, and define how results flow back to users or downstream services. A clean pipeline turns the API into a usable production component.
Prepare stable production operation: concurrency planning, retry logic, timeout handling, moderation flow, logging, cost control, plus product-specific rules. With these in place, the API can reliably power AI Image Generator and AI Image Editor products.
For teams that need steady volumes of polished campaign visuals across channels: ad images, paid social creatives, promotional banners, launch graphics, seasonal assets. Faster from concept to usable output, closer to real campaign-ready creative from the start.
Fits e-commerce and merchandising where updates are controlled (not one-off concept art): change backgrounds, recolor, refine listing images, test packaging, swap hero visuals — without rebuilding the scene each time. Directly affects conversion and content velocity.
Works as a production layer inside a broader content pipeline rather than a standalone feature: presentation graphics, editorial visuals, UI mockups, blog assets, infographics, concept frames, branded support images — aligned with a larger communication system.
Highly relevant across regions, languages, and audience segments: localized campaigns, multilingual packaging, region-specific promos, educational graphics, interface assets. Visual adaptation, language accuracy, and creative consistency advance together.
Affordable pricing for teams that want to build with a stronger OpenAI image model without pushing costs too high too early. Frequent generation, prompt testing, batch visual creation, and large-scale editing workflows all depend on price — now under tighter control.
Complete documentation covers setup, testing, and deployment. Request structure, input handling, output delivery, authentication, and integration logic — all spelled out for both first-time implementation and long-term iteration.
GPT Image 2, Gemini, Claude, Kling, SparkPix and more are all callable through one unified API and one key — no need to register on separate platforms. Transparent pay-as-you-go pricing, ideal for indie devs and startups.
state=failed tasks are not billed, so retries are safe. Successful results are hosted on our R2 and URLs are directly consumable — still recommended to persist to your own storage within 24h as defense-in-depth.
Prompts shared by their authors — copy and adapt them. Each one credits its author and links back to the original post.
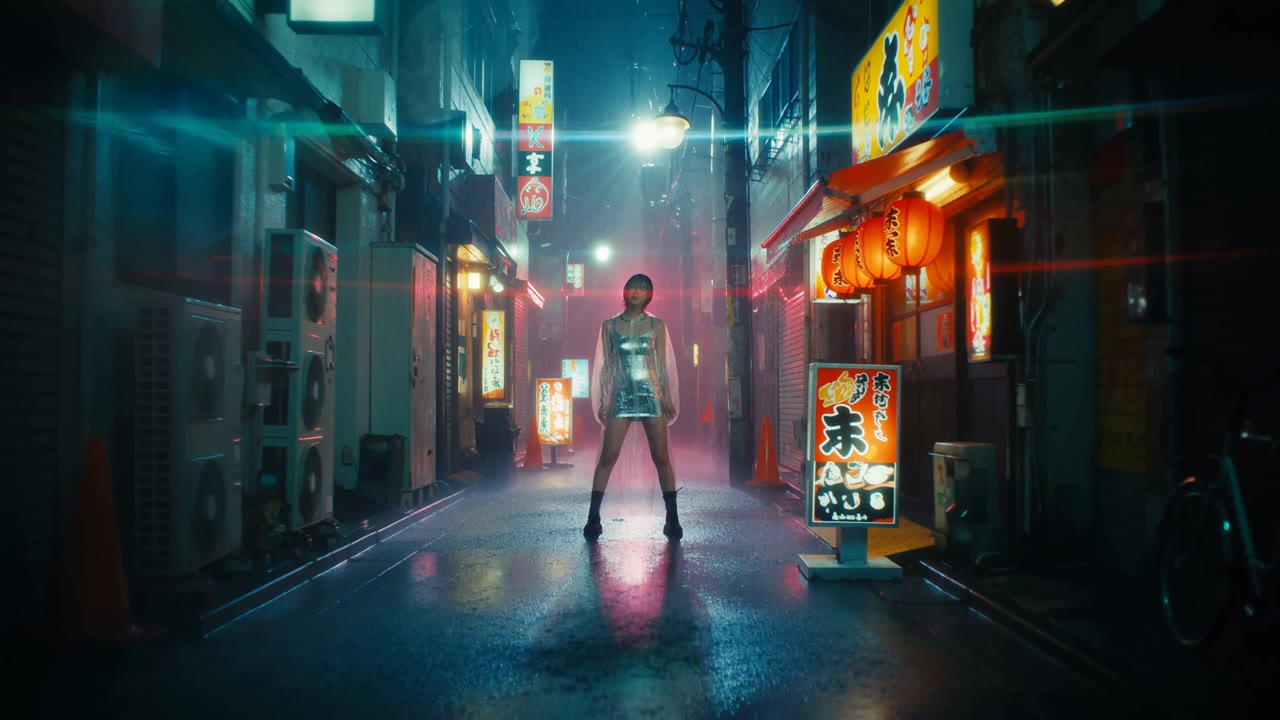
Neon Tokyo Music Video (native stereo audio)
Music video. The soundtrack is a high-energy city-pop / synthwave track with a driving bassline, punchy live drums and a bright analog synth hook, playing continuously from the first frame. Neon-lit Tokyo backstreet at night in the rain. A young female singer in an oversized translucent raincoat performs straight to camera under a red izakaya lantern, singing the hook in sync with the music. Fast cuts landing on the beat: wide shot down the alley with neon reflected in puddles; tight close-up of her face with magenta rim light and rain on her cheek; low-angle push as she walks toward camera when the bass drops; quick insert of rain hitting a buzzing neon sign; back to a wide performance shot as the hook repeats. Anamorphic lens flares, shallow depth of field, 35mm film grain, teal and magenta palette, cinematic colour grade. No on-screen text.
by APIMODELS
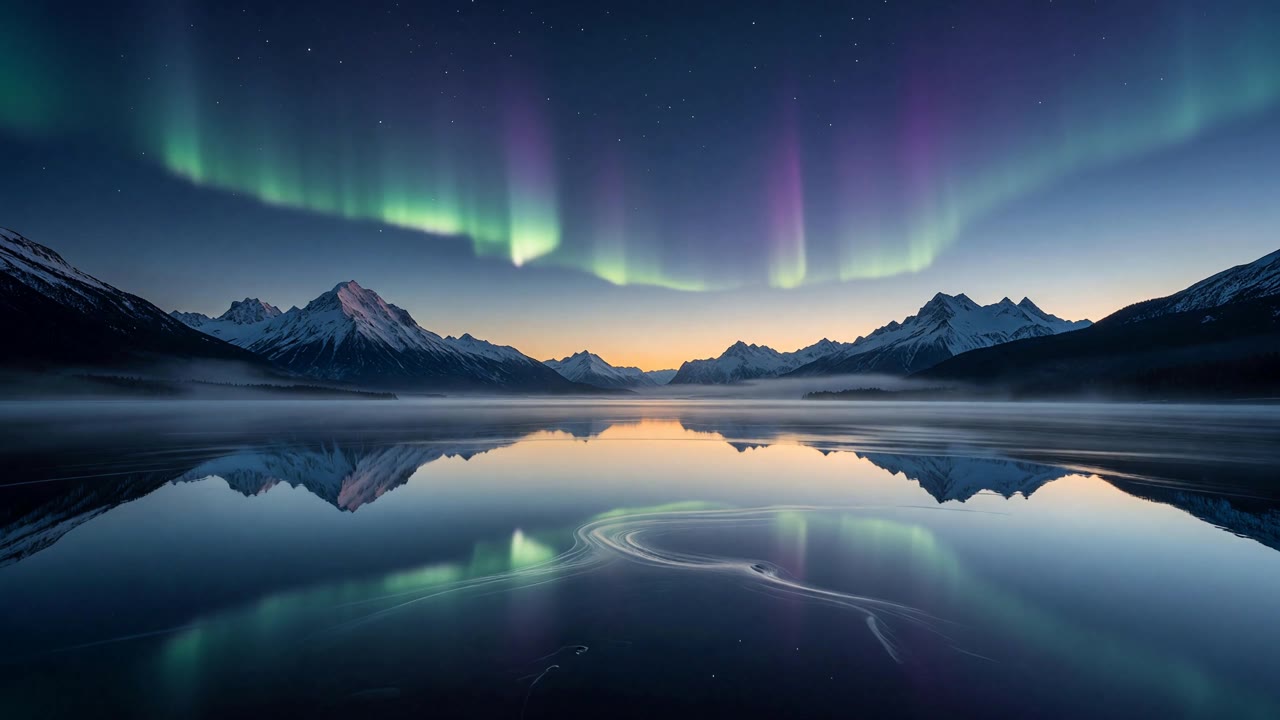
Living Wallpaper: Aurora Lake (locked camera)
Locked-off static camera. No zoom, no pan, no dolly, no parallax. Only ambient atmosphere moves: the aurora ribbons drift and undulate slowly across the night sky, thin low mist creeps gently across the lake, the water surface breathes with extremely subtle ripples while keeping the mirror reflection intact, faint stars shimmer. Calm, continuous, seamless ambient loop. Nothing enters or leaves the frame, no new objects, no people, no text.
by APIMODELS

Condor Heroes characters teach English word dream
神雕侠侣主角趣味讲单词 dream 教程
by @nicekate8888
We curate copy-ready prompt libraries — every entry shows its full text and a sample result, ready to adapt.
How to get access, regional availability, and how this model compares with its alternatives.
