
muse-videoMuse Video は Meta Superintelligence Labs の動画モデルです。APIMODELS では統合動画エンドポイント上の 1 つのモデル ID muse-video で、プロンプトだけを送ればテキストから動画、先頭フレームの画像を 1 枚加えればその画像から始まる動画になり、参照画像を最大 4 枚加えれば、その画像からは始めずに同じ人物や被写体を保った動画になります。 リクエストはシンプルです。prompt は必須(4,000 文字以内、言語は問いません)。duration で長さを 4〜30 の整数秒で指定します(OpenAI 形式の seconds でも可)。省略すると 5 秒です。aspect_ratio で横長 16:9(既定、1280×720)か縦長 9:16(720×1280)を選び、size に 1280x720 または 720x1280 を指定しても同じです。出力は常に 720p で、1080p や正方形はなく、指定するとタスクを作成する前に 400 が返ります。画像から動画にするときは、先頭フレームを image_url で渡します(first_frame_url、image、input_reference も可)。できれば動画と同じ向きの画像を使ってください。参照画像は images で最大 4 枚渡します(image_urls、reference_image_urls も可)。画像はどれも公開 URL か base64 の data URI で、PNG・JPEG・WebP のいずれかです。使えるのはどちらか一方だけで、先頭フレームと参照画像の同時指定、5 枚以上の参照画像、末尾フレーム、参照動画や参照音声、negative_prompt、seed、音声のオフは 400 で拒否されます。 動画の長さは段階式です。5・6・8・10・15・20・25・30 秒のリクエストはちょうどその長さで返り、それ以外の整数は次の段階に切り上げられます(4 → 5 秒、7 → 8 秒、11 → 15 秒)。そのため、支払った長さより短い動画が返ることはありません。動画は H.264 の MP4・24 fps で、Meta は Muse Video が映像と同時に音声も生成すると説明しています。参照画像のテストでは、同じ女性の画像 4 枚から 5 秒の海辺の動画ができ、顔と髪型は同じままでした。動画はどの画像からも始まっていません。 生成は非同期タスクで、作成したあとはポーリングするかコールバックで結果を受け取ります。10 秒までの動画は通常 1〜2 分、15〜30 秒は 3〜7 分ほどかかります。すべてのリクエストが成功するわけではありません。モデルが内容を拒否することも、生成が一時的なエラーになることもあり、向きや長さが違う動画は破棄されます。失敗したタスクは課金されません。料金はリクエストした秒数あたり $0.037 で、5 秒 $0.185、10 秒 $0.37、30 秒 $1.11 です。
The API also takes any other whole number from 4 to 30; it rounds up to the next length here (7 s comes out as 8 s) and is billed on the seconds you request.
Generated video will appear here
Provide URLs and click Generate
モデル ID は 1 つ。プロンプトだけでも、先頭フレーム 1 枚で自分の画像から始めても、参照画像を最大 4 枚渡して同じ人物を複数の動画で保ってもかまいません
整数秒で指定。5・6・8・10・15・20・25・30 秒はそのままの長さで、それ以外は切り上げ。支払った長さより短くなることはありません
1280×720(16:9、既定)か 720×1280(9:16)。H.264 の MP4、24 fps。1080p も正方形もほかの比率もありません
Meta によると、Muse Video は映像と一緒に音声も生成します
すべてのリクエストが成功するわけではなく、失敗したタスクは課金されません。対応外の長さ・サイズ・入力は、タスク作成前に 400 で拒否されます
リクエストした秒数で課金:5 秒 $0.185、10 秒 $0.37、30 秒 $1.11
Muse Video は Meta の動画モデルです。プロンプトだけで生成できるほか、先頭フレームの画像を 1 枚加えればその画像から動画が始まり、参照画像を最大 4 枚加えれば同じ人物や被写体を保てます。返ってくるのは 4〜30 秒・720p の MP4 で、横長 16:9 か縦長 9:16 です。
APIMODELS では POST /v1/video/generations 上の 1 つのモデル ID muse-video として提供し、リクエストした秒数あたり $0.037 で課金します。組み込む前に下の制限を確認してください。720p のみ、横長か縦長のみ、画像は先頭フレーム 1 枚か参照画像最大 4 枚のどちらか一方、そしてすべてのリクエストが成功するわけではありません。
muse-videoテキストから動画、先頭フレームなし、9:16、10 秒。1 回だけ生成し、そのまま掲載しています。
下のプロンプトで 1 回リクエスト(duration 10、aspect_ratio 9:16)。Muse Video は約 75 秒で 10.0 秒・720×1280・音楽付きのクリップを返し、ワンカットのまま動作リストを順番どおりに演じました。枕に頬をつけて目を閉じる、目を開けてカメラを見つめる、照れ笑い、布団を引き上げて顔の半分を隠す、ピースサインをレンズ間際まで近づける、口元を手で隠して枕に顔をうずめて笑う、最後にスマホが傾いて天井を向く、という流れです。
これが Muse Video の得意なタイプのクリップです。ひとりの人物、手持ちの縦向き自撮り構図、小さな仕草の短い連続、そして暖色の暗めの照明と音楽で作る雰囲気。同じプロンプトでもう一度生成すると別の映像になります。テキストから動画ではクリップごとに同じ顔を保てないので、決まったキャラクターを使うなら、その人物の参照画像を最大 4 枚(images)渡してください。モデルは顔を保ったまま、画像から始めずに動画を作ります。
主体:人物是明月(我的固定角色),穿奶白低领细肩吊带;头发被枕头压乱,多缕发丝横过脸部。从闭眼侧躺开始,再睁眼互动。全程同一张脸、同一套衣服。

场景:夜间卧室床上,白被子白枕头,暖色床头灯。她自己拿手机前置超近距自拍,头到上胸几乎占满竖屏,腰腹和下半身不入画。手腕轻轻晃,构图略歪;一镜到底,不切镜。

音乐:轻甜 bedroom pop 器乐,约 90 BPM。无台词、无说话口型。配乐里不要人声和笑声。

动作:侧脸贴枕闭眼浅笑 → 慢慢睁眼锁定镜头 → 下巴抵肩害羞抿嘴笑 → 拉起白被子挡住半张脸再拉开 → 空着手从上胸前伸向镜头,V 手势几乎贴住镜头再收成夹捏/小爱心 → 握拳挡嘴害羞偷笑,把脸埋进枕头 → 手机一歪甩向天花板。实时速度。

画质:故意拍糊,手持动态模糊和局部失焦,暖色低照度,10 秒竖屏。18 本、どれも参照画像 2 枚付きの 10 秒リクエスト 1 回分です。生成されたままを掲載。カードを開くと実際に送ったプロンプトが見られます。
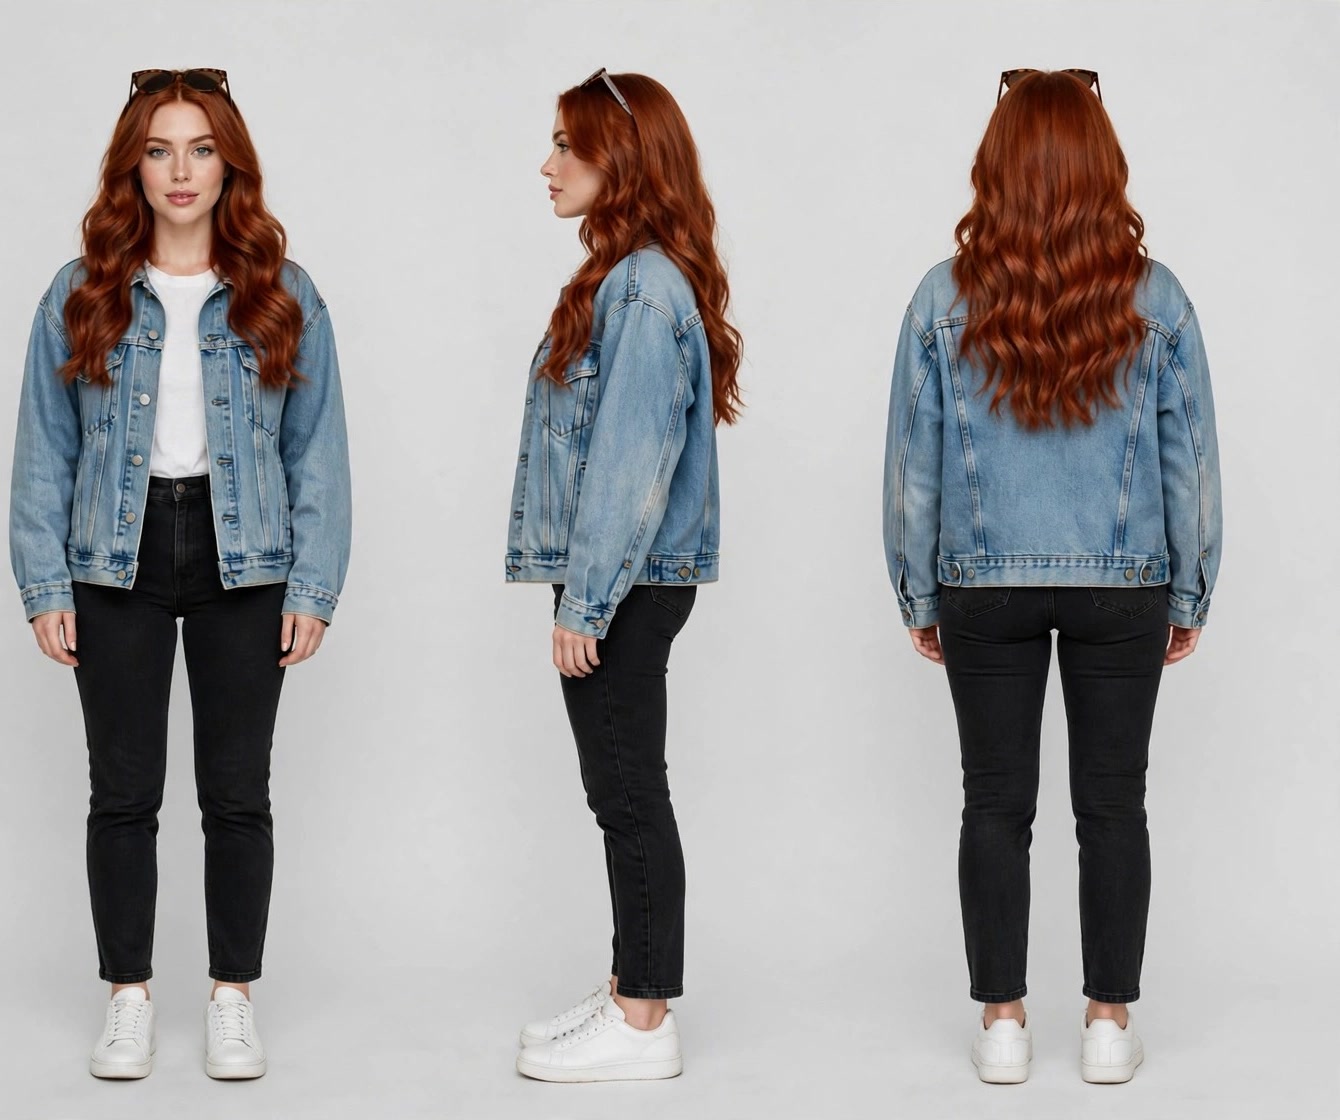
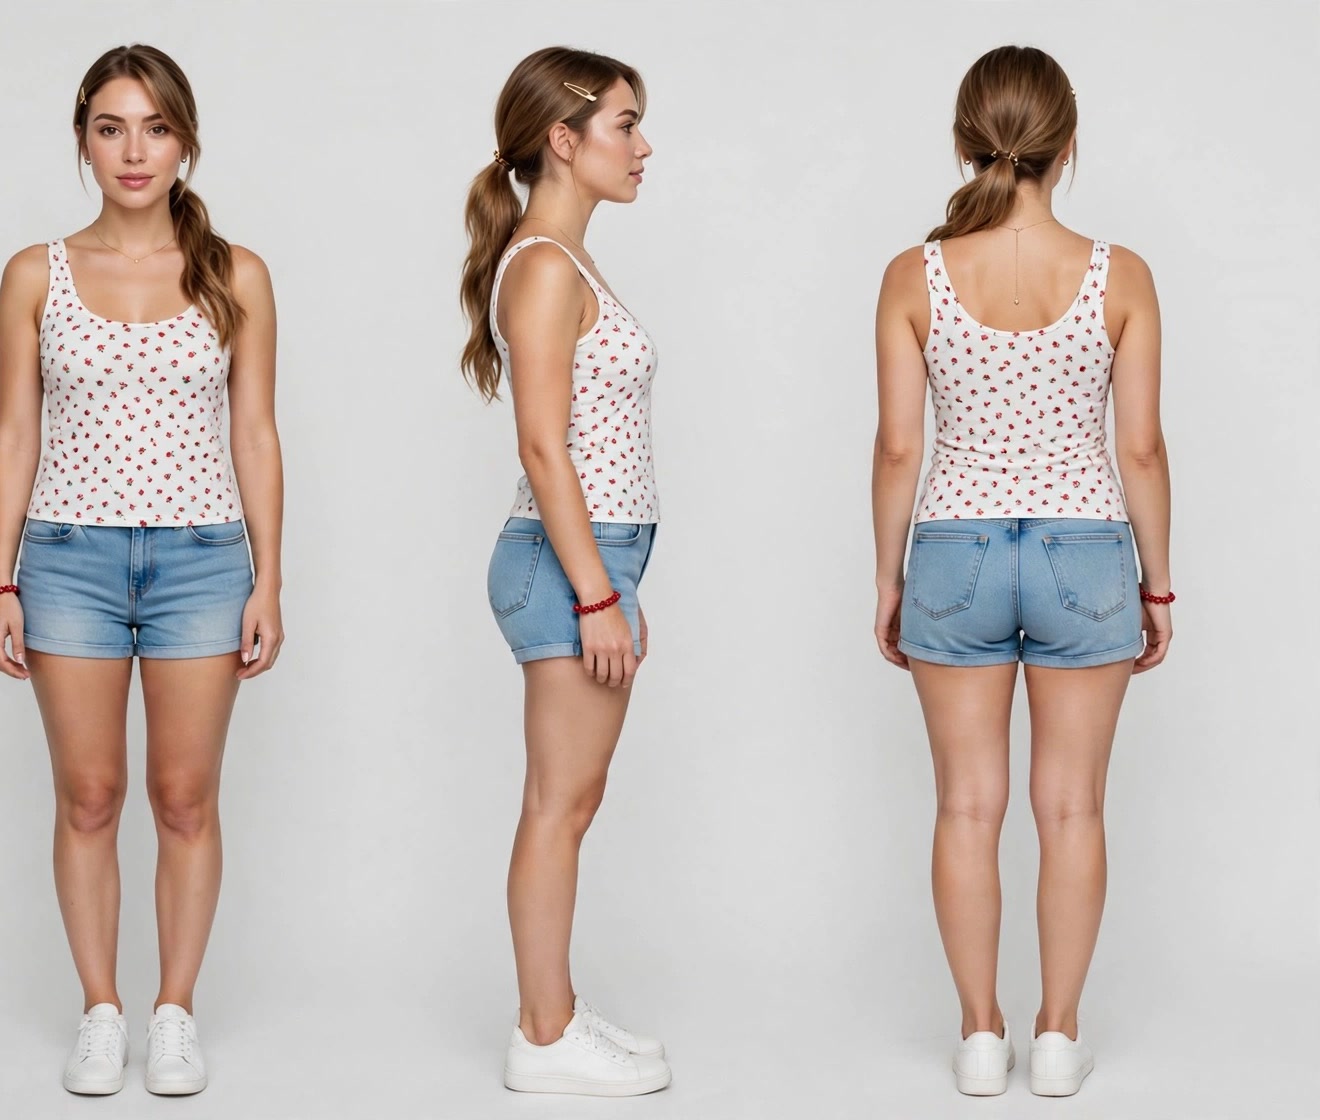
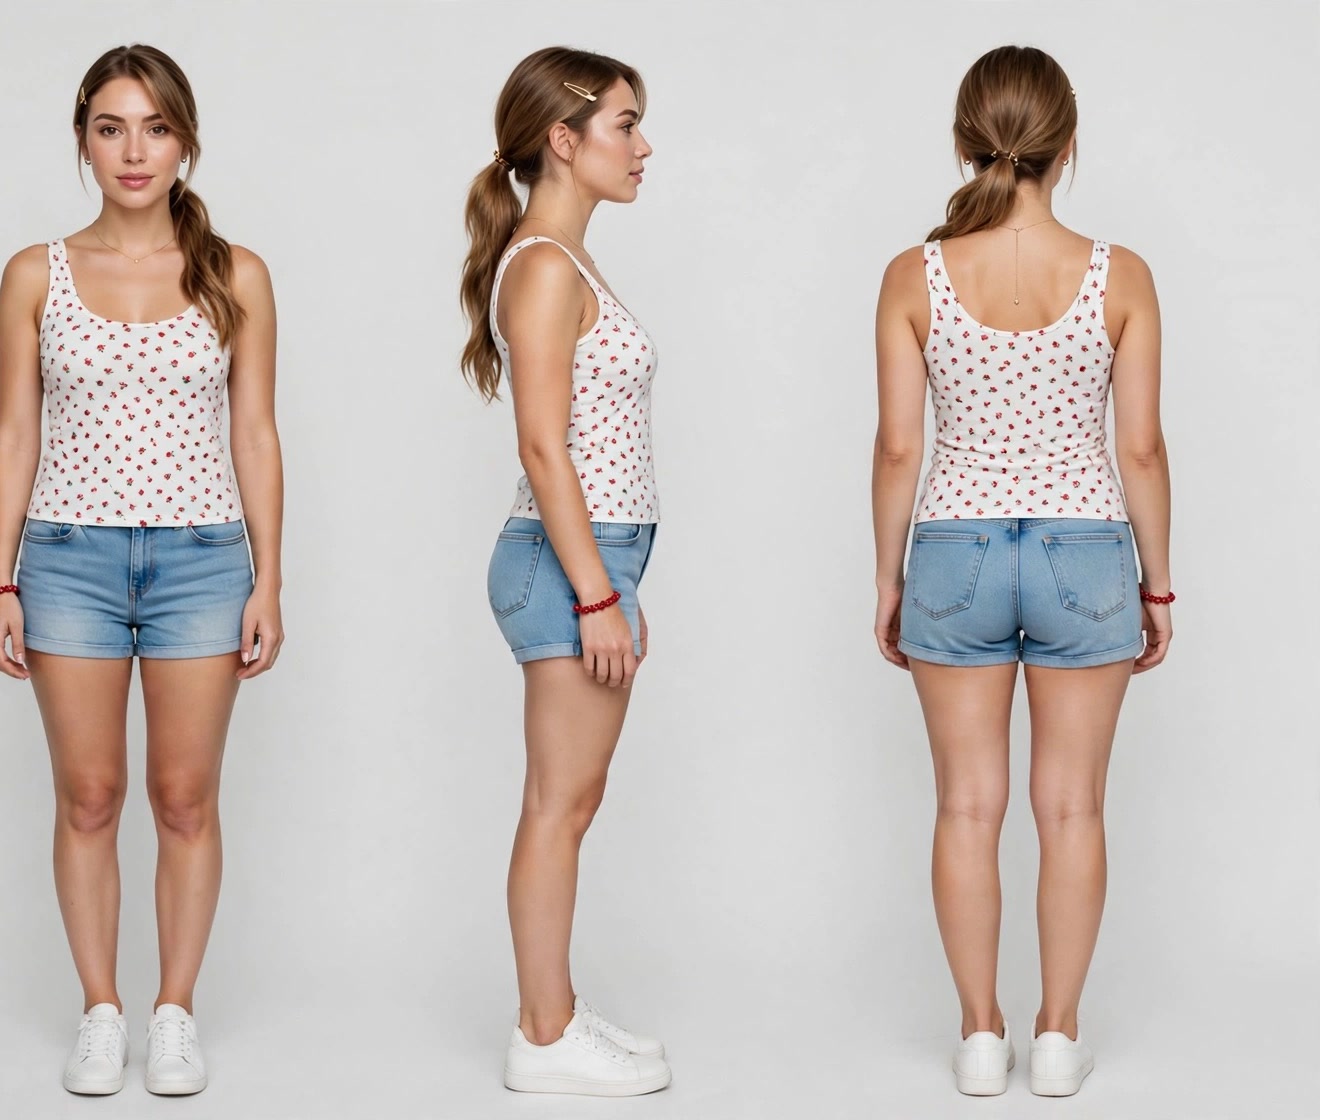
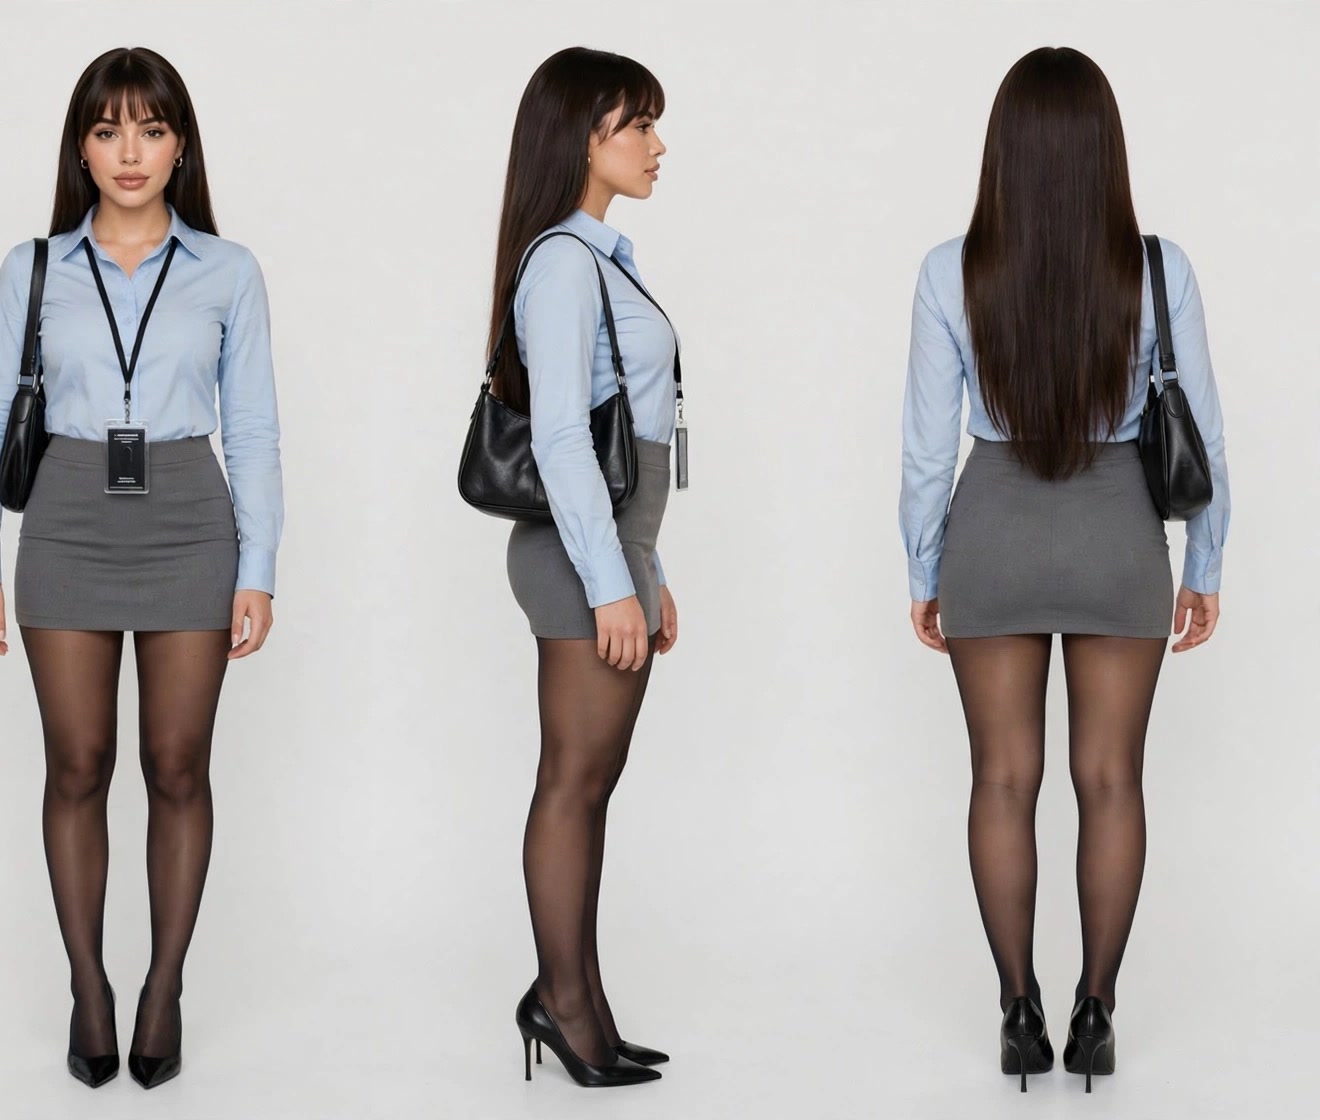
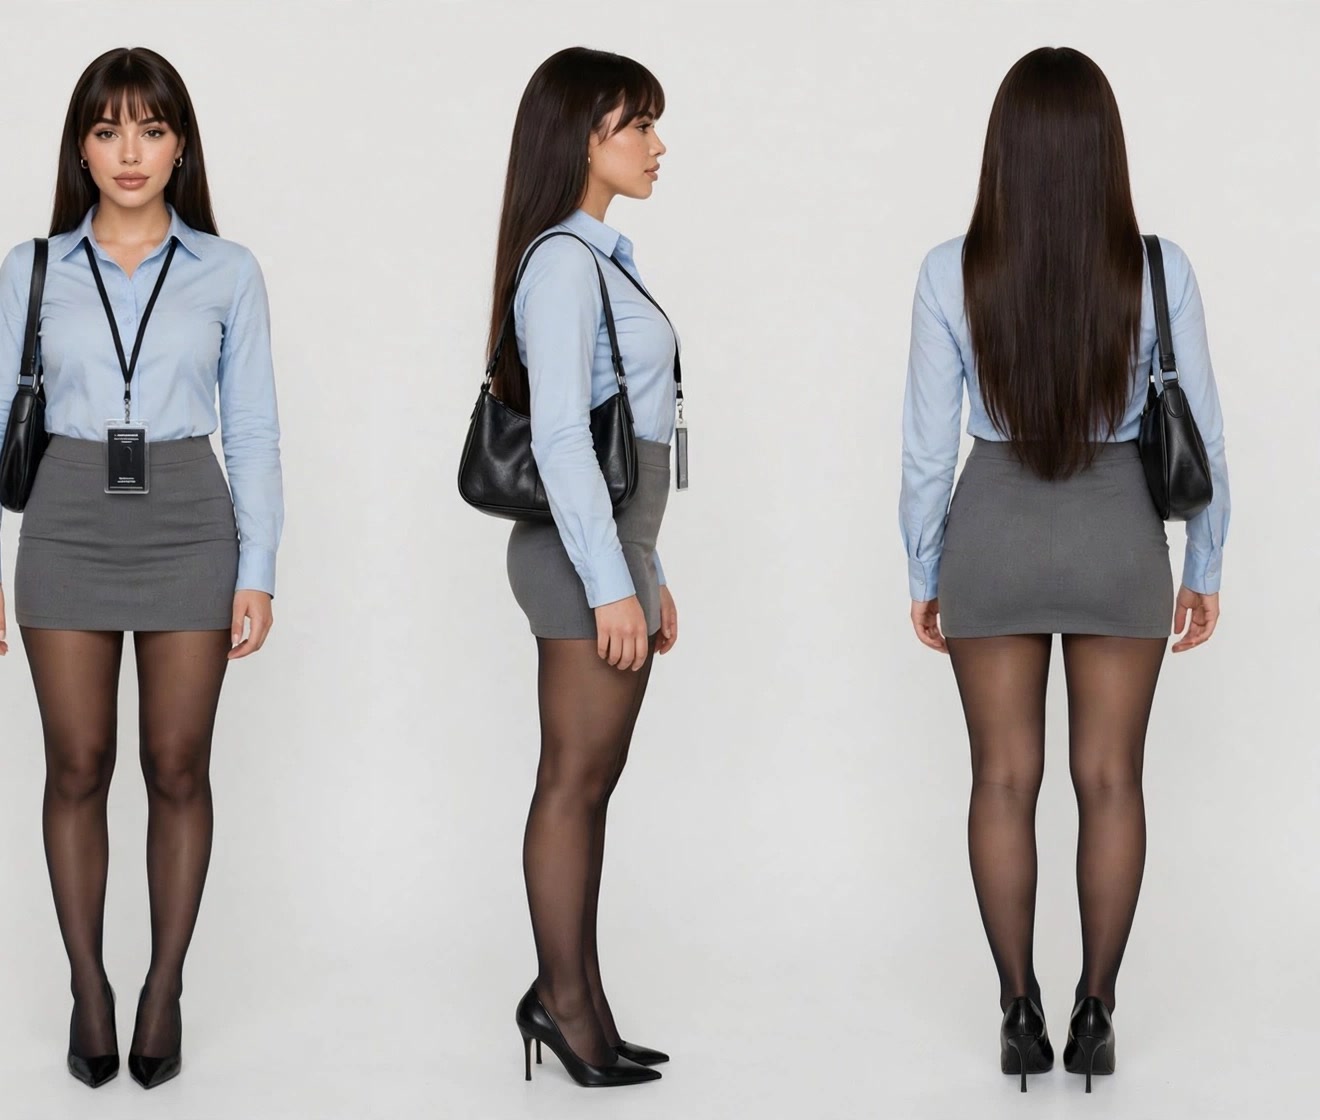
作り方:キャラクターごとに Muse Image で設定画(バストアップと正面・横・背面の三面図を並べた 1 枚)を作り、2 枚に切り分けて参照画像(images)として、10 秒・9:16 のプロンプトと一緒に送りました(キッチン vlog だけ 16:9)。プロンプトは動きを秒単位で書き、服装は露出を抑え、英語のセリフを 1 つ入れています。カットが変わっても顔と服装は同じまま。同じプロンプトの 2 回目(A / B のペア)を見ると、生成ごとの違いがわかります。うち 3 本のプロンプトは X で公開されたプロンプトを改変したもので、出典をカードに記しています。
Took you long enough. I already ordered yours.参照画像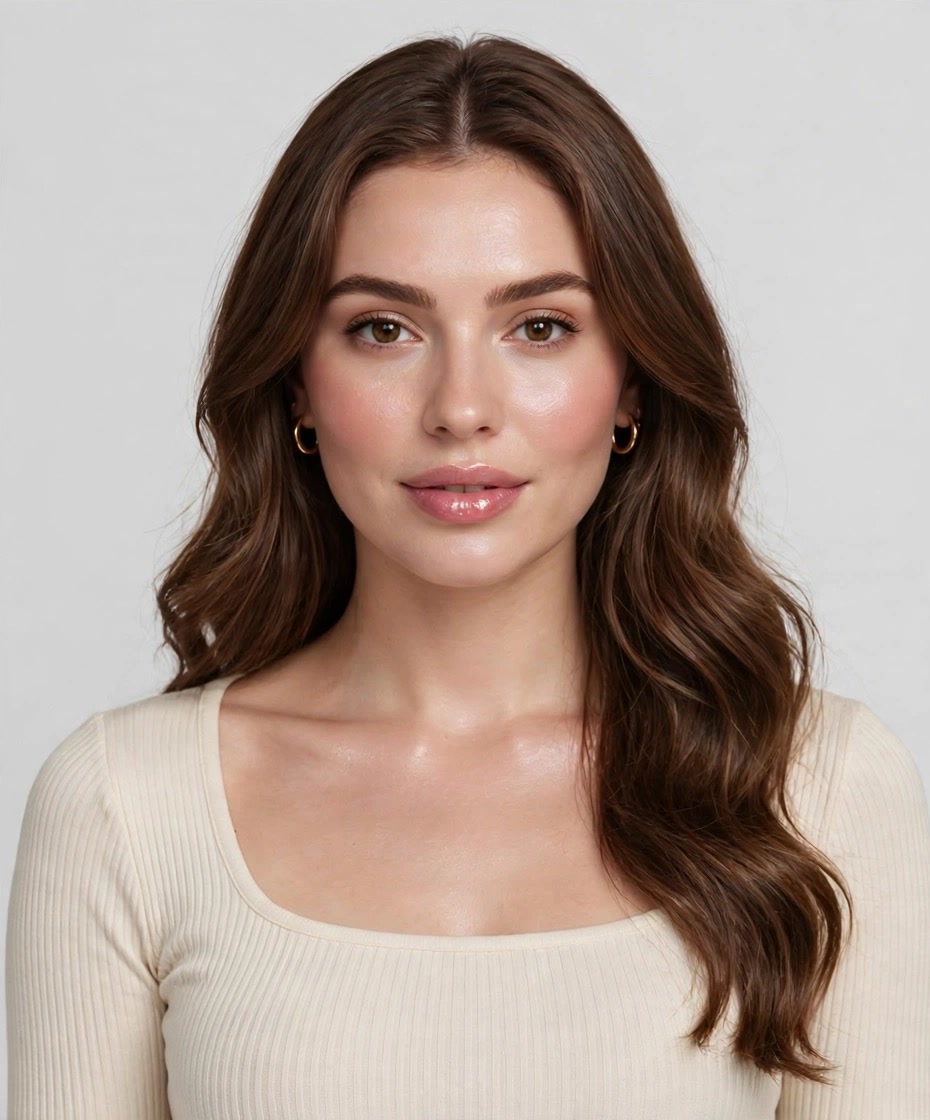
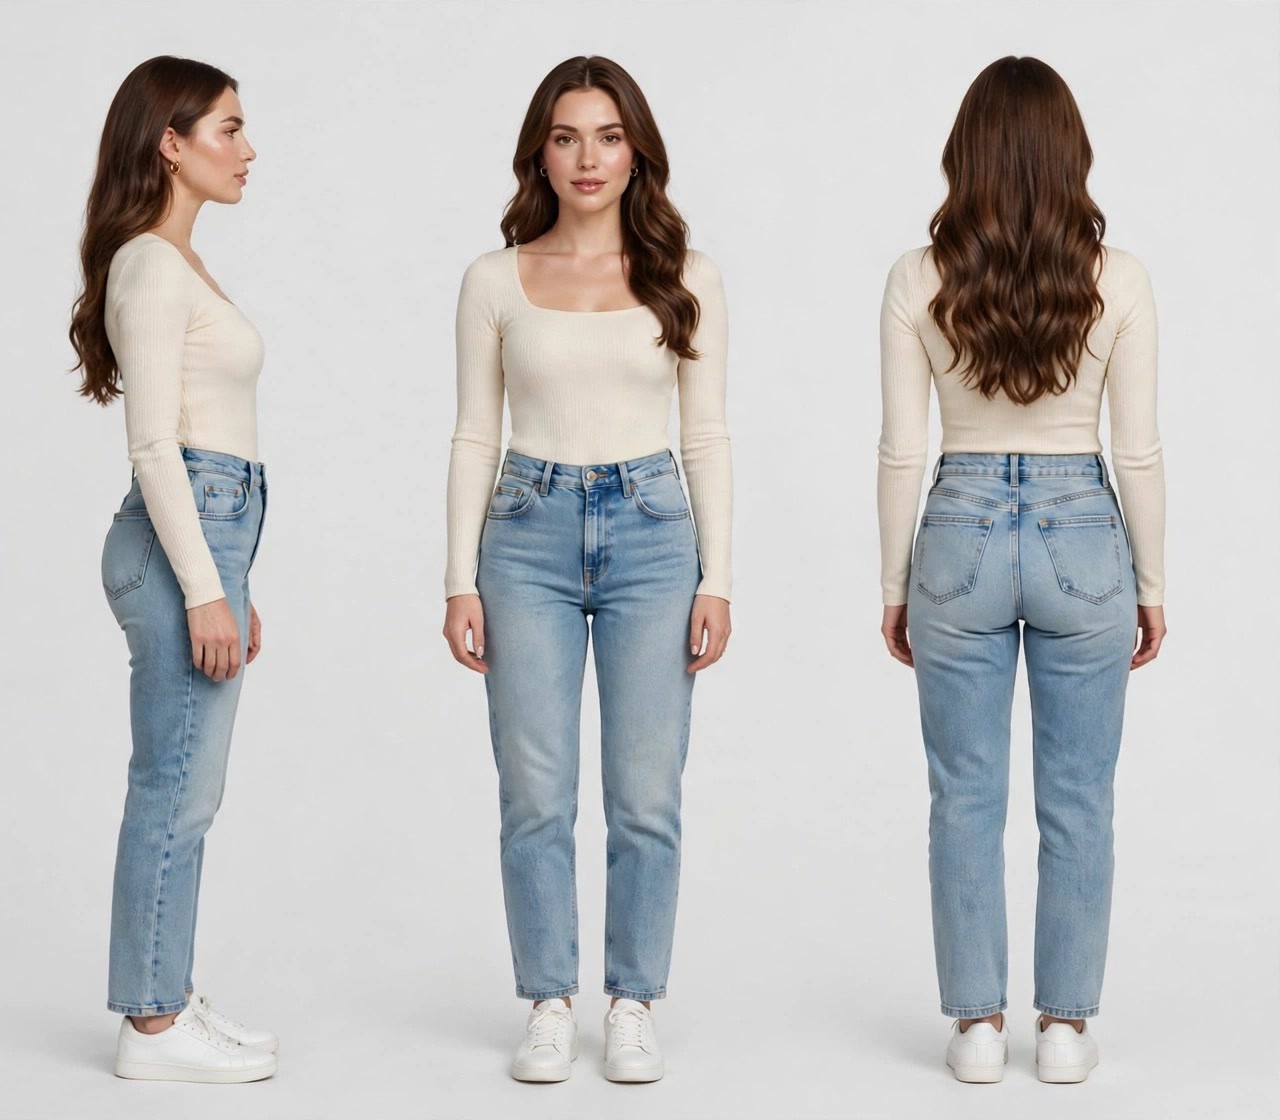
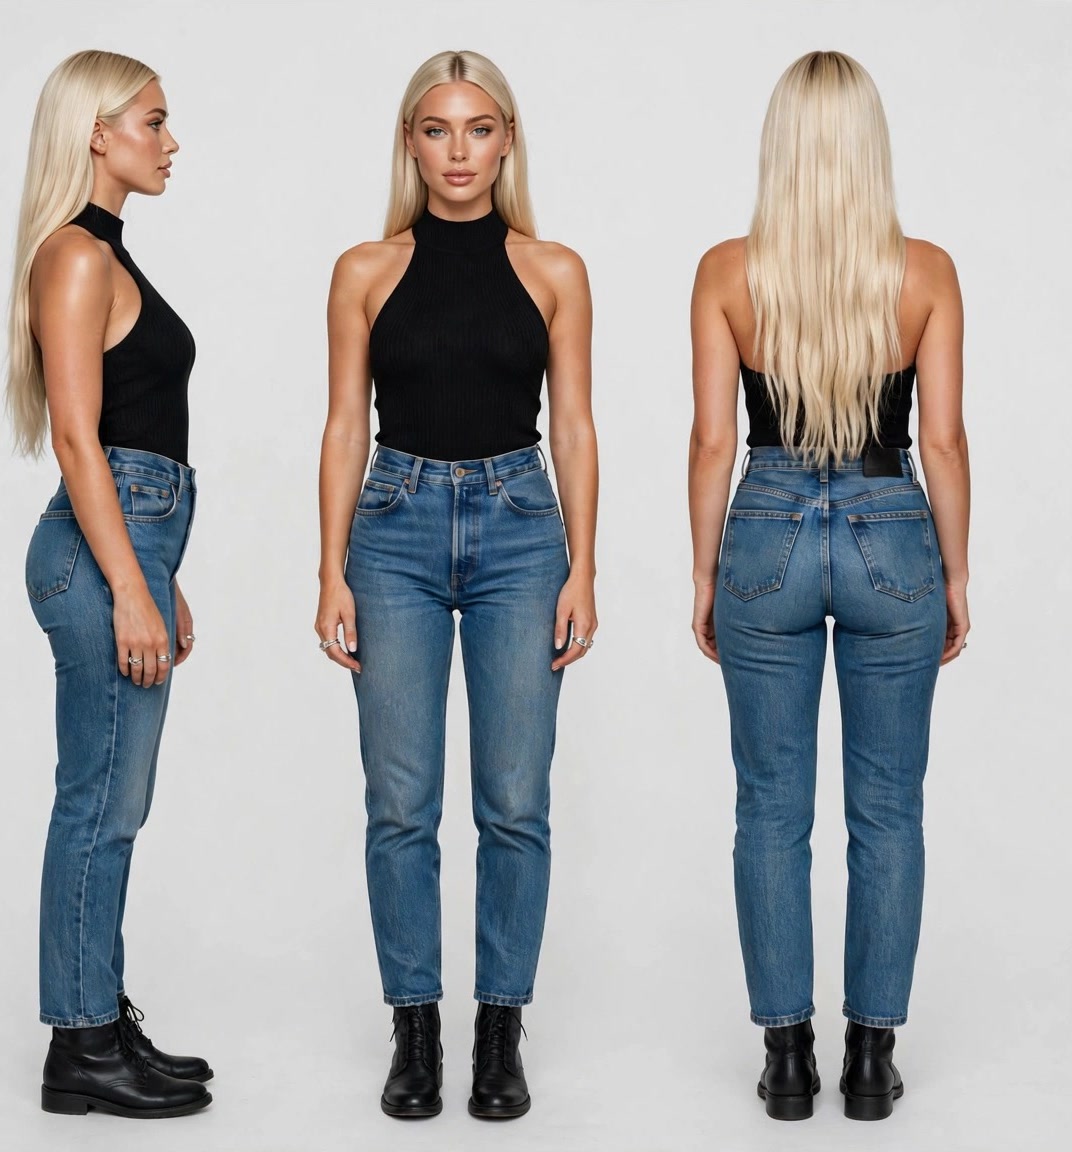
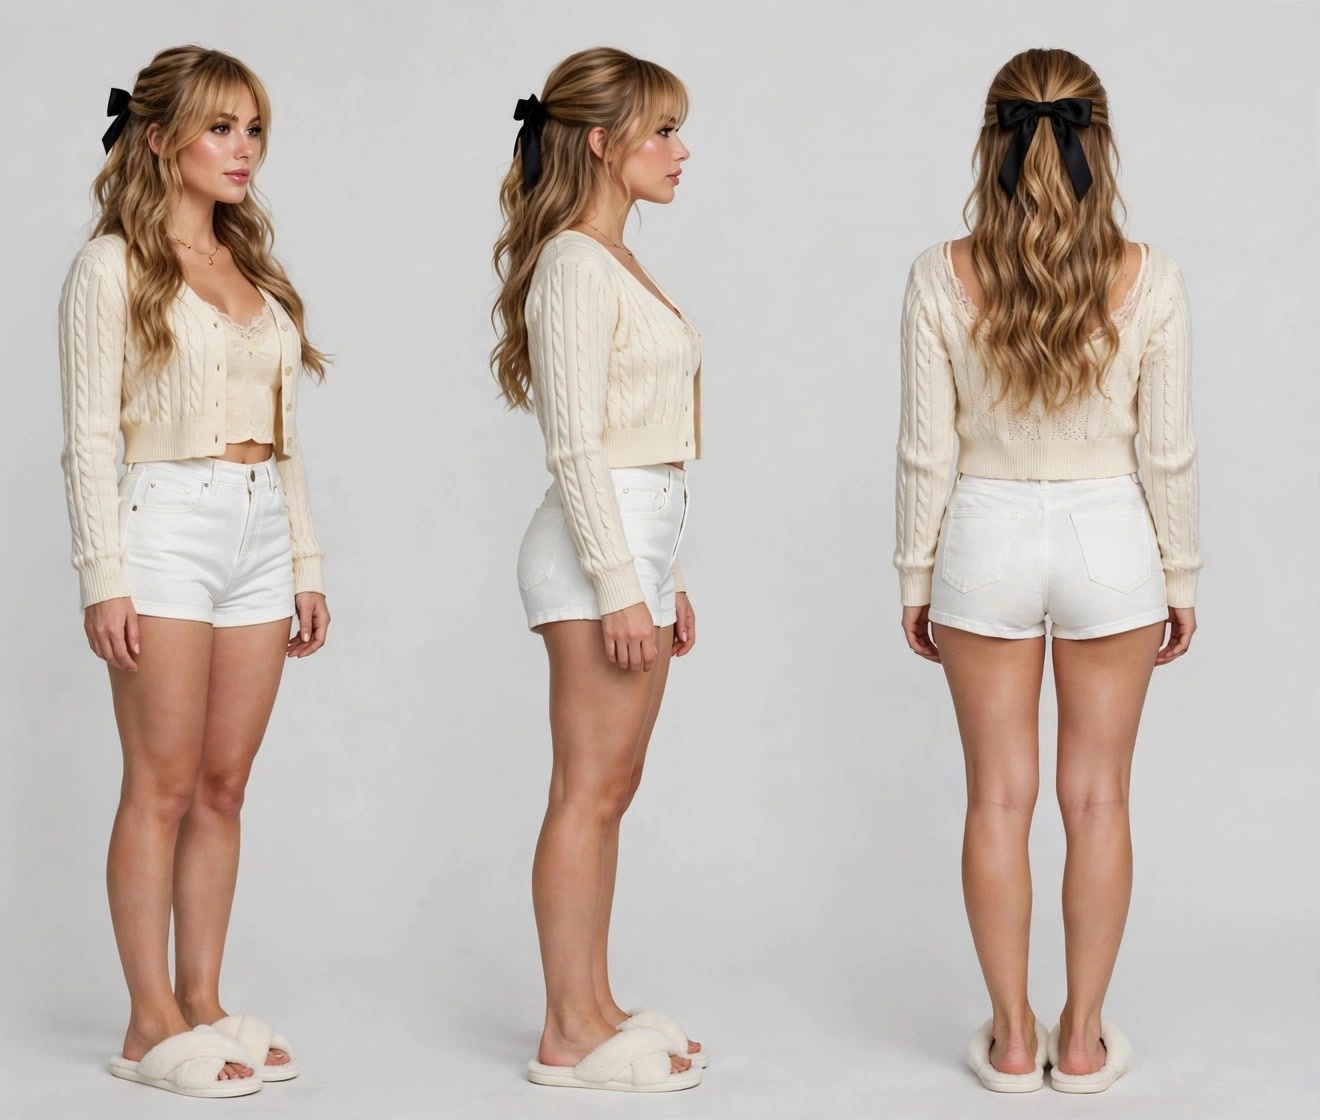
Reference images: image 1 is her headshot (face, features, hair, makeup); image 2 is a front / side / back three-view of the same woman (outfit, accessories, shoes, body). Keep exactly this face, hair and outfit in every frame. She is a 25-year-old woman with a polished Instagram look.

Coffee date. Scene: a sunny corner café, window seat, a small wooden table with two iced oat lattes, soft morning light through the window, the street blurred outside, a few customers far in the background.
Camera: the viewer's point of view, sitting across the table from her, eye level, one continuous take, no cuts.
0.0–1.5 s: she rests her chin on one hand and stirs her latte with the straw, looking down with a small smile.
1.5–3.0 s: she looks up into the lens, raises one eyebrow and her smile widens.
3.0–5.0 s: she says, warm and teasing: "Took you long enough. I already ordered yours." and slides the second latte toward the camera with two fingers.
5.0–7.0 s: she tucks a strand of hair behind her ear and leans forward a little on her elbows, holding eye contact, with a soft laugh.
7.0–8.5 s: she taps the table twice and tilts her head toward the empty chair, inviting the viewer to sit.
8.5–10.0 s: she sips her latte and keeps looking into the lens over the straw, eyes smiling, until the end.
Mood: warm, playful, confident, friendly; natural eye contact, nothing exaggerated.
Lighting: soft warm daylight, gentle highlights in her hair, realistic skin texture.

Audio: soft acoustic café music and light café ambience; her line is clear, natural American English; no other voices, no laugh track.
Style: realistic Instagram Reel shot on an iPhone, vertical 9:16, natural colors, crisp focus on her face, gentle handheld motion.
Avoid: changing her face or outfit, revealing or low-cut clothing, see-through fabric, extra fingers, warped hands, strangers staring at the camera, on-screen text, subtitles, watermark.Come on, the sun's going down!参照画像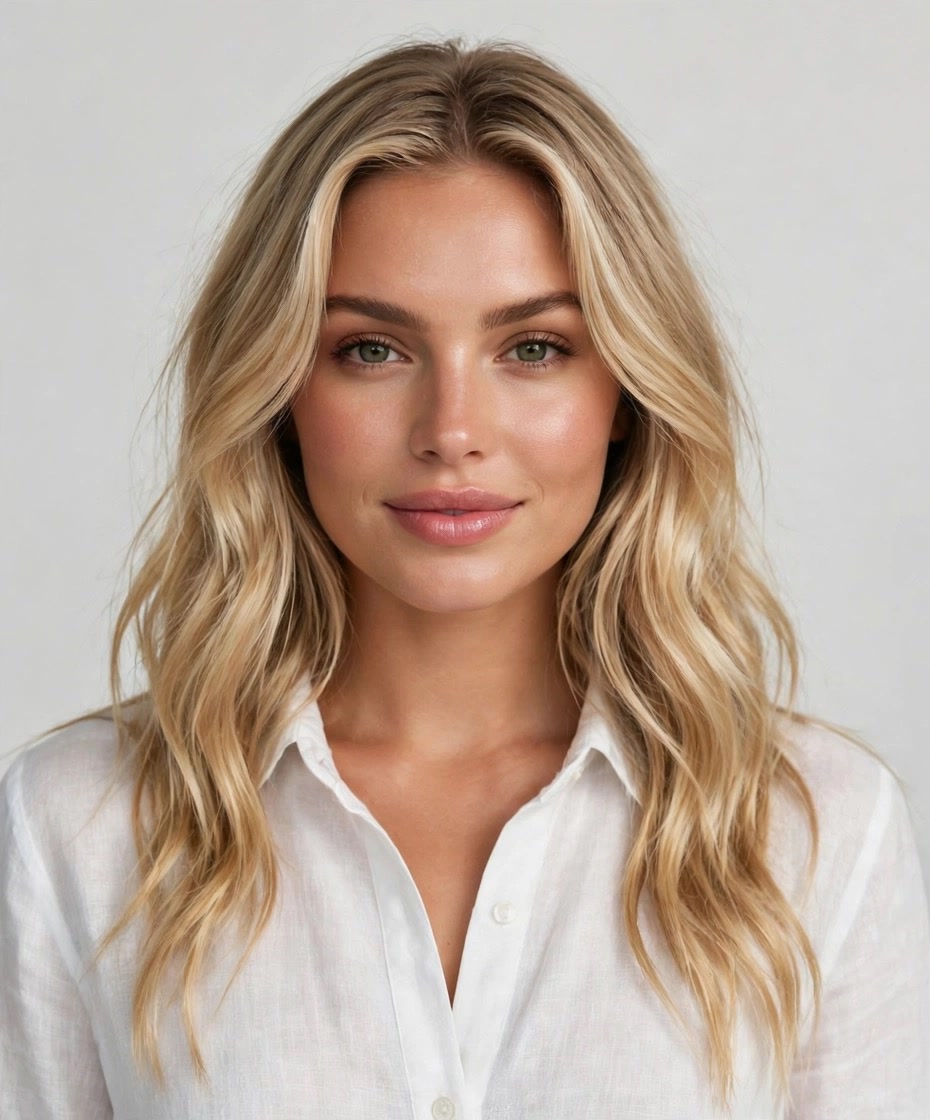
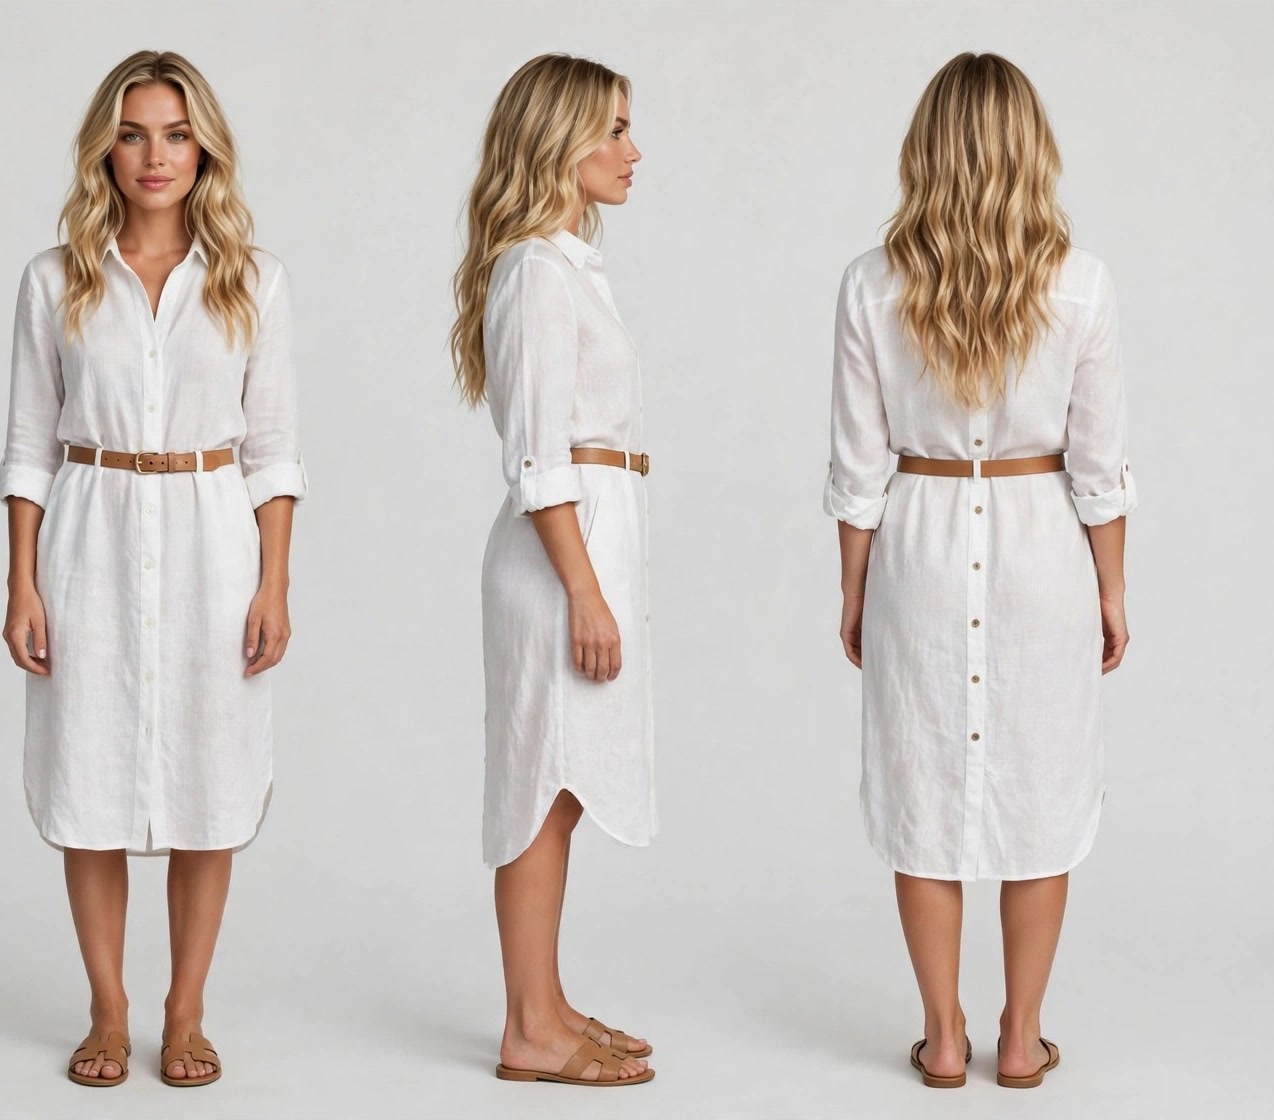
Reference images: image 1 is her headshot (face, features, hair, makeup); image 2 is a front / side / back three-view of the same woman (outfit, accessories, shoes, body). Keep exactly this face, hair and outfit in every frame. She is a 25-year-old woman with a polished Instagram look.

Golden hour beach. Scene: a wide sandy beach at sunset, gentle waves, the sun low over the ocean, footprints in wet sand, a light sea breeze.
Camera: the viewer walking a few steps behind her, one continuous take, smooth natural movement.
0.0–2.0 s: she walks barefoot along the waterline away from the camera, sandals hanging from one hand, the breeze moving her hair and the hem of her shirt dress.
2.0–3.5 s: she slows down and looks back over her shoulder at the lens with a bright smile.
3.5–5.5 s: she turns around, walks backwards for a few steps and reaches one hand toward the camera, palm up, saying: "Come on, the sun's going down!"
5.5–7.5 s: the camera moves closer; she laughs and pushes her windblown hair off her face, eyes on the lens.
7.5–9.0 s: she takes a little splash step in the shallow water and glances back with a playful grin.
9.0–10.0 s: she stops and faces the camera with the sunset behind her, tilts her head and smiles softly, holding eye contact.
Mood: carefree, warm, inviting, romantic but natural.
Lighting: golden backlight, soft lens flare, warm skin tones, rim light on her hair.

Audio: dreamy indie pop music with soft waves and wind; her line is clear, natural American English; no other voices, no laugh track.
Style: realistic Instagram Reel shot on an iPhone, vertical 9:16, natural colors, crisp focus on her face, gentle handheld motion.
Avoid: changing her face or outfit, revealing or low-cut clothing, see-through fabric, extra fingers, warped hands, strangers staring at the camera, on-screen text, subtitles, watermark.Have you read this one?参照画像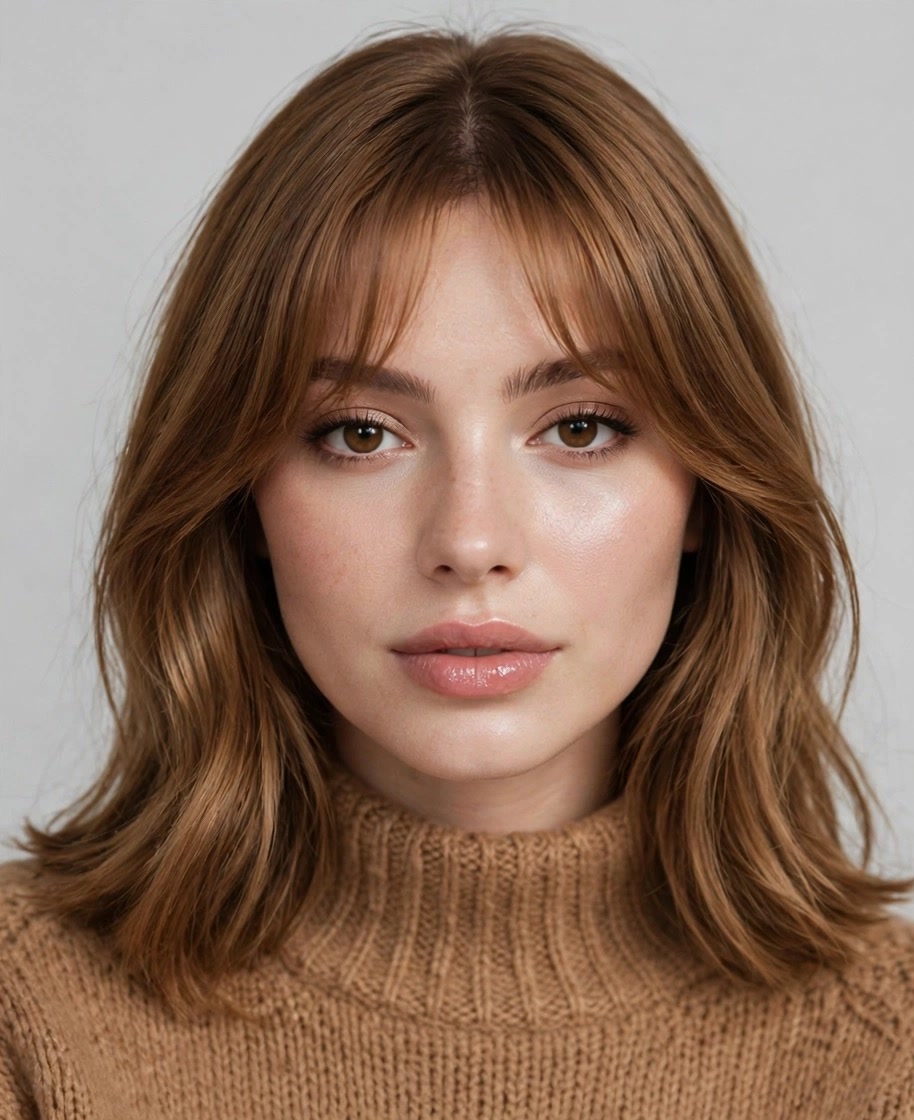
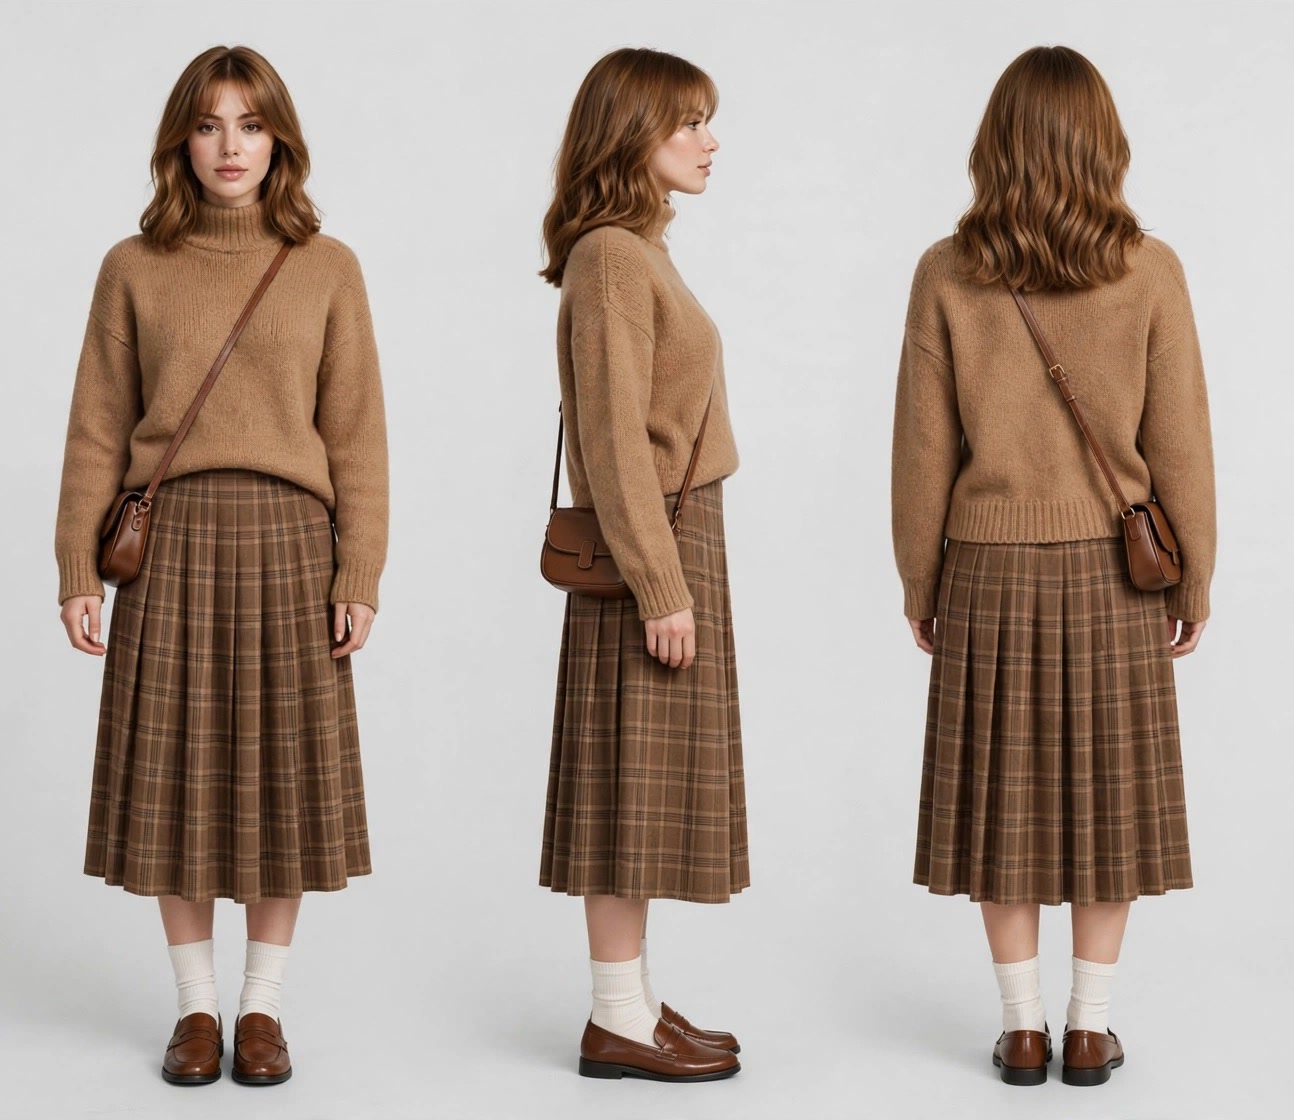
Reference images: image 1 is her headshot (face, features, hair, makeup); image 2 is a front / side / back three-view of the same woman (outfit, accessories, shoes, body). Keep exactly this face, hair and outfit in every frame. She is a 25-year-old woman with a polished Instagram look.

Bookstore. Scene: a cozy independent bookstore, tall wooden shelves, warm reading lamps, a rolling ladder, soft afternoon light, a few customers far in the background.
Camera: the viewer standing in the aisle facing her, one continuous take, a slow push-in.
0.0–1.5 s: she peeks out from behind the end of a bookshelf, only half her face visible, eyes on the lens.
1.5–3.0 s: she steps out holding a book up so it covers her nose and mouth, her eyes smiling above it.
3.0–4.5 s: she slowly lowers the book to reveal a playful smile.
4.5–6.5 s: she taps the cover and whispers: "Have you read this one?"
6.5–8.0 s: she leans her shoulder against the shelf, hugging the book to her chest, and tilts her head.
8.0–10.0 s: she bites back a smile, glances down, then looks up again through her lashes and holds eye contact.
Mood: sweet, curious, playful, intimate but wholesome.
Lighting: warm tungsten lamps, soft window light, cozy amber tones.
Book covers stay plain, with no readable text.

Audio: soft piano and acoustic guitar music with a quiet bookstore ambience; her line is clear, natural American English; no other voices, no laugh track.
Style: realistic Instagram Reel shot on an iPhone, vertical 9:16, natural colors, crisp focus on her face, gentle handheld motion.
Avoid: changing her face or outfit, revealing or low-cut clothing, see-through fabric, extra fingers, warped hands, strangers staring at the camera, on-screen text, subtitles, watermark.Mine's better.参照画像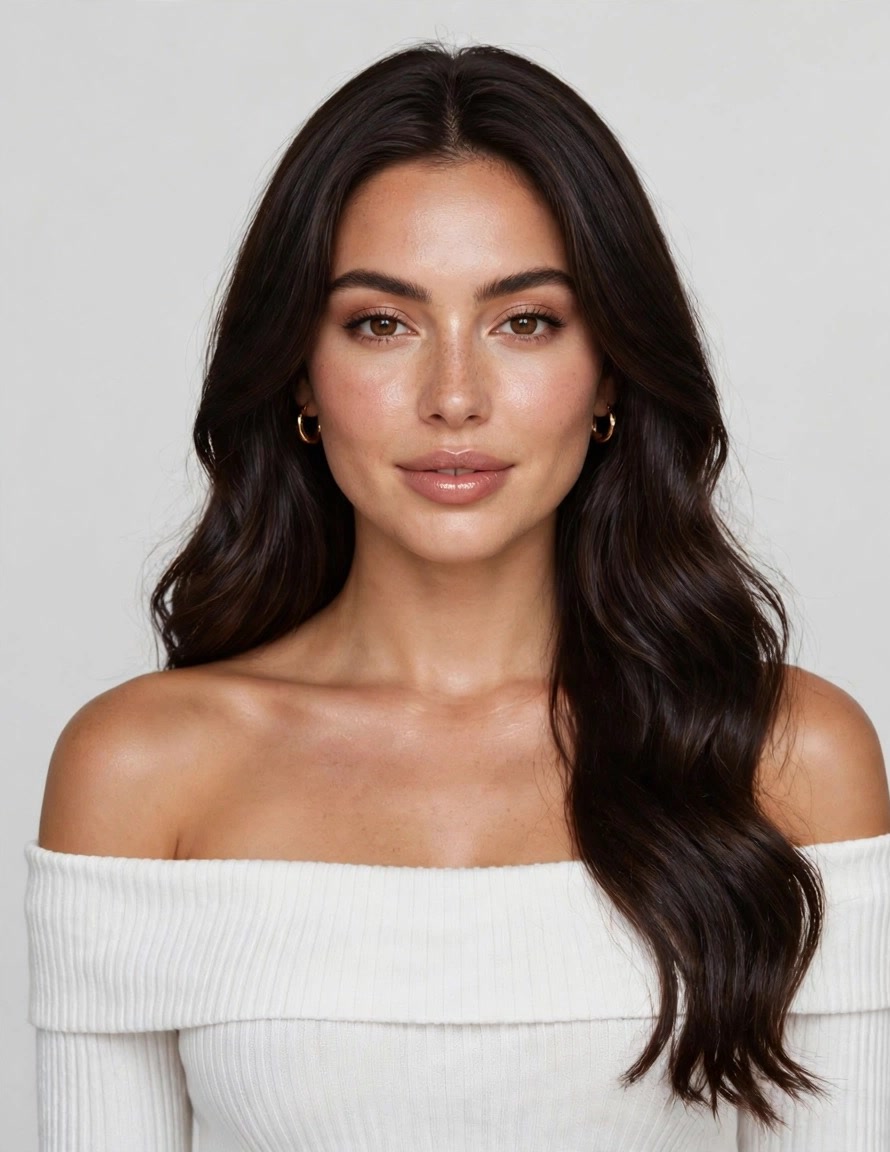
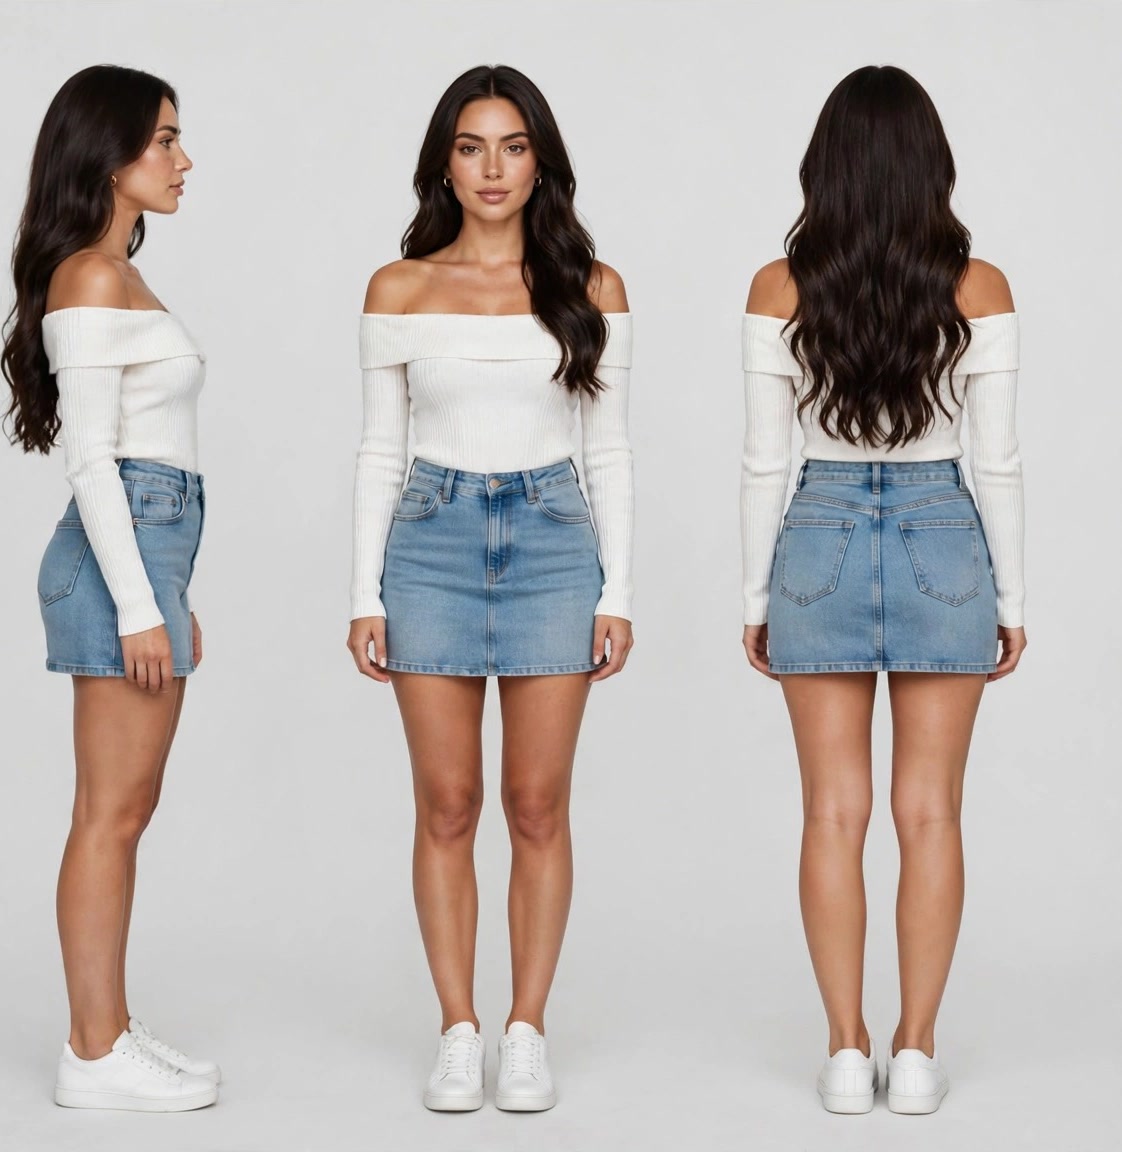
Reference images: image 1 is her headshot (face, features, hair, makeup); image 2 is a front / side / back three-view of the same woman in a light summer outfit (outfit, accessories, shoes, body). Keep exactly this face, hair and outfit in every frame. She is a 25-year-old woman with a polished Instagram look.

Outdoor café date. Scene: a sunny café terrace on a quiet European-style street, a small round marble table with two cappuccinos and a croissant, a striped awning, potted flowers, soft morning sun.
Camera: the viewer's point of view sitting across the small table, very close to her, eye level.
0.0–1.5 s: she rests her chin on her interlaced fingers, watching the lens with a slow half-smile.
1.5–3.0 s: she reaches across, takes the viewer's cappuccino instead of her own and sips it, eyes on the lens over the cup.
3.0–4.5 s: she wipes a little milk foam from her lip with her thumb and laughs.
4.5–6.0 s: she says, teasing: "Mine's better." and slides her own cup toward the camera.
6.0–8.0 s: she leans in close to the lens on her elbows, her bare shoulders catching the sun, lightly bites her lower lip and holds eye contact.
8.0–10.0 s: she leans back, tucks her hair behind her ear and gives one playful wink.
Lighting: soft warm morning sun, gentle highlights on her hair and shoulders.
Flirt cues (natural and playful, never explicit): long lingering eye contact with the lens, a slow half-smile, lightly biting her lower lip once, glancing down and then back up through her lashes, leaning in close to the lens as if sharing a secret, at most one playful wink. She is clearly enjoying the viewer's company.

Audio: light French café jazz and soft street ambience; her line is clear, natural American English; no other voices, no laugh track.
Style: realistic Instagram Reel shot on an iPhone, vertical 9:16, warm natural colors, crisp focus on her face, gentle handheld motion, one continuous take.
Avoid: changing her face or outfit, cleavage, lingerie, swimwear, see-through fabric, kissing, touching her own body suggestively, extra fingers, warped hands, strangers staring at the camera, on-screen text, subtitles, watermark.Sit with me.参照画像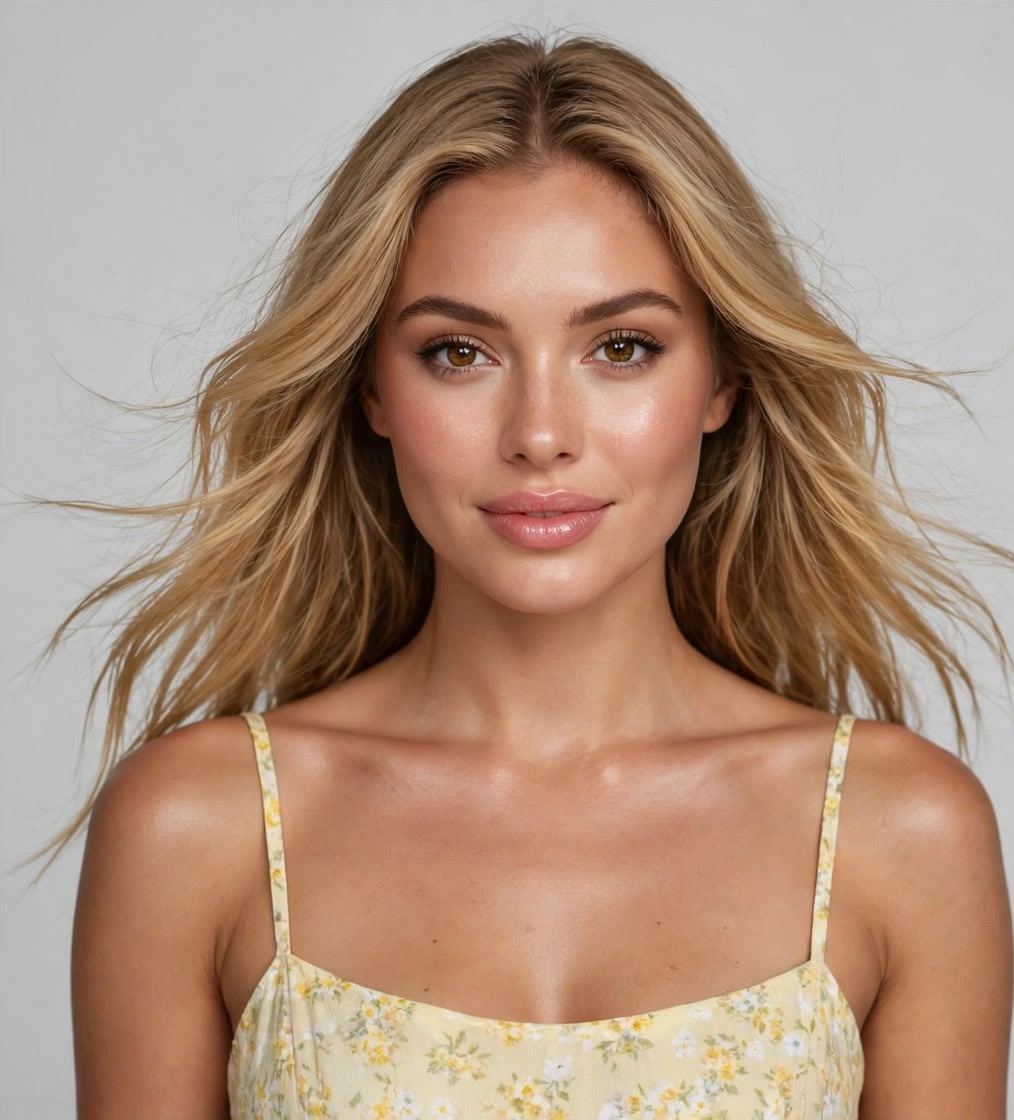
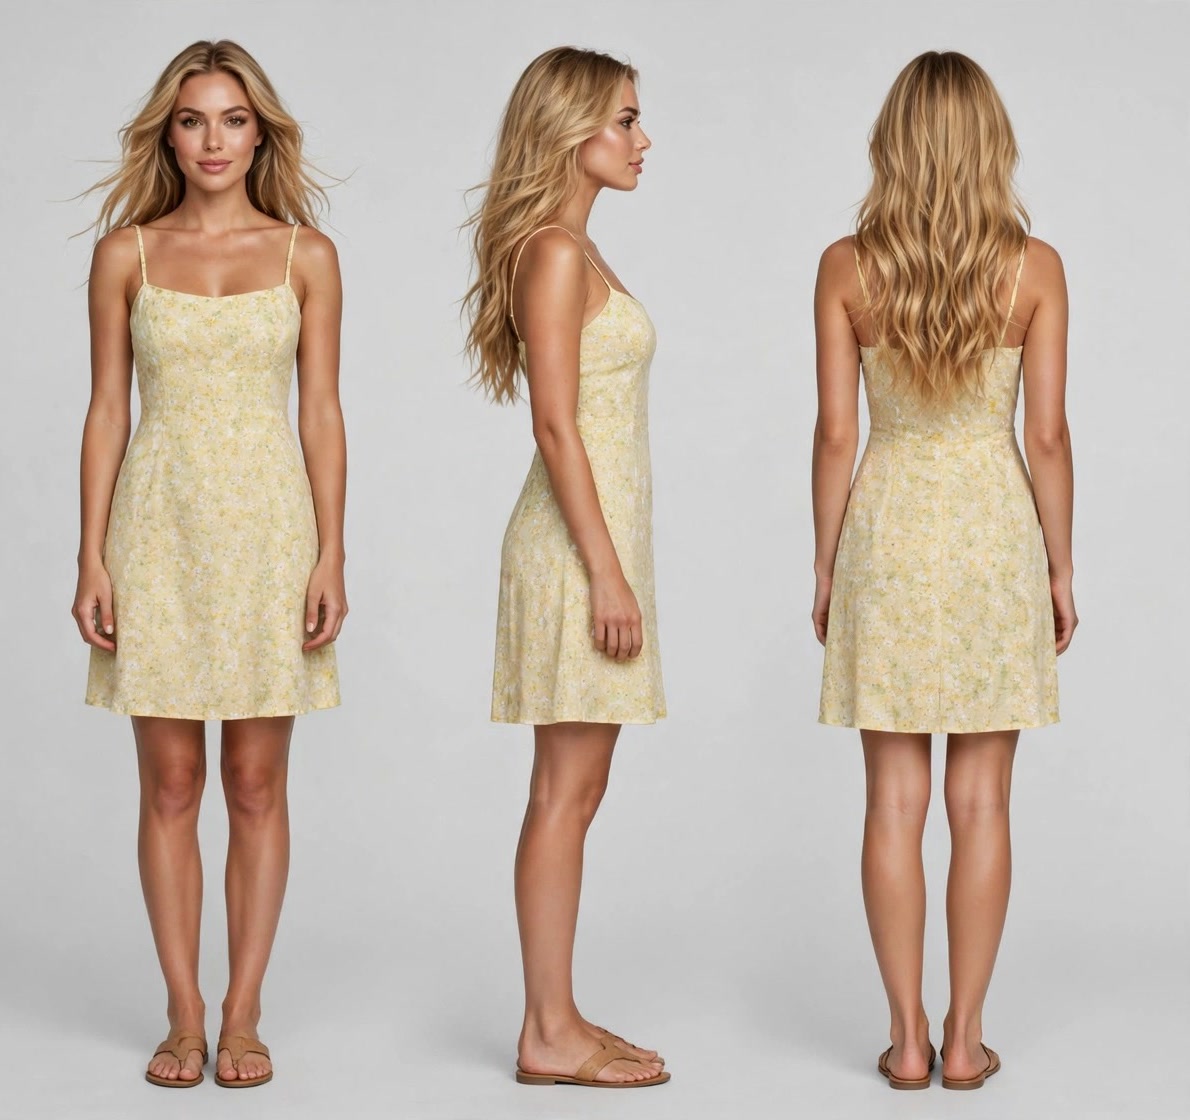
Reference images: image 1 is her headshot (face, features, hair, makeup); image 2 is a front / side / back three-view of the same woman in a light summer outfit (outfit, accessories, shoes, body). Keep exactly this face, hair and outfit in every frame. She is a 25-year-old woman with a polished Instagram look.

Sunset pier. Scene: a wooden pier over calm water at sunset, golden light, a pink and orange sky, a gentle breeze.
Camera: the viewer walking up to her and then sitting down right beside her.
0.0–2.0 s: she sits on the edge of the pier, legs dangling over the water, sandals beside her, the breeze lifting her hair and the hem of her sundress.
2.0–3.5 s: she hears the viewer, looks back over her shoulder and her face breaks into a soft smile.
3.5–5.0 s: she pats the boards right next to her and says: "Sit with me."
5.0–7.0 s: the camera lowers to sit beside her, very close; she turns her face to the lens, sunset light on her skin, and lets her gaze linger.
7.0–8.5 s: she leans her shoulder lightly toward the camera, looks down at the water, then back up through her lashes.
8.5–10.0 s: she rests her chin on her hand and smiles at the lens as the sun dips behind her.
Lighting: golden backlight, soft lens flare, warm glowing skin.
Flirt cues (natural and playful, never explicit): long lingering eye contact with the lens, a slow half-smile, lightly biting her lower lip once, glancing down and then back up through her lashes, leaning in close to the lens as if sharing a secret, at most one playful wink. She is clearly enjoying the viewer's company.

Audio: dreamy acoustic indie music with soft water and wind; her line is clear, natural American English; no other voices, no laugh track.
Style: realistic Instagram Reel shot on an iPhone, vertical 9:16, warm natural colors, crisp focus on her face, gentle handheld motion, one continuous take.
Avoid: changing her face or outfit, cleavage, lingerie, swimwear, see-through fabric, kissing, touching her own body suggestively, extra fingers, warped hands, strangers staring at the camera, on-screen text, subtitles, watermark.This part reminds me of you.参照画像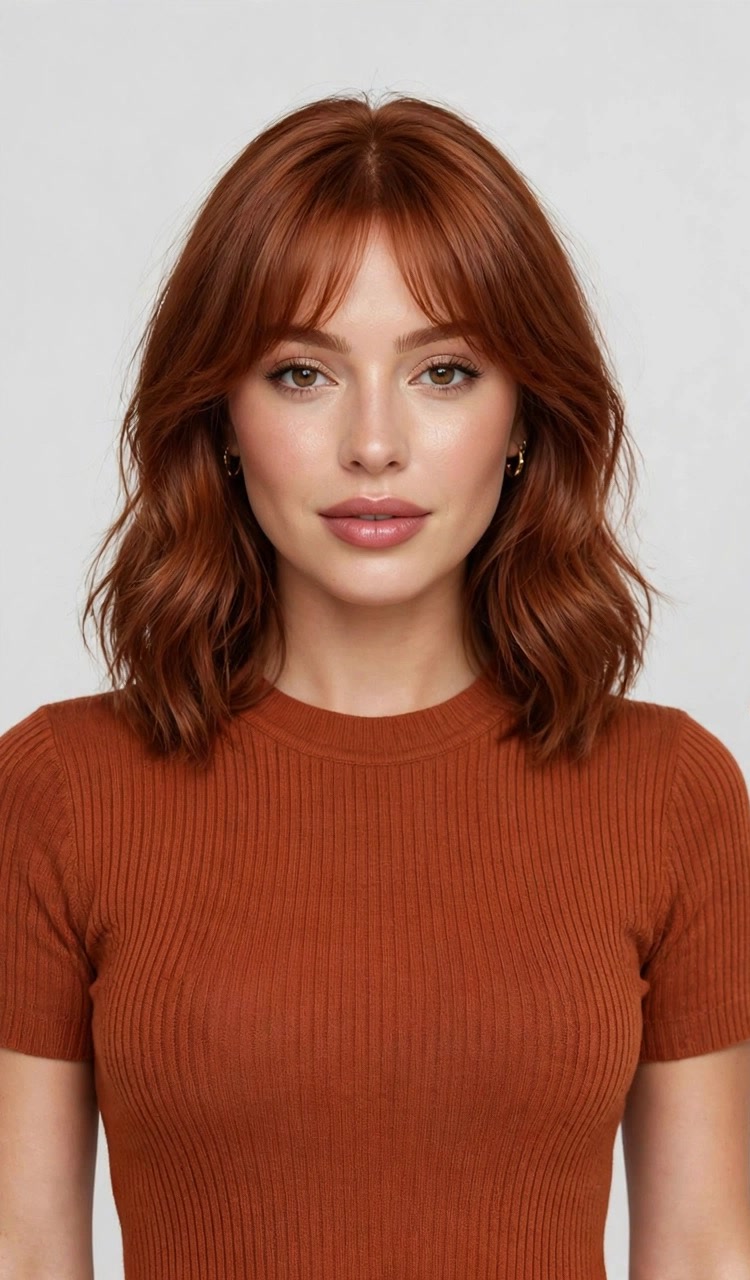
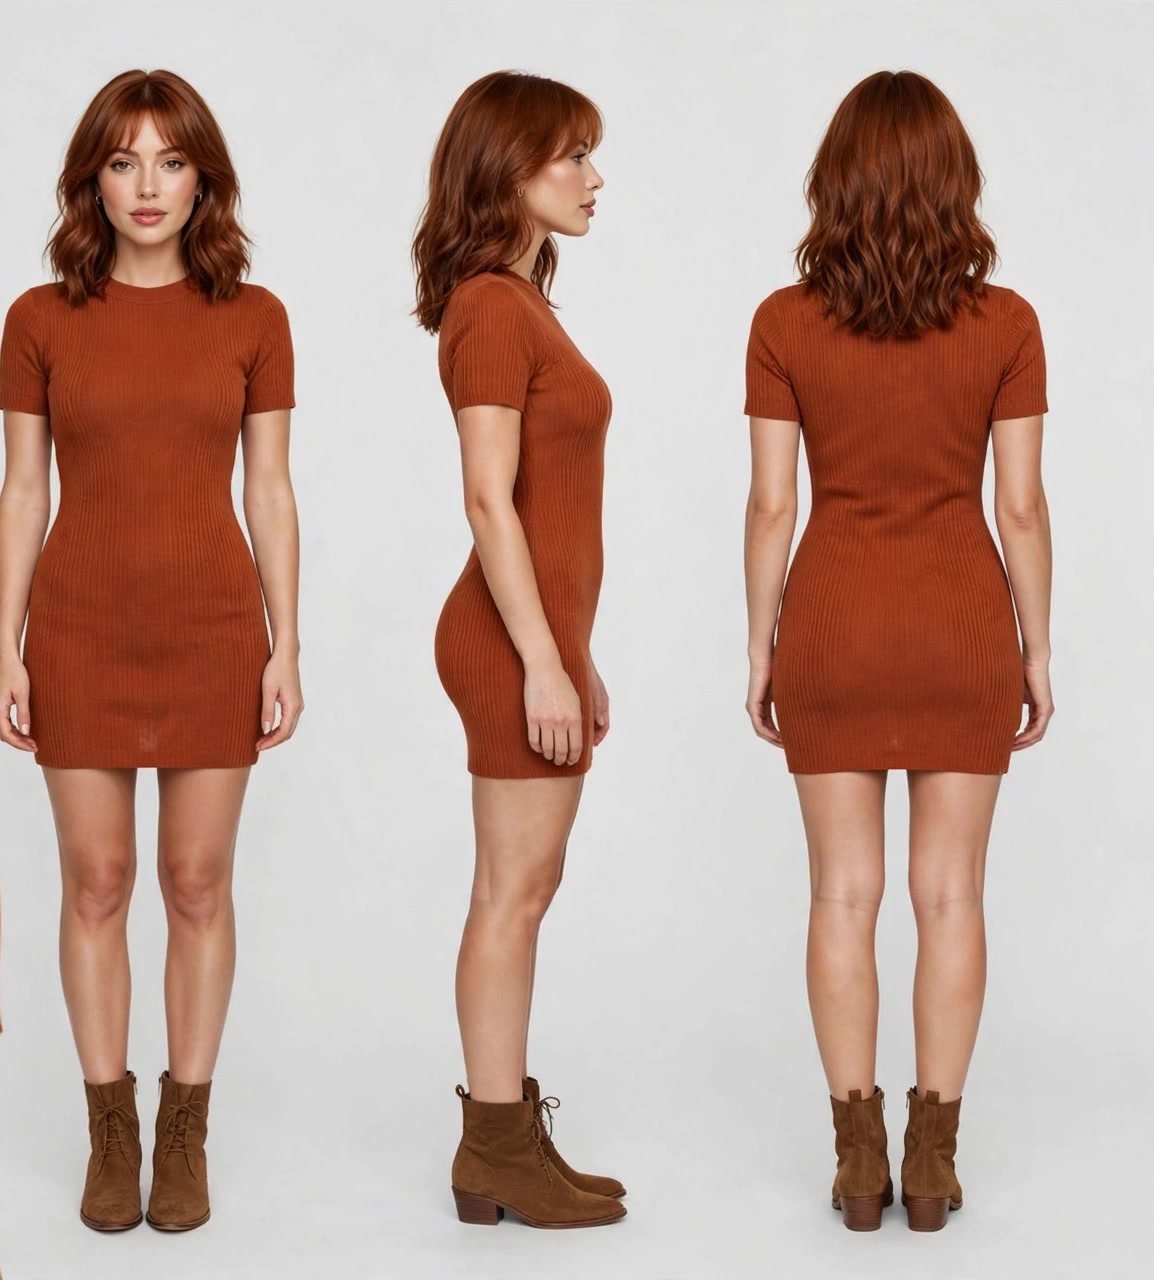
Reference images: image 1 is her headshot (face, features, hair, makeup); image 2 is a front / side / back three-view of the same woman in a light summer outfit (outfit, accessories, shoes, body). Keep exactly this face, hair and outfit in every frame. She is a 25-year-old woman with a polished Instagram look.

Bookstore reading nook. Scene: a cozy window seat in an independent bookstore, cushions, stacks of books, warm lamp light mixed with late-afternoon sun.
Camera: the viewer sitting down next to her on the window seat, close.
0.0–1.5 s: she sits curled up on the window seat reading an open book, a strand of hair falling across her face.
1.5–3.0 s: she glances up over the top of the book at the lens, then back down, hiding a smile.
3.0–5.0 s: she lowers the book and says softly: "This part reminds me of you."
5.0–7.0 s: she shifts closer and holds the open book toward the camera, her face close to the lens.
7.0–8.5 s: she watches the viewer's reaction, lightly bites her lower lip and laughs quietly.
8.5–10.0 s: she closes the book against her chest, tilts her head and holds eye contact with a soft smile.
Book pages and covers stay plain, with no readable text.
Lighting: warm amber lamps, soft window light on her face.
Flirt cues (natural and playful, never explicit): long lingering eye contact with the lens, a slow half-smile, lightly biting her lower lip once, glancing down and then back up through her lashes, leaning in close to the lens as if sharing a secret, at most one playful wink. She is clearly enjoying the viewer's company.

Audio: soft piano and acoustic guitar music with a quiet bookstore ambience; her line is clear, natural American English; no other voices, no laugh track.
Style: realistic Instagram Reel shot on an iPhone, vertical 9:16, warm natural colors, crisp focus on her face, gentle handheld motion, one continuous take.
Avoid: changing her face or outfit, cleavage, lingerie, swimwear, see-through fabric, kissing, touching her own body suggestively, extra fingers, warped hands, strangers staring at the camera, on-screen text, subtitles, watermark.Just one bite.参照画像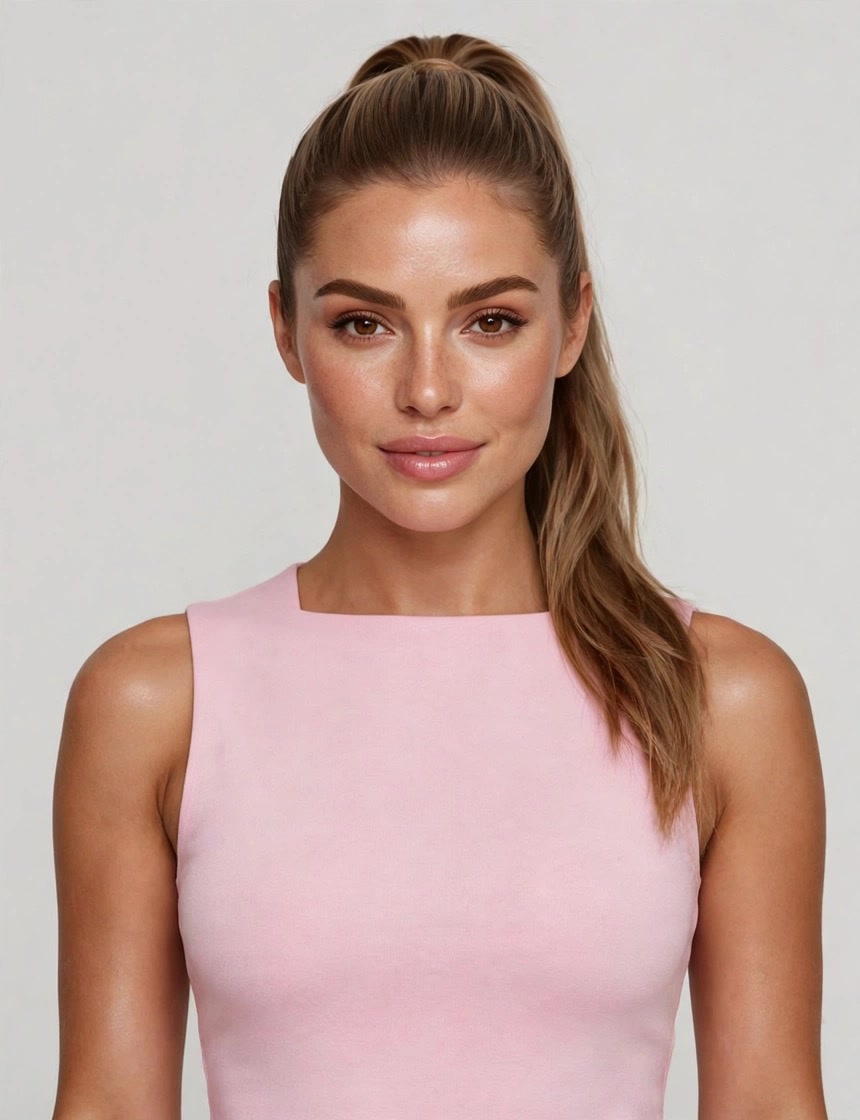
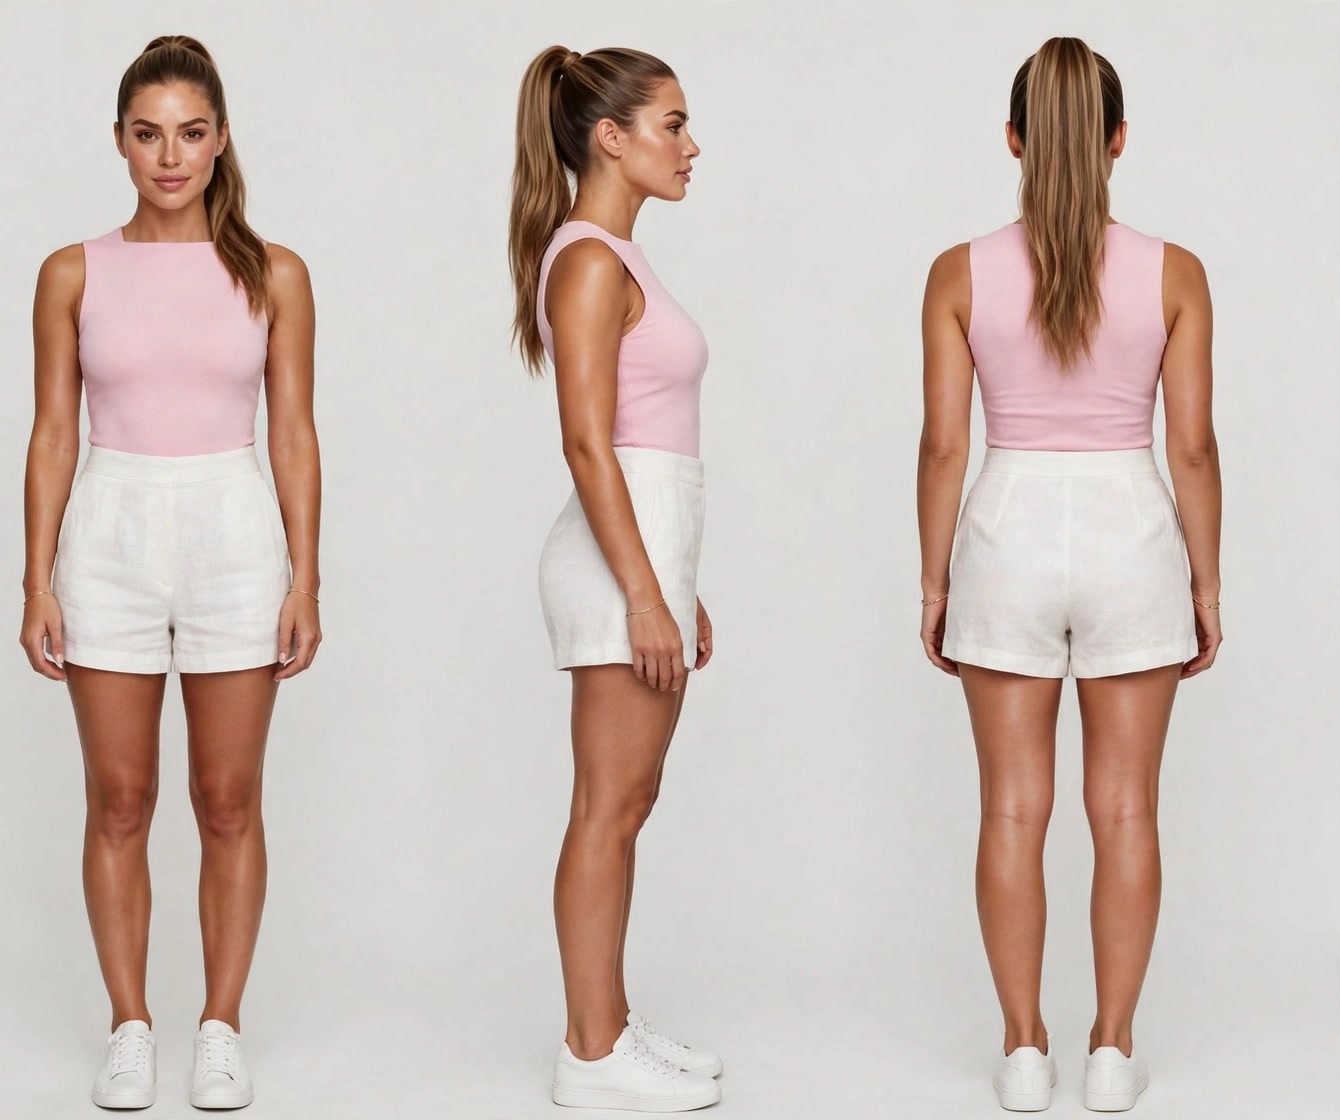
Reference images: image 1 is her headshot (face, features, hair, makeup); image 2 is a front / side / back three-view of the same woman in a light summer outfit (outfit, accessories, shoes, body). Keep exactly this face, hair and outfit in every frame. She is a 25-year-old woman with a polished Instagram look.

Ice cream on the promenade. Scene: a sunny seaside promenade in summer, pastel shopfronts, palm trees, people strolling far in the background.
Camera: the viewer walking beside her, then facing her.
0.0–1.5 s: she walks along holding a strawberry ice-cream cone and takes a small bite.
1.5–3.0 s: she notices the viewer watching and holds the cone out toward the camera, eyebrows raised.
3.0–4.5 s: as the camera leans in, she pulls it back with a playful laugh and says: "Just one bite."
4.5–6.5 s: she holds it out again, closer this time, watching the lens with a teasing half-smile.
6.5–8.5 s: she gets a tiny dot of ice cream on the tip of her nose, laughs and wipes it off.
8.5–10.0 s: she swings her ponytail, turns to keep walking and glances back at the lens with a wink.
Lighting: bright summer sun, warm tones, soft shadows.
Flirt cues (natural and playful, never explicit): long lingering eye contact with the lens, a slow half-smile, lightly biting her lower lip once, glancing down and then back up through her lashes, leaning in close to the lens as if sharing a secret, at most one playful wink. She is clearly enjoying the viewer's company.

Audio: upbeat summer pop music and light seaside ambience; her line is clear, natural American English; no other voices, no laugh track.
Style: realistic Instagram Reel shot on an iPhone, vertical 9:16, warm natural colors, crisp focus on her face, gentle handheld motion, one continuous take.
Avoid: changing her face or outfit, cleavage, lingerie, swimwear, see-through fabric, kissing, touching her own body suggestively, extra fingers, warped hands, strangers staring at the camera, on-screen text, subtitles, watermark.Open up.参照画像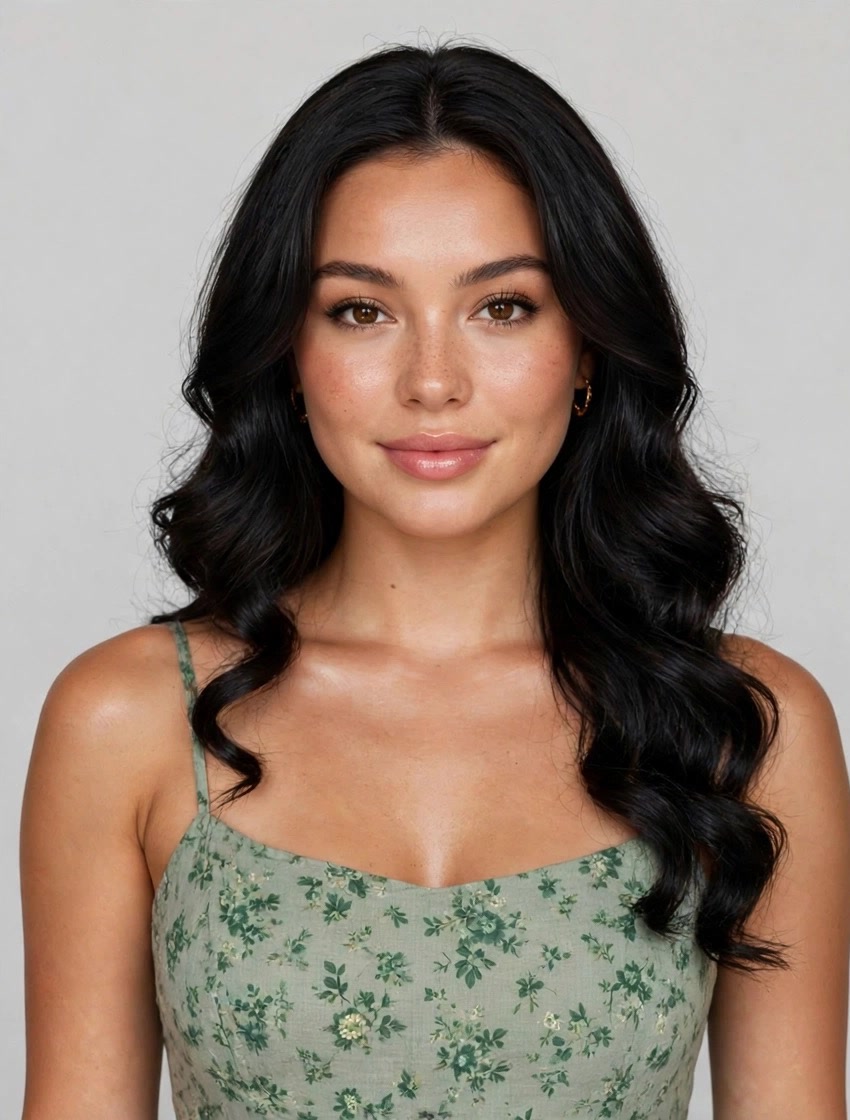
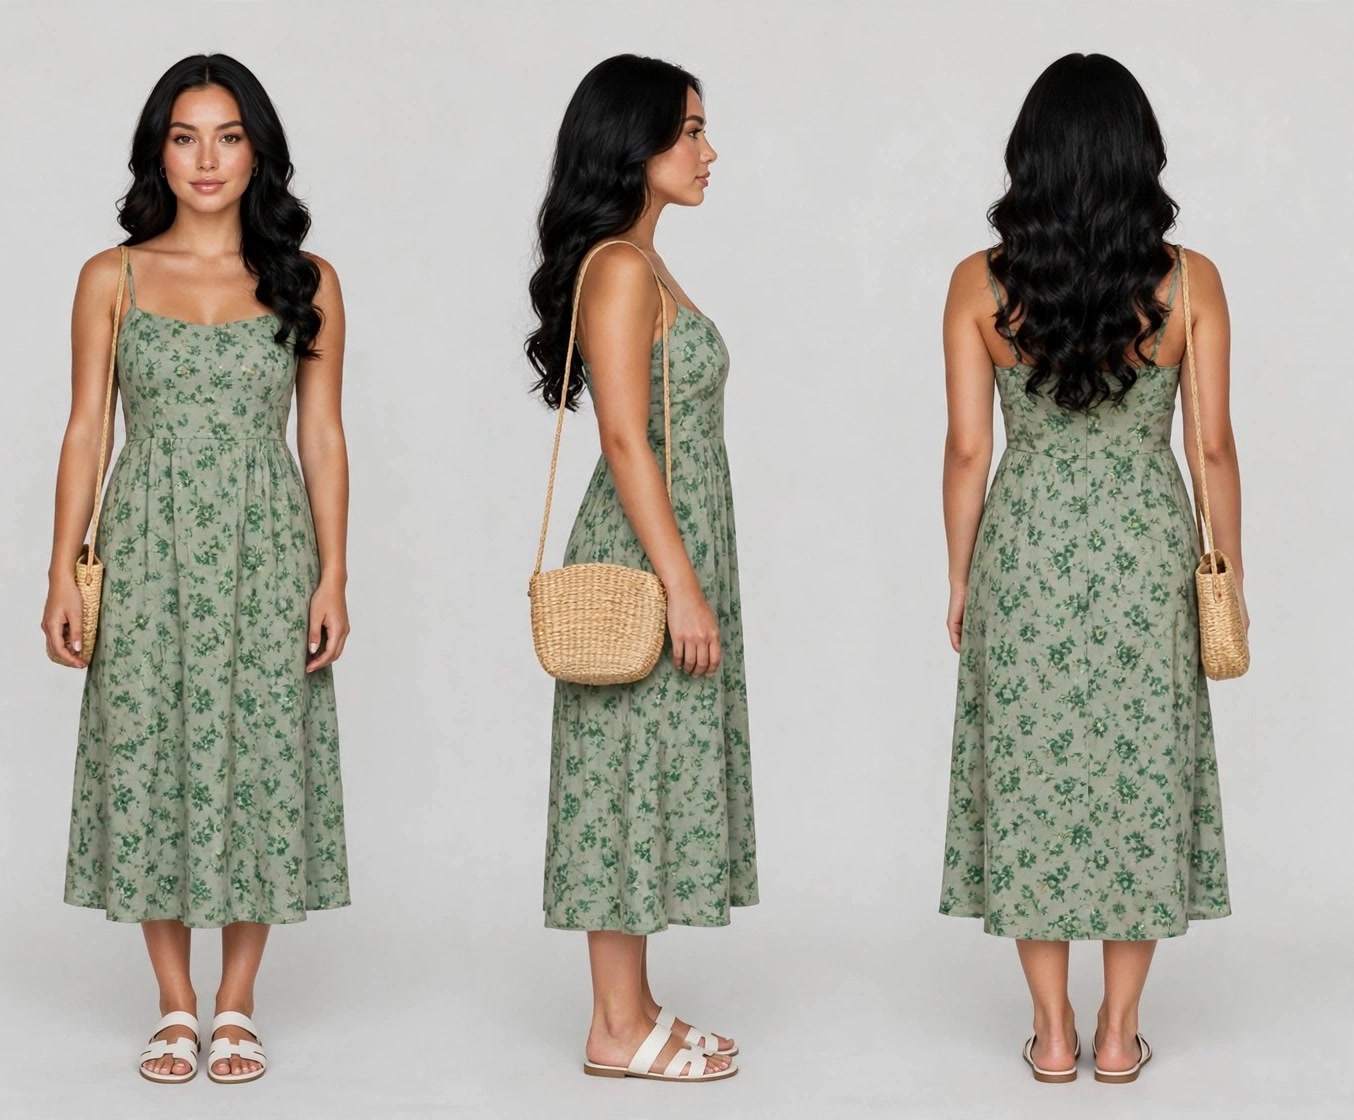
Reference images: image 1 is her headshot (face, features, hair, makeup); image 2 is a front / side / back three-view of the same woman in a light summer outfit (outfit, accessories, shoes, body). Keep exactly this face, hair and outfit in every frame. She is a 25-year-old woman with a polished Instagram look.

Park picnic. Scene: a summer picnic in a park, a checkered blanket on the grass under a big tree, a wicker basket, a bowl of strawberries, dappled golden sunlight.
Camera: the viewer lying on the blanket facing her, low angle.
0.0–2.0 s: she lies on her side propped on one elbow, her sundress spread over the blanket, twirling a daisy and smiling at the lens.
2.0–3.5 s: she picks a strawberry from the bowl and holds it toward the camera.
3.5–5.0 s: she says, playful: "Open up." and brings it close to the lens.
5.0–6.5 s: she pulls it back at the last second, laughs and takes a bite herself.
6.5–8.5 s: she tucks the daisy behind her ear, rests her cheek on her hand and holds eye contact with a slow smile.
8.5–10.0 s: she offers the other half of the strawberry to the camera again, eyes sparkling.
Lighting: dappled warm sunlight through leaves, soft golden glow.
Flirt cues (natural and playful, never explicit): long lingering eye contact with the lens, a slow half-smile, lightly biting her lower lip once, glancing down and then back up through her lashes, leaning in close to the lens as if sharing a secret, at most one playful wink. She is clearly enjoying the viewer's company.

Audio: gentle ukulele and acoustic music with birdsong; her line is clear, natural American English; no other voices, no laugh track.
Style: realistic Instagram Reel shot on an iPhone, vertical 9:16, warm natural colors, crisp focus on her face, gentle handheld motion, one continuous take.
Avoid: changing her face or outfit, cleavage, lingerie, swimwear, see-through fabric, kissing, touching her own body suggestively, extra fingers, warped hands, strangers staring at the camera, on-screen text, subtitles, watermark.Listen to this part.参照画像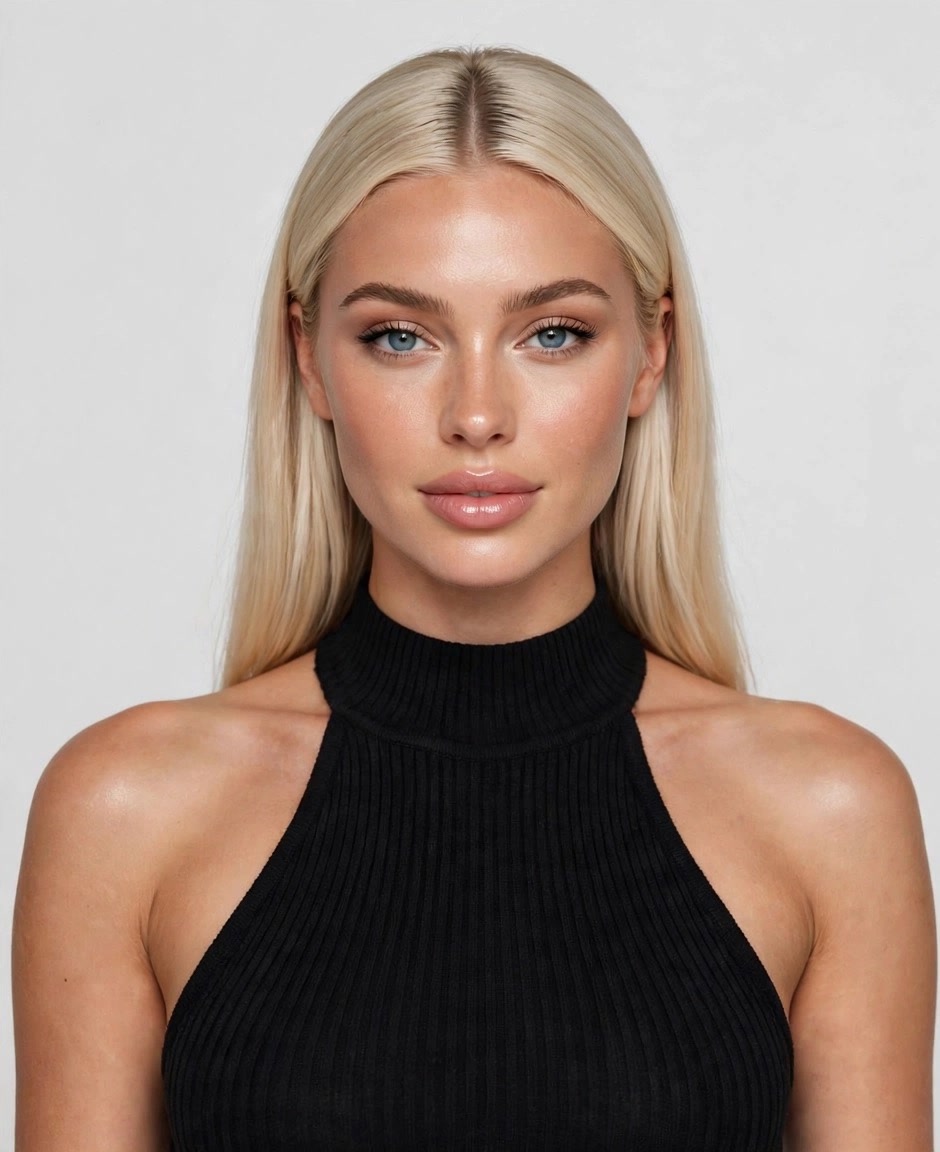
Reference images: image 1 is her headshot (face, features, hair, makeup); image 2 is a front / side / back three-view of the same woman in a light summer outfit (outfit, accessories, shoes, body). Keep exactly this face, hair and outfit in every frame. She is a 25-year-old woman with a polished Instagram look.

Record store listening booth. Scene: a vintage record store with a small wooden listening booth, shelves and crates of vinyl, a warm amber glow.
Camera: the viewer standing inside the small booth with her, very close.
0.0–1.5 s: she flips through records in a crate, pulls one out and smiles at it.
1.5–3.0 s: she puts on over-ear headphones, closes her eyes and sways slightly to the music.
3.0–4.5 s: she slides one ear cup off and holds it out toward the camera, saying: "Listen to this part."
4.5–6.5 s: she leans in very close to the lens as if sharing the headphones, her eyes looking up into the lens.
6.5–8.5 s: she mouths along to the chorus with a slow smile and lightly bites her lower lip.
8.5–10.0 s: she pulls back a little, laughs and gives the viewer a playful look over her shoulder.
Record sleeves stay plain, with no readable text.
Lighting: warm amber light, soft shadows, cozy vintage tones.
Flirt cues (natural and playful, never explicit): long lingering eye contact with the lens, a slow half-smile, lightly biting her lower lip once, glancing down and then back up through her lashes, leaning in close to the lens as if sharing a secret, at most one playful wink. She is clearly enjoying the viewer's company.

Audio: a warm retro soul song playing in the booth; her line is clear, natural American English; no other voices, no laugh track.
Style: realistic Instagram Reel shot on an iPhone, vertical 9:16, warm natural colors, crisp focus on her face, gentle handheld motion, one continuous take.
Avoid: changing her face or outfit, cleavage, lingerie, swimwear, see-through fabric, kissing, touching her own body suggestively, extra fingers, warped hands, strangers staring at the camera, on-screen text, subtitles, watermark.You actually came!参照画像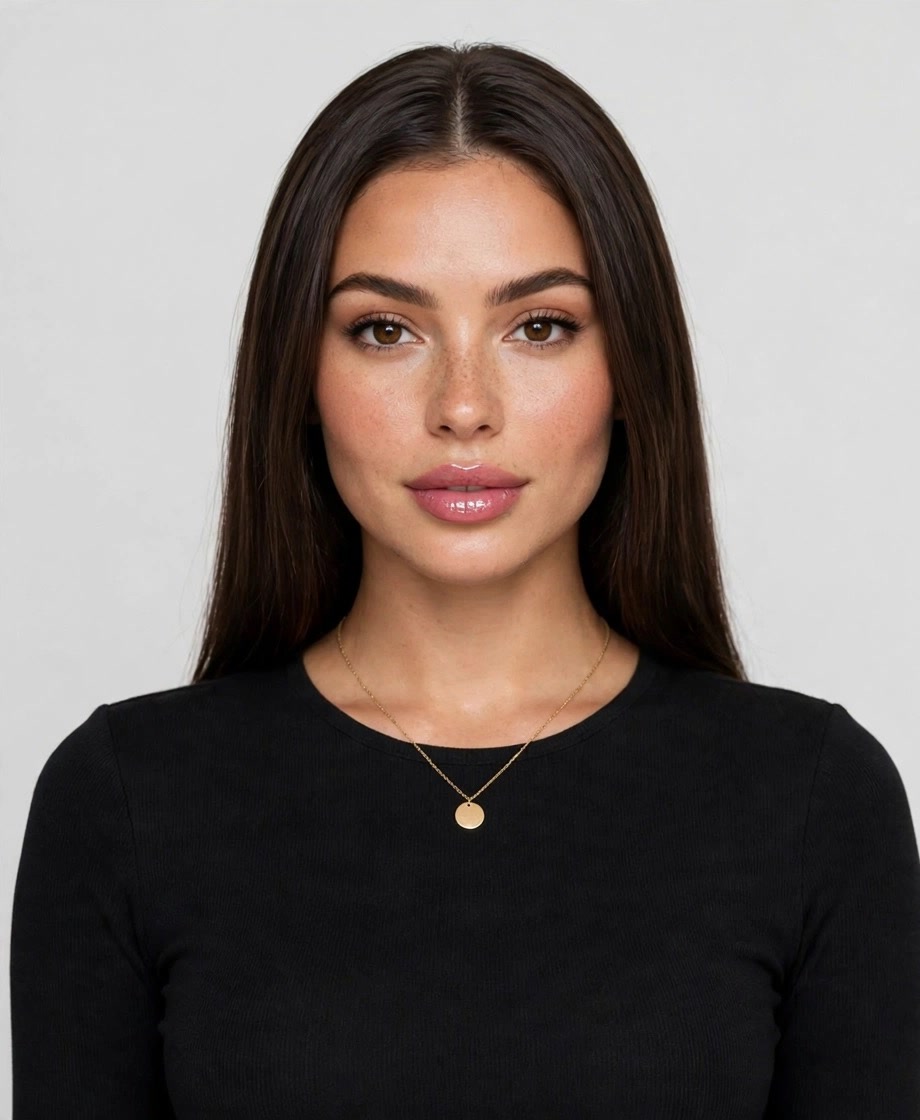
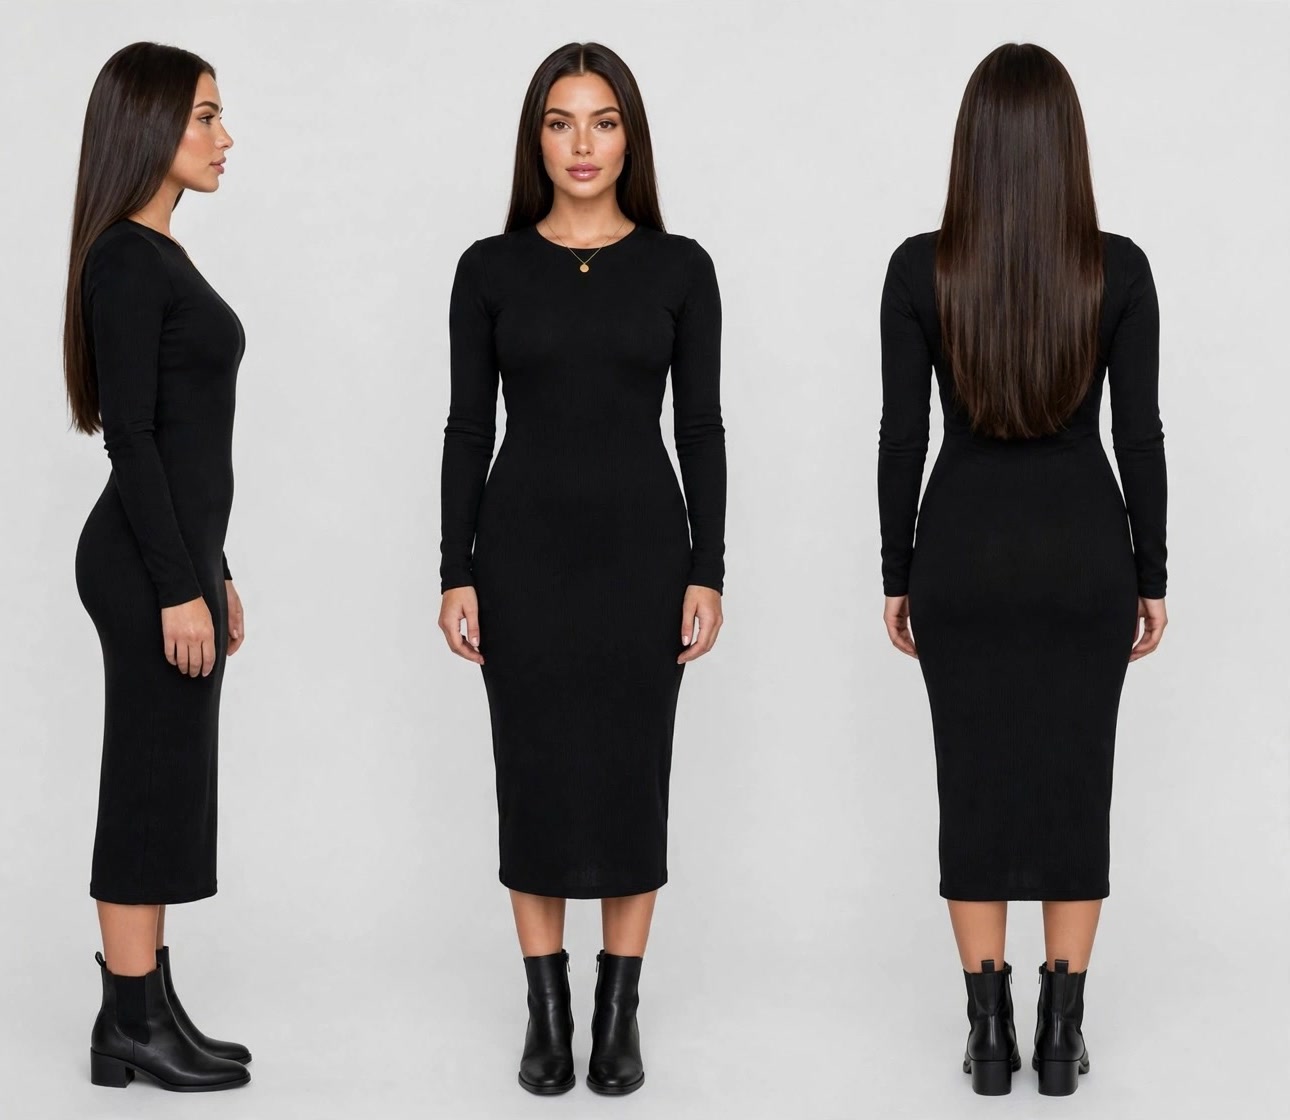
Reference images: image 1 is her headshot (face, features, hair, makeup); image 2 is a front / side / back three-view of the same woman (outfit, accessories, shoes, body). Keep exactly this face, hair and outfit in every frame. She is a 25-year-old woman with a polished Instagram look.

Rooftop at night. Scene: a rooftop bar above a city at night, warm string lights, the glowing skyline as soft bokeh behind her, a glass railing, small candles on a high table.
Camera: the viewer walking up to her at the railing, one continuous take.
0.0–1.5 s: she leans on the railing half turned away, looking out at the city lights, holding a glass of sparkling water with lime.
1.5–3.0 s: she turns her head toward the lens and her face lights up with a surprised smile.
3.0–5.0 s: she says: "You actually came!" and raises her glass toward the camera as if to clink.
5.0–7.0 s: she sweeps her hair over one shoulder, laughs softly and gives a small playful shrug.
7.0–8.5 s: she makes a small "come here" gesture with two fingers and tilts her head toward the view beside her.
8.5–10.0 s: she turns back toward the skyline but keeps looking at the lens over her shoulder, smiling.
Mood: elegant, playful, warm, confident.
Lighting: warm string lights on her face, cool city bokeh behind, a soft natural night look, no harsh flash.

Audio: chill lo-fi house music and soft city ambience; her line is clear, natural American English; no other voices, no laugh track.
Style: realistic Instagram Reel shot on an iPhone, vertical 9:16, natural colors, crisp focus on her face, gentle handheld motion.
Avoid: changing her face or outfit, revealing or low-cut clothing, see-through fabric, extra fingers, warped hands, strangers staring at the camera, on-screen text, subtitles, watermark.Okay, your turn to pick the song.参照画像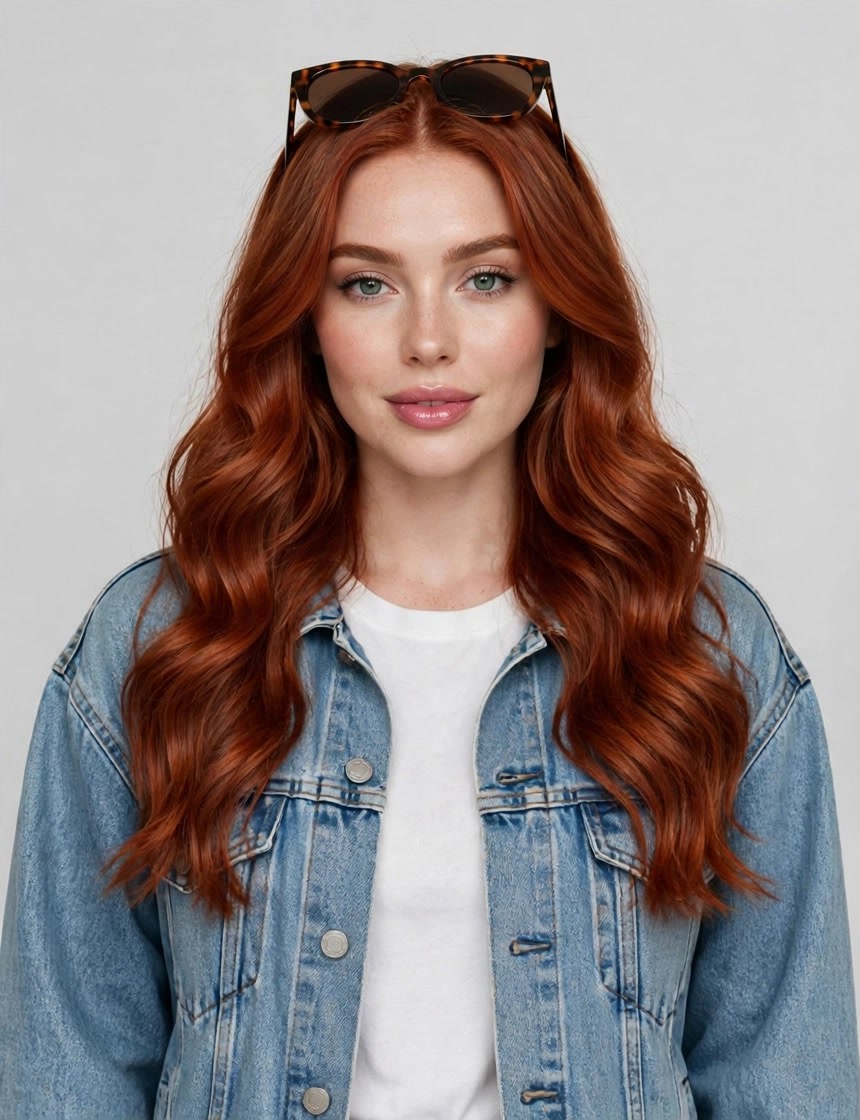
Reference images: image 1 is her headshot (face, features, hair, makeup); image 2 is a front / side / back three-view of the same woman (outfit, accessories, shoes, body). Keep exactly this face, hair and outfit in every frame. She is a 25-year-old woman with a polished Instagram look.

Road trip stop. Scene: inside a parked car at a sunny beach parking lot, engine off, she sits in the passenger seat, the ocean and palm trees visible through the windshield, sunlight across the dashboard.
Camera: the viewer's point of view from the driver's seat, angled toward her, one continuous take.
0.0–2.0 s: she sings along to the song on the radio with her eyes closed, moving her shoulders to the beat, sunglasses on.
2.0–3.5 s: she pulls her sunglasses down her nose with one finger and looks over them into the lens with a teasing smile.
3.5–5.5 s: she says: "Okay, your turn to pick the song." and hands the phone toward the camera.
5.5–7.5 s: she holds out a paper bag of fries toward the camera, offering one, eyebrows raised.
7.5–9.0 s: she rests her elbow on the open window, the breeze catching her hair, glances at the ocean, then back at the lens.
9.0–10.0 s: she pushes the sunglasses up into her hair and gives the camera a warm, easy smile.
Mood: fun, relaxed, playful, best-road-trip-ever energy.
Lighting: bright natural sunlight, warm tones, soft reflections on the glass.

Audio: upbeat summer pop music from the car speakers; her line is clear, natural American English; no other voices, no laugh track.
Style: realistic Instagram Reel shot on an iPhone, vertical 9:16, natural colors, crisp focus on her face, gentle handheld motion.
Avoid: changing her face or outfit, revealing or low-cut clothing, see-through fabric, extra fingers, warped hands, strangers staring at the camera, on-screen text, subtitles, watermark.Get under here, you're soaked!参照画像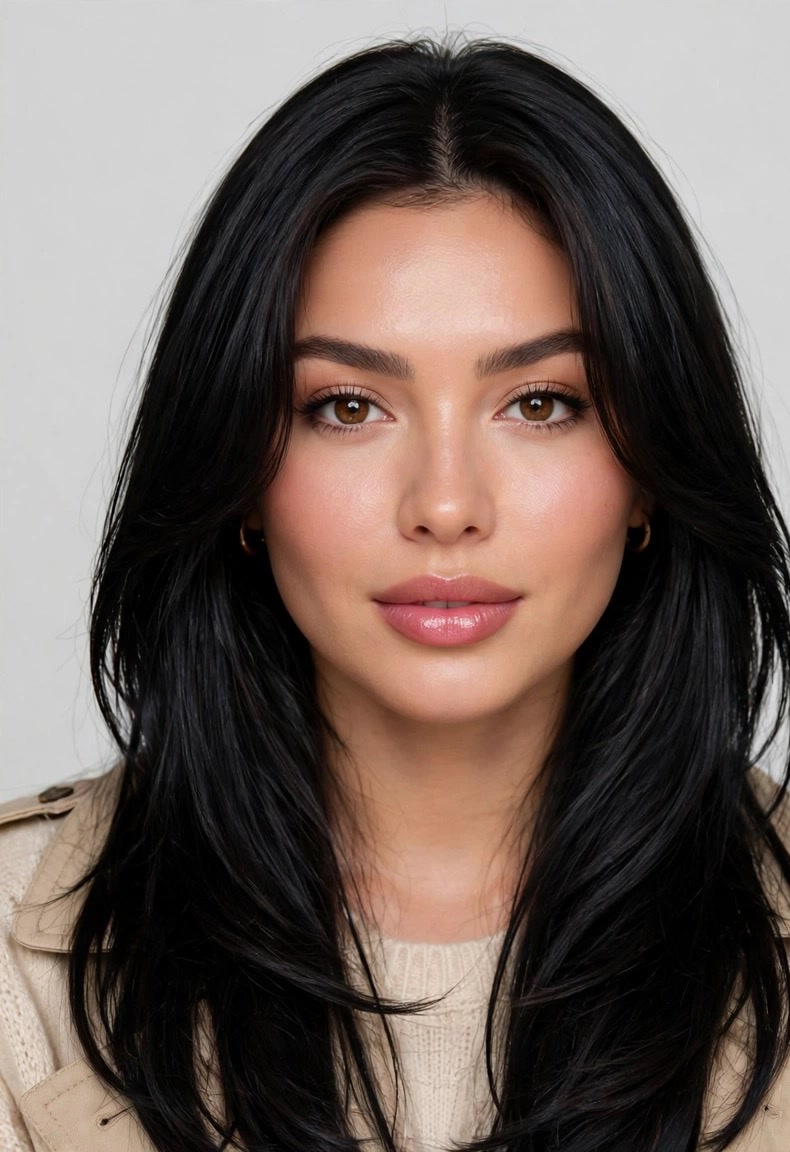
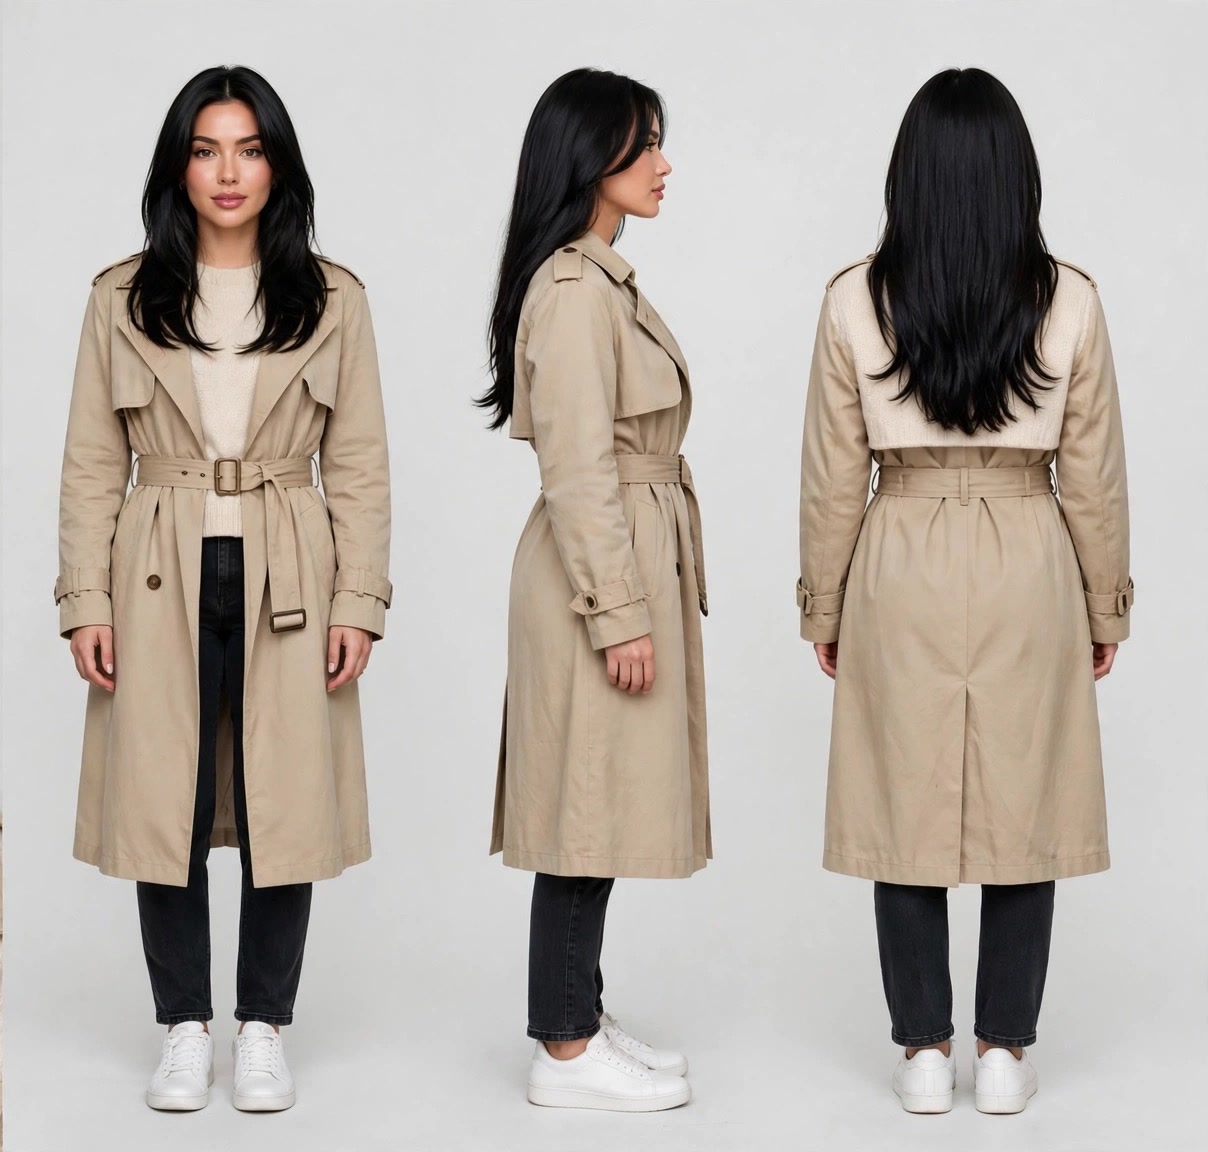
Reference images: image 1 is her headshot (face, features, hair, makeup); image 2 is a front / side / back three-view of the same woman (outfit, accessories, shoes, body). Keep exactly this face, hair and outfit in every frame. She is a 25-year-old woman with a polished Instagram look.

Rainy evening. Scene: a city sidewalk at dusk in light rain, wet pavement reflecting neon shop signs and street lights, people with umbrellas blurred in the background.
Camera: the viewer standing in the rain without an umbrella, one continuous take.
0.0–1.5 s: she walks toward the camera under a clear umbrella, raindrops on the canopy.
1.5–3.0 s: she notices the viewer getting wet, her eyes widen and she laughs.
3.0–5.0 s: she steps close and tilts the umbrella over the camera so the canopy fills the top of the frame, saying: "Get under here, you're soaked!"
5.0–7.0 s: under the umbrella, close to the lens, she shakes the rain off her hand and smiles, her face lit by the neon glow.
7.0–8.5 s: she nods toward the street as if to say "walk with me", eyebrows raised.
8.5–10.0 s: she turns slightly to start walking, still looking back at the lens with a warm smile, the umbrella over both of them.
Mood: romantic, caring, playful, cinematic.
Lighting: neon reflections, soft street lights, cool blue and warm pink tones, sparkling rain.

Audio: soft rain sounds and a gentle R&B instrumental; her line is clear, natural American English; no other voices, no laugh track.
Style: realistic Instagram Reel shot on an iPhone, vertical 9:16, natural colors, crisp focus on her face, gentle handheld motion.
Avoid: changing her face or outfit, revealing or low-cut clothing, see-through fabric, extra fingers, warped hands, strangers staring at the camera, on-screen text, subtitles, watermark.Look, isn't this spatula so handy?参照画像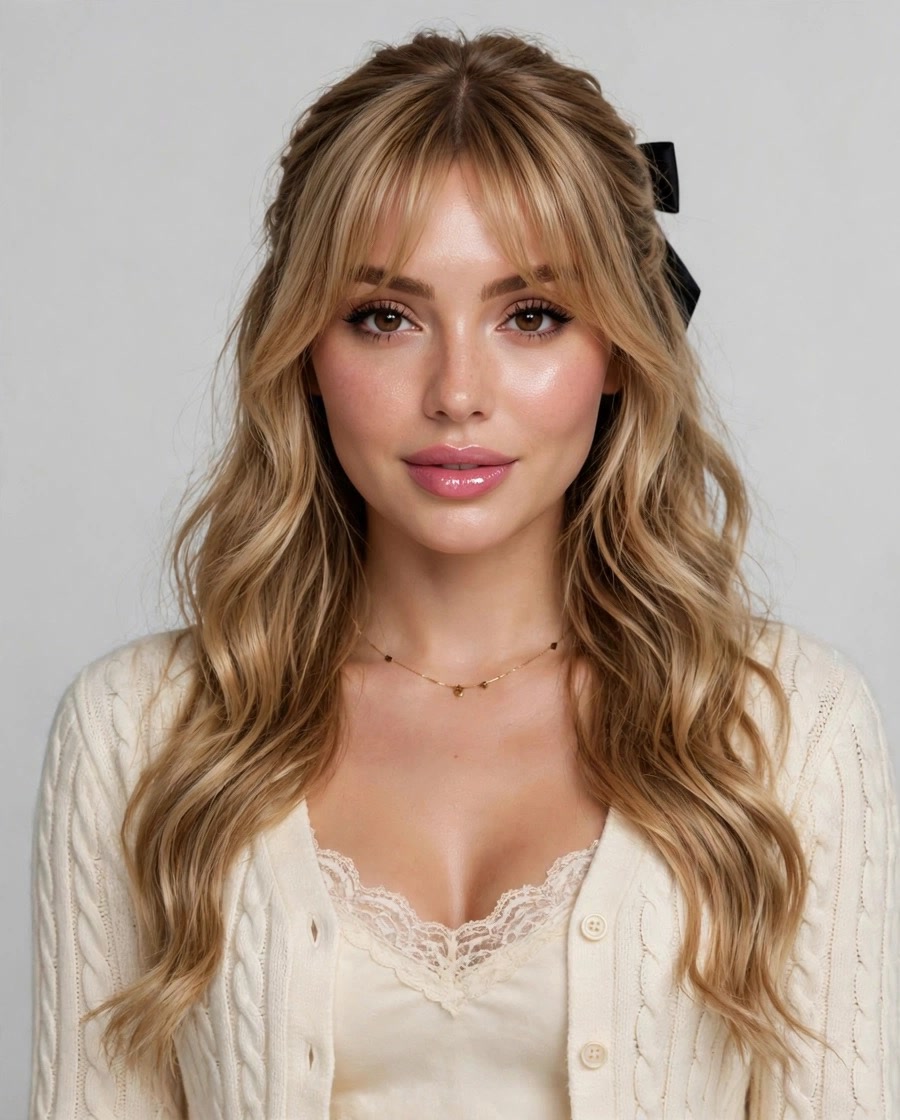
 プロンプトの元投稿 @beizhi606
参考图说明:参考图1是人物大头照(脸、五官、发型、发色、妆容都以它为准),参考图2是同一个人的三视图(服装、配饰、鞋子、身材都以它为准)。人物是 25 岁的欧美女性,Instagram 博主风格的精致妆容。下文里「原视频里」的发型、发色和穿搭描述一律忽略,以参考图为准。

中文提示词(10.00秒)
人物:
脸部: 人物的长相、五官、发型、发色和妆容严格按照。
服装和身材: 人物的服装穿搭、配饰和身材比例严格按照。镜头2里人物背对镜头,背面的服装请参考三视图的背面。
一致性: 4个镜头里都是同一个人,脸和服装全程保持一致,切镜后不能变样;镜头2镜子里的倒影也必须是同一个人、同一套服装。

道具:
镜头1:一把黑色的厨房食物夹。
镜头4:一把黑色的锅铲。

场景:
场景是一个居家厨房,以及厨房门口连着的客厅。

厨房: 墙面贴着白色大理石纹理的瓷砖,灶台是黑色的,上面放着一口黑色的炒锅,台面上摆着各种调料瓶、刀架和杂物。厨房门是白色的,墙顶挂着几个红色的小灯笼。
客厅: 浅木色的地板,门背后挂着一面全身镜,地上有一只黑猫。

光线:
室内自然日光,光线柔和均匀,色调是偏冷的白灰色,干净通透。

分镜
镜头1|0.00–3.27秒|广角近景,拿着食物夹对镜头互动

机位: 手机离人物很近,略微俯拍,用广角镜头,画面是人物的脸和上半身,背景是厨房的瓷砖墙、白色的门和灶台上的黑色炒锅。
0.00–0.60秒: 人物低着头,眼睛往下看,带着一点浅笑;画面左侧的那只手拿着黑色食物夹,放在画面左下角。
0.60–1.00秒: 人物抬起头看向镜头,镜头稍微往前凑近一点。
1.00–1.60秒: 人物看着镜头,嘴角轻轻扬起,食物夹移到画面左侧边缘。
1.60–2.00秒: 人物把食物夹朝镜头伸过来,夹头出现在画面左侧前景里,有虚焦。
2.00–2.60秒: 人物用食物夹在镜头前一开一合地"夹"了几下,眼睛微微眯起,露出俏皮的笑。
2.60–3.27秒: 食物夹收回到画面左侧,人物看着镜头微笑。在3.27秒硬切。

镜头2|3.27–4.70秒|全身镜前,背对镜头再回头

机位: 镜头在人物身后偏右的位置,平视,画面是中景。画面左半部分是全身镜里人物的正面倒影,右半部分是人物本人的背面。客厅的木地板上能看到一只黑猫。
3.27–4.00秒: 人物背对镜头,面朝全身镜站着,一只手叉腰,另一只手轻轻扶着镜子的边缘;镜子里的倒影看着她自己。
4.00–4.20秒: 人物的头从肩膀上方转过来,回头看向镜头。
4.20–4.70秒: 人物回头直视镜头,表情平静;镜子里的倒影转成侧脸。在4.70秒硬切。

镜头3|4.70–5.50秒|高角度俯拍,在灶台边站着

机位: 镜头放在厨房的高处角落,从上往下俯拍人物的全身,用广角镜头,画面里能看到黑色灶台、炒锅、调料瓶和白色的门。
4.70–5.50秒: 人物站在灶台旁边,双手背在身后,抬头看着镜头微笑,身体轻轻晃一下。在5.50秒硬切。

镜头4|5.50–10.00秒|拿着锅铲,近景表情变化

机位: 手机离人物比较近,略微俯拍,用广角镜头,画面是人物的胸口以上。背景里有白色的门、门把手、大理石瓷砖墙、黑色炒锅,墙顶挂着红色小灯笼。
5.50–5.90秒: 人物画面左侧的那只手拿着黑色锅铲,举到肩膀的高度,锅铲头朝上。她看着镜头,开口用英文说出台词「Look, isn't this spatula so handy?」,带着笑。
5.90–6.30秒: 人物的眼睛看向画面一侧,嘴唇嘟起来。
6.30–6.90秒: 人物低头,眼睛往下看,嘴唇抿着。
6.90–7.30秒: 人物抬眼看向镜头,眉头微微皱起,嘴巴轻轻嘟着。
7.30–8.40秒(补充): 人物保持皱眉嘟嘴看着镜头,拿着锅铲的手在空中朝镜头轻轻点两下。
8.40–9.30秒(补充): 人物的眉头慢慢松开,嘴角忍不住往上扬。
9.30–10.00秒(补充): 人物看着镜头露出笑容,锅铲还举在肩膀旁边,定格收尾。从低头到抬头、举锅铲的动作要连贯流畅地过渡,不得跳帧或姿势瞬移。

风格:
风格是抖音/小红书的居家vlog短视频,手机广角原相机的质感,加了美颜和磨皮,肤色白皙通透。自然日光,冷白色调,写实,高清,表情生动自然。

音频:
全程是好听的轻快配乐(尤克里里、手风琴风格的明亮纯音乐),3.27秒、4.70秒、5.50秒的三次切镜都卡在节拍上。镜头4里人物开口用英文说出台词「Look, isn't this spatula so handy?」,人声是自然的美式英语,清晰自然,配乐压低、不盖过人声。除这句台词外,全程不得出现任何其他人声、怪叫、笑声或其他奇怪的声音。

参数:
16:9横屏,10.00秒,30fps,写实,4个镜头。

负面提示词: 换脸、服装变化、切镜后人物变样、镜子倒影和本人不一致、倒影变成别人、五官变形、手指畸形、食物夹或锅铲变形、多余手臂、广角导致的严重畸变、画面闪烁、低清、水印、字幕、跳帧、动作瞬移、姿势突变、奇怪的人声、怪叫、无故笑声Look, isn't this spatula so handy?参照画像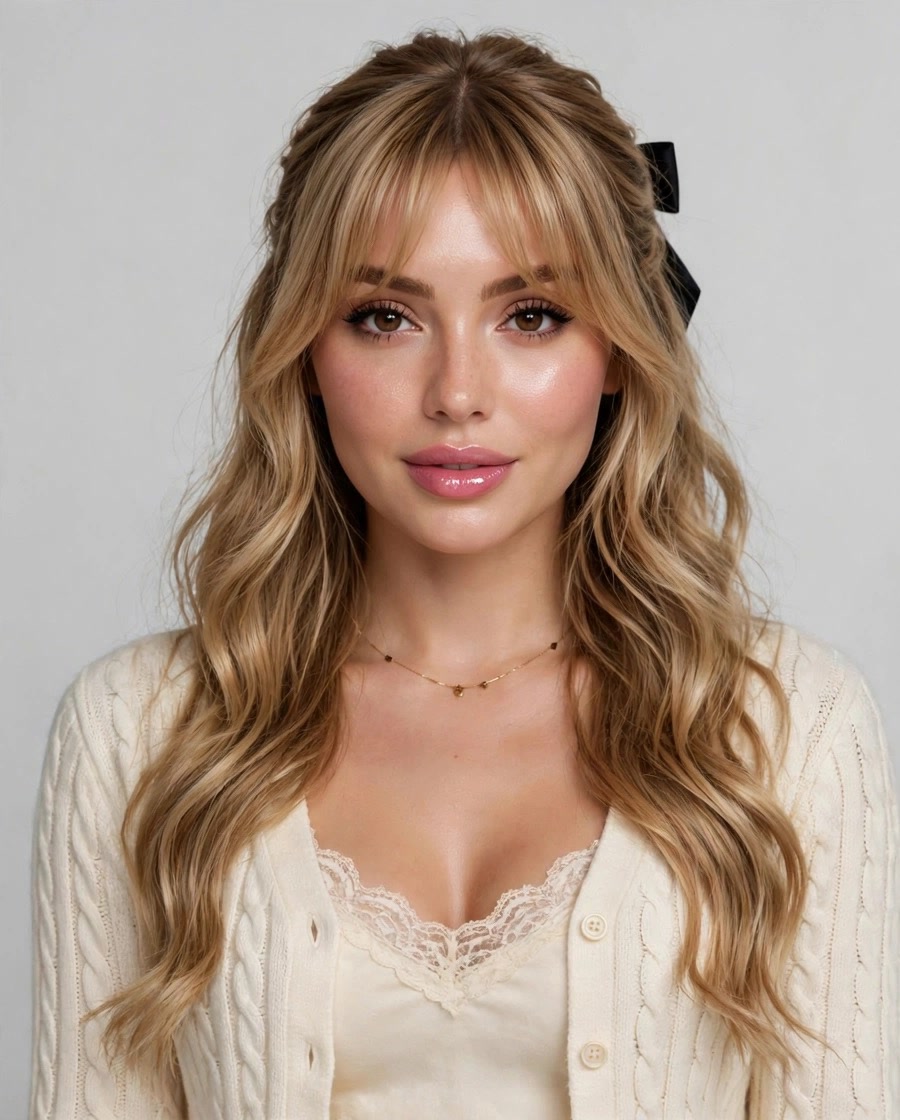
 プロンプトの元投稿 @beizhi606
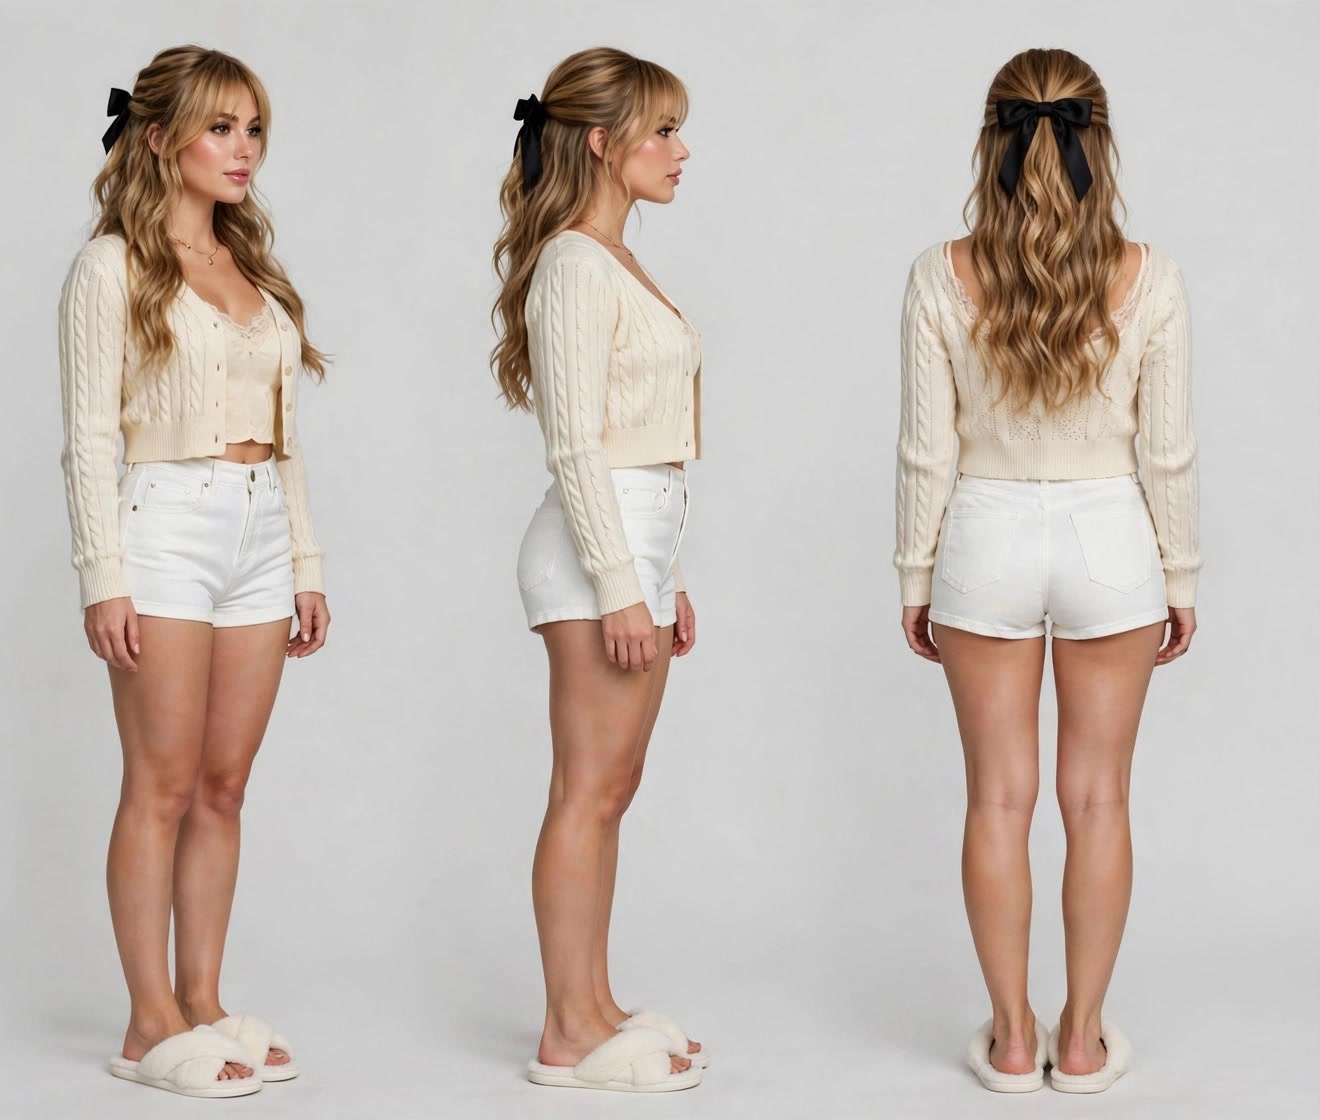
参考图说明:参考图1是人物大头照(脸、五官、发型、发色、妆容都以它为准),参考图2是同一个人的三视图(服装、配饰、鞋子、身材都以它为准)。人物是 25 岁的欧美女性,Instagram 博主风格的精致妆容。下文里「原视频里」的发型、发色和穿搭描述一律忽略,以参考图为准。

中文提示词(10.00秒)
人物:
脸部: 人物的长相、五官、发型、发色和妆容严格按照。
服装和身材: 人物的服装穿搭、配饰和身材比例严格按照。镜头2里人物背对镜头,背面的服装请参考三视图的背面。
一致性: 4个镜头里都是同一个人,脸和服装全程保持一致,切镜后不能变样;镜头2镜子里的倒影也必须是同一个人、同一套服装。

道具:
镜头1:一把黑色的厨房食物夹。
镜头4:一把黑色的锅铲。

场景:
场景是一个居家厨房,以及厨房门口连着的客厅。

厨房: 墙面贴着白色大理石纹理的瓷砖,灶台是黑色的,上面放着一口黑色的炒锅,台面上摆着各种调料瓶、刀架和杂物。厨房门是白色的,墙顶挂着几个红色的小灯笼。
客厅: 浅木色的地板,门背后挂着一面全身镜,地上有一只黑猫。

光线:
室内自然日光,光线柔和均匀,色调是偏冷的白灰色,干净通透。

分镜
镜头1|0.00–3.27秒|广角近景,拿着食物夹对镜头互动

机位: 手机离人物很近,略微俯拍,用广角镜头,画面是人物的脸和上半身,背景是厨房的瓷砖墙、白色的门和灶台上的黑色炒锅。
0.00–0.60秒: 人物低着头,眼睛往下看,带着一点浅笑;画面左侧的那只手拿着黑色食物夹,放在画面左下角。
0.60–1.00秒: 人物抬起头看向镜头,镜头稍微往前凑近一点。
1.00–1.60秒: 人物看着镜头,嘴角轻轻扬起,食物夹移到画面左侧边缘。
1.60–2.00秒: 人物把食物夹朝镜头伸过来,夹头出现在画面左侧前景里,有虚焦。
2.00–2.60秒: 人物用食物夹在镜头前一开一合地"夹"了几下,眼睛微微眯起,露出俏皮的笑。
2.60–3.27秒: 食物夹收回到画面左侧,人物看着镜头微笑。在3.27秒硬切。

镜头2|3.27–4.70秒|全身镜前,背对镜头再回头

机位: 镜头在人物身后偏右的位置,平视,画面是中景。画面左半部分是全身镜里人物的正面倒影,右半部分是人物本人的背面。客厅的木地板上能看到一只黑猫。
3.27–4.00秒: 人物背对镜头,面朝全身镜站着,一只手叉腰,另一只手轻轻扶着镜子的边缘;镜子里的倒影看着她自己。
4.00–4.20秒: 人物的头从肩膀上方转过来,回头看向镜头。
4.20–4.70秒: 人物回头直视镜头,表情平静;镜子里的倒影转成侧脸。在4.70秒硬切。

镜头3|4.70–5.50秒|高角度俯拍,在灶台边站着

机位: 镜头放在厨房的高处角落,从上往下俯拍人物的全身,用广角镜头,画面里能看到黑色灶台、炒锅、调料瓶和白色的门。
4.70–5.50秒: 人物站在灶台旁边,双手背在身后,抬头看着镜头微笑,身体轻轻晃一下。在5.50秒硬切。

镜头4|5.50–10.00秒|拿着锅铲,近景表情变化

机位: 手机离人物比较近,略微俯拍,用广角镜头,画面是人物的胸口以上。背景里有白色的门、门把手、大理石瓷砖墙、黑色炒锅,墙顶挂着红色小灯笼。
5.50–5.90秒: 人物画面左侧的那只手拿着黑色锅铲,举到肩膀的高度,锅铲头朝上。她看着镜头,开口用英文说出台词「Look, isn't this spatula so handy?」,带着笑。
5.90–6.30秒: 人物的眼睛看向画面一侧,嘴唇嘟起来。
6.30–6.90秒: 人物低头,眼睛往下看,嘴唇抿着。
6.90–7.30秒: 人物抬眼看向镜头,眉头微微皱起,嘴巴轻轻嘟着。
7.30–8.40秒(补充): 人物保持皱眉嘟嘴看着镜头,拿着锅铲的手在空中朝镜头轻轻点两下。
8.40–9.30秒(补充): 人物的眉头慢慢松开,嘴角忍不住往上扬。
9.30–10.00秒(补充): 人物看着镜头露出笑容,锅铲还举在肩膀旁边,定格收尾。从低头到抬头、举锅铲的动作要连贯流畅地过渡,不得跳帧或姿势瞬移。

风格:
风格是抖音/小红书的居家vlog短视频,手机广角原相机的质感,加了美颜和磨皮,肤色白皙通透。自然日光,冷白色调,写实,高清,表情生动自然。

音频:
全程是好听的轻快配乐(尤克里里、手风琴风格的明亮纯音乐),3.27秒、4.70秒、5.50秒的三次切镜都卡在节拍上。镜头4里人物开口用英文说出台词「Look, isn't this spatula so handy?」,人声是自然的美式英语,清晰自然,配乐压低、不盖过人声。除这句台词外,全程不得出现任何其他人声、怪叫、笑声或其他奇怪的声音。

参数:
16:9横屏,10.00秒,30fps,写实,4个镜头。

负面提示词: 换脸、服装变化、切镜后人物变样、镜子倒影和本人不一致、倒影变成别人、五官变形、手指畸形、食物夹或锅铲变形、多余手臂、广角导致的严重畸变、画面闪烁、低清、水印、字幕、跳帧、动作瞬移、姿势突变、奇怪的人声、怪叫、无故笑声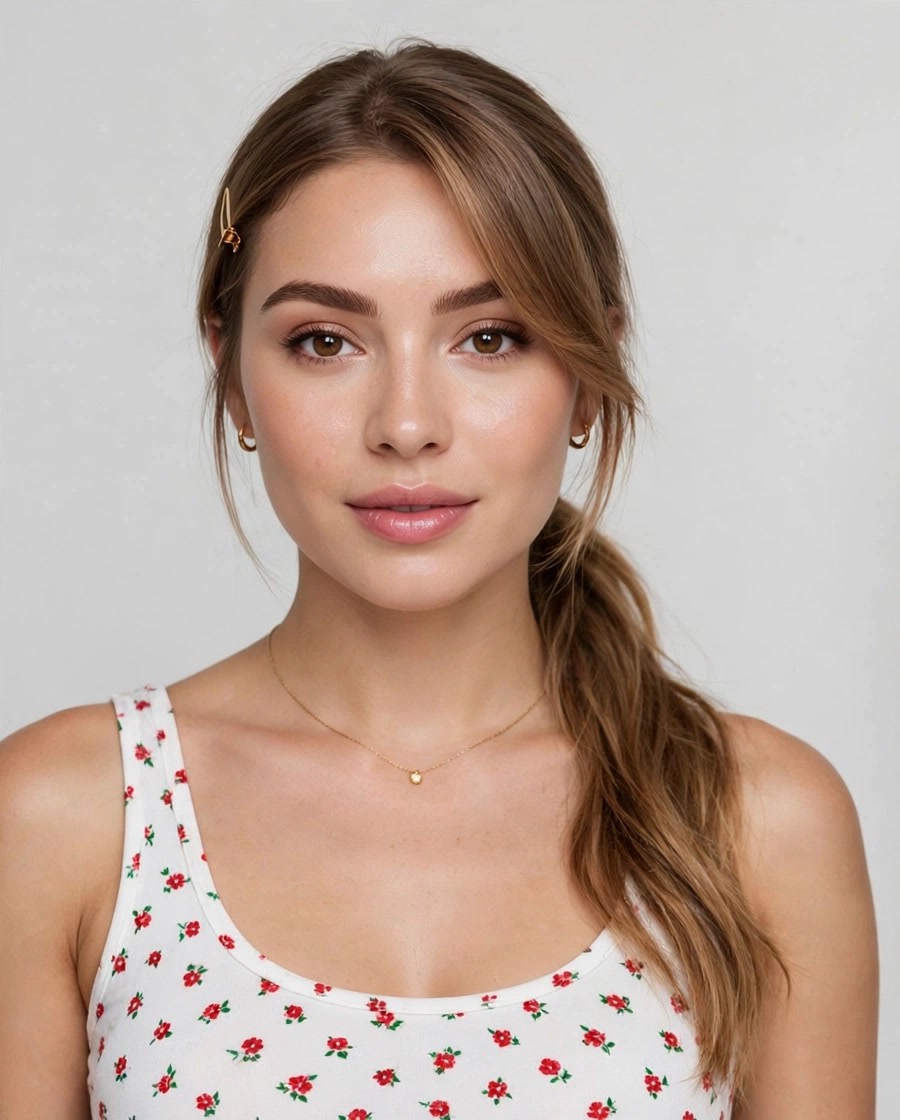
 プロンプトの元投稿 @beizhi606
参考图说明:参考图1是人物大头照(脸、五官、发型、发色、妆容都以它为准),参考图2是同一个人的三视图(服装、配饰、鞋子、身材都以它为准)。人物是 25 岁的欧美女性,Instagram 博主风格的精致妆容。下文里「原视频里」的发型、发色和穿搭描述一律忽略,以参考图为准。

中文提示词(10.00秒)
·脸部:完全按【参考图1 大头照】,五官、脸型、发型、发色都以大头照为准,全程保持同一张脸。原视频里是黑色长发,低马尾搭在右肩前面,有侧分刘海,左侧别一个小发夹。
·服装和身材:完全按【参考图2 三视图】,包括服装款式、颜色、配饰和身材比例。以下是原视频的穿搭,只在没有参考时备用:
·白色背心,上面有红色小碎花印花:
·浅蓝色牛仔短裤:
·右手腕戴红色串珠手链,脖子上有金色细项链。
·一致性:全程人物的脸和服装都不能变。
场景

• 老式居民楼的楼道和阳台,人物站在楼上一层的水泥栏杆后面,栏杆是一根根竖着的方形水泥柱,表面斑驳。
• 背景是灰色水泥墙,墙上有几根电线横着穿过。
• 机位在楼下一层,画面最下方前景是一根黄色金属扶手。
• 中段镜头拉开一点时,能稍微看到上方一层水泥栏杆阳台的下沿和电线即可,不要拉成远景。

光线:阴天的自然光,光线柔和均匀,偏灰调,低饱和,写实。

机位(本版重点):手持拍摄,从楼下往上仰拍,竖屏。前半段是近距离中近景,人物上半身占画面主体;约 4.6 秒开始只轻轻往后拉一次,拉到中景(人物腰部以上、头部约占画面高度三分之一)就立刻停住,之后一直保持这个距离固定拍到结尾,不再继续拉远、不往下拉成远景,人物不能变小。全程只有轻微手持晃动。

分镜
• 0.00–0.40:镜头从下往上快速甩,画面先是模糊的黄色扶手和水泥栏杆,有动态模糊,随即稳定成近距离中近景。
• 0.40–0.60:人物站在栏杆后面,上半身往前探出栏杆,左手扶着栏杆顶部,右手从栏杆之间向下伸出,掌心朝下,手指张开,伸向镜头。
• 0.60–1.60:保持向下伸手的姿势,头往右歪,微笑着看向镜头,马尾垂在右肩前。
• 1.60–2.80:头慢慢回正,继续微笑看镜头,右手还向下伸着,手指轻轻动了一下。
• 2.80–3.60:头又往左歪,眼睛半眯,嘴角上扬,身体随着节奏轻轻晃动。
• 3.60–4.60:头回到正面,看着镜头,右手保持向下伸出,镜头不动。
• 4.60–6.50:镜头只轻轻往后拉一次,拉到中景就停:人物稍微变小一点,上方一层阳台下沿和电线稍微进画,黄色扶手仍在画面下方;人物保持伸手姿势看着镜头。
• 6.50–7.50:镜头停住不动,保持这个中景距离,人物保持向下伸手、微笑看镜头。
• 7.50–8.80:镜头仍固定在这个距离。人物慢慢把右手收回到栏杆上,双手扶着栏杆,头微微歪着。
• 8.80–10.00:人物保持双手扶栏杆、身体往前探的姿势,头抬着、微笑看着镜头直到结束,不要把头伏到手臂或栏杆上;镜头保持距离不再拉动。

风格:写实真人质感,手机竖屏随手拍的感觉,阴天的灰调,低饱和,有轻微手持晃动。

字幕:不要在生成时让模型写任何字幕文字(字幕后期再加)。

音频:保留背景音乐,镜头拉开的时候对准音乐节拍。

参数:10.00 秒,9:16 竖屏,720×1280,30fps。

负面提示词:一直拉远、持续变焦拉远、远景、人物变得很小、换脸、五官变形、脸显老、发型改变、服装颜色或款式变化、手链消失或戴错手、多出手指、手部畸形、伸出的手臂过长、肢体扭曲、栏杆穿过身体、建筑结构错乱、画面闪烁、乱码文字、水印。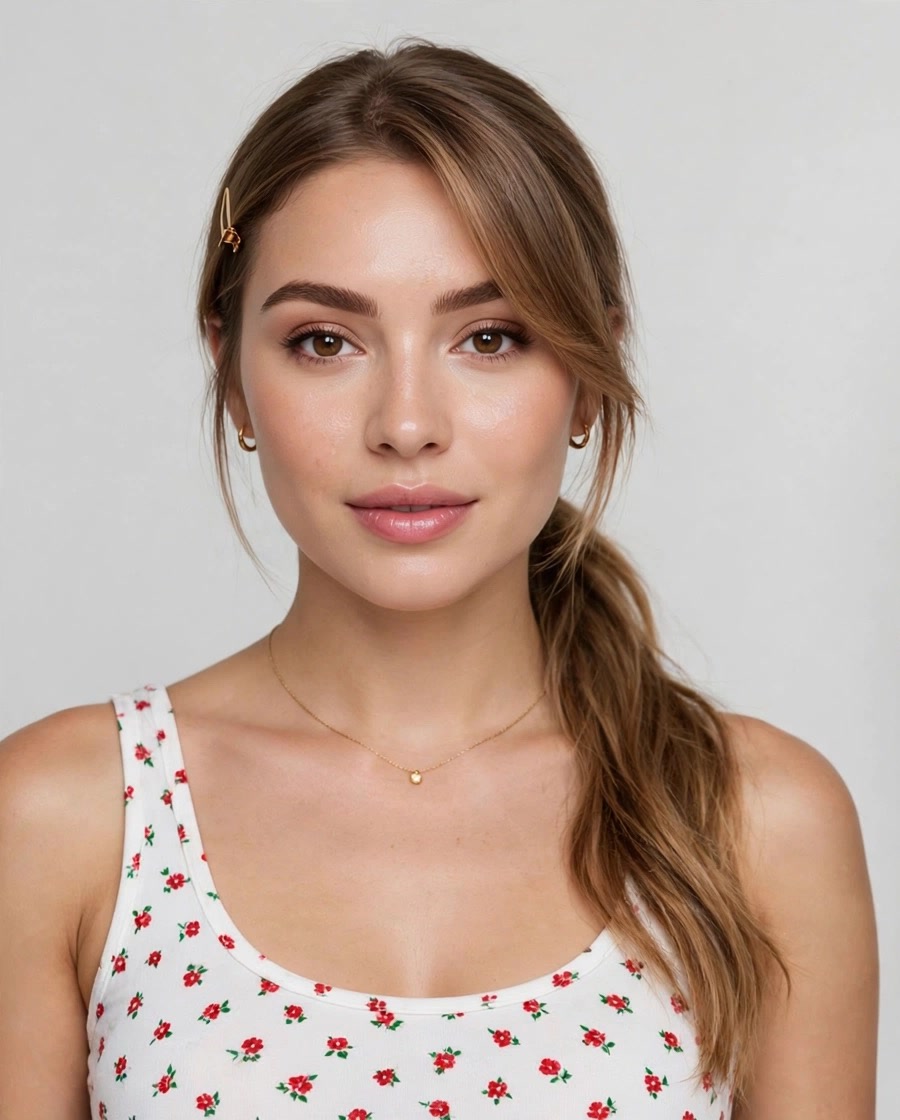
 プロンプトの元投稿 @beizhi606
参考图说明:参考图1是人物大头照(脸、五官、发型、发色、妆容都以它为准),参考图2是同一个人的三视图(服装、配饰、鞋子、身材都以它为准)。人物是 25 岁的欧美女性,Instagram 博主风格的精致妆容。下文里「原视频里」的发型、发色和穿搭描述一律忽略,以参考图为准。

中文提示词(10.00秒)
·脸部:完全按【参考图1 大头照】,五官、脸型、发型、发色都以大头照为准,全程保持同一张脸。原视频里是黑色长发,低马尾搭在右肩前面,有侧分刘海,左侧别一个小发夹。
·服装和身材:完全按【参考图2 三视图】,包括服装款式、颜色、配饰和身材比例。以下是原视频的穿搭,只在没有参考时备用:
·白色背心,上面有红色小碎花印花:
·浅蓝色牛仔短裤:
·右手腕戴红色串珠手链,脖子上有金色细项链。
·一致性:全程人物的脸和服装都不能变。
场景

• 老式居民楼的楼道和阳台,人物站在楼上一层的水泥栏杆后面,栏杆是一根根竖着的方形水泥柱,表面斑驳。
• 背景是灰色水泥墙,墙上有几根电线横着穿过。
• 机位在楼下一层,画面最下方前景是一根黄色金属扶手。
• 中段镜头拉开一点时,能稍微看到上方一层水泥栏杆阳台的下沿和电线即可,不要拉成远景。

光线:阴天的自然光,光线柔和均匀,偏灰调,低饱和,写实。

机位(本版重点):手持拍摄,从楼下往上仰拍,竖屏。前半段是近距离中近景,人物上半身占画面主体;约 4.6 秒开始只轻轻往后拉一次,拉到中景(人物腰部以上、头部约占画面高度三分之一)就立刻停住,之后一直保持这个距离固定拍到结尾,不再继续拉远、不往下拉成远景,人物不能变小。全程只有轻微手持晃动。

分镜
• 0.00–0.40:镜头从下往上快速甩,画面先是模糊的黄色扶手和水泥栏杆,有动态模糊,随即稳定成近距离中近景。
• 0.40–0.60:人物站在栏杆后面,上半身往前探出栏杆,左手扶着栏杆顶部,右手从栏杆之间向下伸出,掌心朝下,手指张开,伸向镜头。
• 0.60–1.60:保持向下伸手的姿势,头往右歪,微笑着看向镜头,马尾垂在右肩前。
• 1.60–2.80:头慢慢回正,继续微笑看镜头,右手还向下伸着,手指轻轻动了一下。
• 2.80–3.60:头又往左歪,眼睛半眯,嘴角上扬,身体随着节奏轻轻晃动。
• 3.60–4.60:头回到正面,看着镜头,右手保持向下伸出,镜头不动。
• 4.60–6.50:镜头只轻轻往后拉一次,拉到中景就停:人物稍微变小一点,上方一层阳台下沿和电线稍微进画,黄色扶手仍在画面下方;人物保持伸手姿势看着镜头。
• 6.50–7.50:镜头停住不动,保持这个中景距离,人物保持向下伸手、微笑看镜头。
• 7.50–8.80:镜头仍固定在这个距离。人物慢慢把右手收回到栏杆上,双手扶着栏杆,头微微歪着。
• 8.80–10.00:人物保持双手扶栏杆、身体往前探的姿势,头抬着、微笑看着镜头直到结束,不要把头伏到手臂或栏杆上;镜头保持距离不再拉动。

风格:写实真人质感,手机竖屏随手拍的感觉,阴天的灰调,低饱和,有轻微手持晃动。

字幕:不要在生成时让模型写任何字幕文字(字幕后期再加)。

音频:保留背景音乐,镜头拉开的时候对准音乐节拍。

参数:10.00 秒,9:16 竖屏,720×1280,30fps。

负面提示词:一直拉远、持续变焦拉远、远景、人物变得很小、换脸、五官变形、脸显老、发型改变、服装颜色或款式变化、手链消失或戴错手、多出手指、手部畸形、伸出的手臂过长、肢体扭曲、栏杆穿过身体、建筑结构错乱、画面闪烁、乱码文字、水印。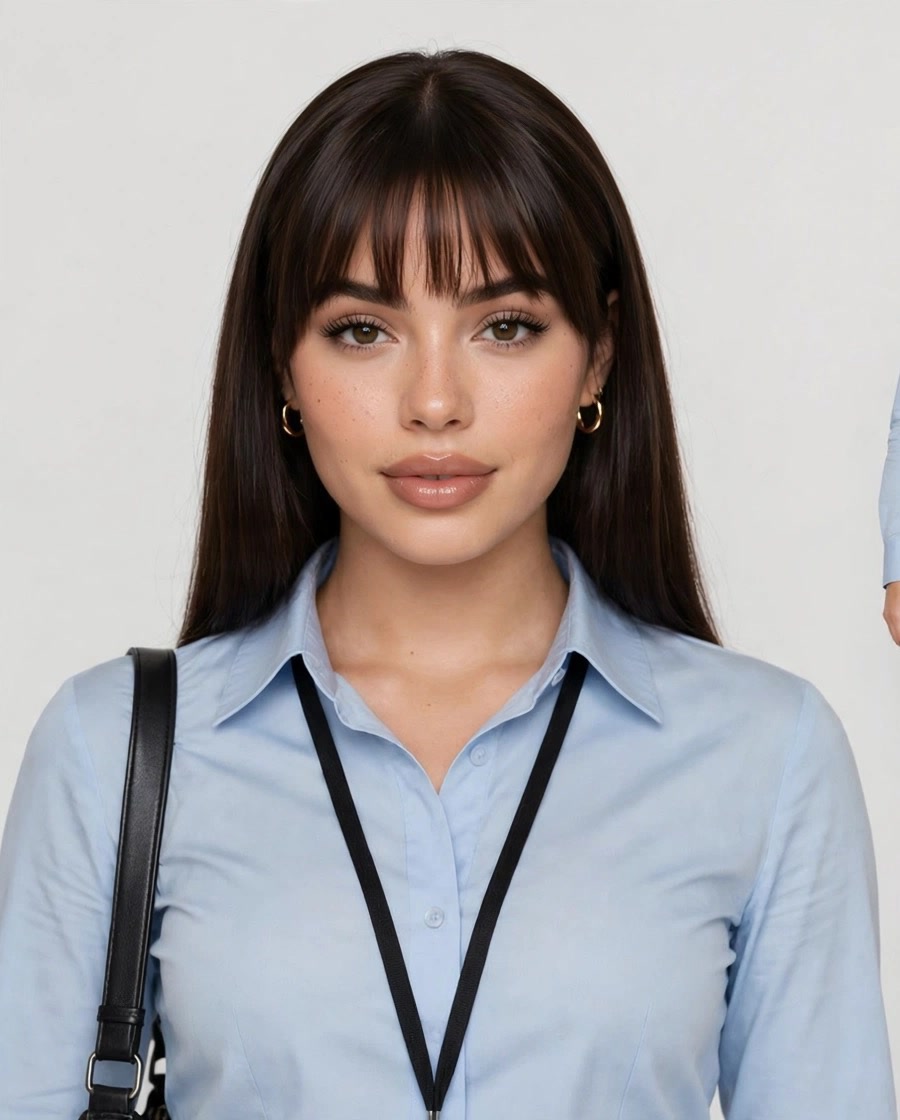
 プロンプトの元投稿 @beizhi606
参考图说明:参考图1是人物大头照(脸、五官、发型、发色、妆容都以它为准),参考图2是同一个人的三视图(服装、配饰、鞋子、身材都以它为准)。人物是 25 岁的欧美女性,Instagram 博主风格的精致妆容。下文里「原视频里」的发型、发色和穿搭描述一律忽略,以参考图为准。

中文提示词(10.00秒)
人物

• 脸部:完全按【参考图1 大头照】,五官、脸型、发型、发色都以大头照为准,每个镜头保持同一张脸。原视频里是黑棕色齐腰长直发、齐刘海。
• 服装和身材:完全按【参考图2 三视图】,包括服装款式、颜色、配饰、鞋子和身材比例。原视频里的穿搭只作为没有参考时的备用:
• 浅蓝色长袖衬衫,扎进裙子里;
• 灰色包臀短裙;
• 黑色薄丝袜,黑色尖头细高跟鞋;
• 胸前挂黑色挂绳工牌;
• 黑色单肩包。

• 一致性:5 个镜头里人物的脸和服装不能变。

场景

• 地铁车厢里,白色车厢内壁,金属扶手竖杆。
• 车门边有黄黑警示条,门上有出口和安全标识。
• 车厢里有其他乘客:有的低头看手机,有的坐着,有的站着,有的放着红色行李箱和紫色袋子。乘客都是自然状态,不看镜头。

光线:地铁车厢顶部的白色日光灯,照明均匀明亮,偏冷白色调,写实。

机位:都是手机手持拍摄,平视或略低机位,竖屏。

分镜
镜头1|0.00–1.97秒|靠在车门边站着,旁边是看手机的乘客

• 机位:平视中全景,竖屏能拍到全身。画面左侧前景是一位穿蓝色T恤、低头看手机的男乘客,人物在画面中间偏右,背靠车门。
• 0.00–0.40:人物背靠车门,一条腿弯曲,脚掌向后抵在车门上。右手抬到颈侧摸着头发,看向镜头。
• 0.40–0.80:抬起的脚放回地面,变成双脚并拢站立,右手放下到胸前。
• 0.80–1.40:双手自然垂放,身体靠着车门,头微微低下。
• 1.40–1.97:右手抬到耳边,把头发往耳后拨,眼睛向下看。

镜头2|1.97–3.37秒|坐在座位上跷腿,侧脸看向左边

• 机位:略高的侧前方机位,中全景。人物在画面右侧,坐在地铁座椅上,左侧有一位戴眼镜、穿深色衣服的男乘客,低头看手机,旁边还站着一位乘客。
• 1.97–2.60:硬切进来。人物跷着二郎腿,黑色单肩包放在大腿上,双手放在包上,头转向画面左侧,侧脸朝镜头。
• 2.60–3.37:姿势不变,眼睛看着左前方,头发自然垂在背后,身体基本保持不动。

镜头3|3.37–5.33秒|手扶竖杆站着,拨头发

• 机位:正面平视中景,拍到大腿以上。人物站在车厢过道中间,左边是金属竖杆,背景是纵深的车厢和其他乘客。镜头缓慢往前推。
• 3.37–3.90:硬切进来。人物右手握着竖杆,左肩背着黑色包,看着镜头。
• 3.90–4.40:左手抬起来,把脸侧的头发往耳后拨。
• 4.40–5.33:左手停在耳边扶着头发,头微微向右歪,看着镜头,右手一直握着竖杆。

镜头4|5.33–7.27秒|背靠车厢隔板站着,手里拿奶茶

• 机位:平视全景,画面从车厢纵深方向拍过去。人物在画面右侧,背靠车门旁的白色隔板,左边是长长的车厢,里面有很多乘客和行李箱。
• 5.33–6.00:硬切进来。人物背靠隔板站着,双腿并拢,左手在胸前拿着一杯带吸管的奶茶,右手垂在身侧,黑色包放在脚边或挂在手臂上,看着镜头。
• 6.00–7.27:姿势基本不变,头微微转向车厢一侧,再转回来看着镜头,镜头有轻微的手持晃动。

镜头5|7.27–8.73秒|靠墙曲腿,拨头发后转头

• 机位:平视中全景,比镜头4离人物更近。人物还是靠着同一块白色隔板,左边背景是坐着的乘客和行李。
• 7.27–7.60:硬切进来。人物背靠隔板,一条腿弯曲,脚掌向后抵在隔板上。右手抬到头侧拨头发,左手拿着奶茶,头歪着看向镜头。
• 7.60–8.10:右手放下,叉在腰侧,还保持曲腿姿势。
• 8.10–8.73:抬起的脚放回地面,双腿并拢站直。头转向画面左侧,看向车厢里面,侧脸朝镜头。

(补充)镜头5延续|8.73–10.00

• 8.73–9.40:机位不变。人物保持站立,慢慢把头转回来看着镜头。
• 9.40–10.00:左手拿着奶茶放在胸前,右手自然垂下,身体轻轻靠着隔板,画面停在这个构图上直到结束。

风格:写实真人质感,手机竖屏随手拍的感觉,高清,自然生活场景,带轻微手持晃动。

音频:保留背景音乐,切镜点 1.97、3.37、5.33、7.27 秒对准音乐节拍。

参数:10.00 秒,9:16 竖屏,1080×1920,30fps。

负面提示词:换脸、五官变形、发型改变、服装颜色或款式变化、工牌消失、多出手指、肢体扭曲、腿部比例异常、路人看镜头、路人脸部畸形、画面闪烁、文字水印、背景变形、车厢结构错乱。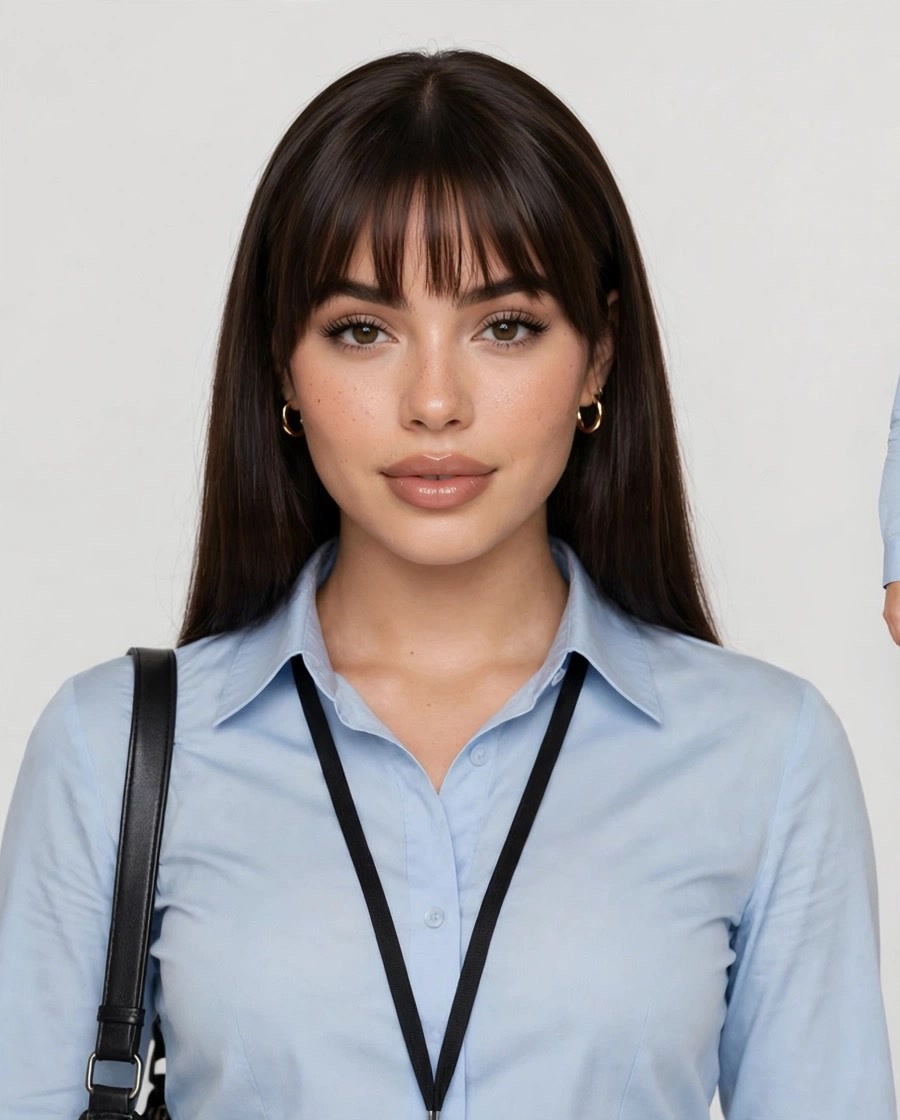
 プロンプトの元投稿 @beizhi606
参考图说明:参考图1是人物大头照(脸、五官、发型、发色、妆容都以它为准),参考图2是同一个人的三视图(服装、配饰、鞋子、身材都以它为准)。人物是 25 岁的欧美女性,Instagram 博主风格的精致妆容。下文里「原视频里」的发型、发色和穿搭描述一律忽略,以参考图为准。

中文提示词(10.00秒)
人物

• 脸部:完全按【参考图1 大头照】,五官、脸型、发型、发色都以大头照为准,每个镜头保持同一张脸。原视频里是黑棕色齐腰长直发、齐刘海。
• 服装和身材:完全按【参考图2 三视图】,包括服装款式、颜色、配饰、鞋子和身材比例。原视频里的穿搭只作为没有参考时的备用:
• 浅蓝色长袖衬衫,扎进裙子里;
• 灰色包臀短裙;
• 黑色薄丝袜,黑色尖头细高跟鞋;
• 胸前挂黑色挂绳工牌;
• 黑色单肩包。

• 一致性:5 个镜头里人物的脸和服装不能变。

场景

• 地铁车厢里,白色车厢内壁,金属扶手竖杆。
• 车门边有黄黑警示条,门上有出口和安全标识。
• 车厢里有其他乘客:有的低头看手机,有的坐着,有的站着,有的放着红色行李箱和紫色袋子。乘客都是自然状态,不看镜头。

光线:地铁车厢顶部的白色日光灯,照明均匀明亮,偏冷白色调,写实。

机位:都是手机手持拍摄,平视或略低机位,竖屏。

分镜
镜头1|0.00–1.97秒|靠在车门边站着,旁边是看手机的乘客

• 机位:平视中全景,竖屏能拍到全身。画面左侧前景是一位穿蓝色T恤、低头看手机的男乘客,人物在画面中间偏右,背靠车门。
• 0.00–0.40:人物背靠车门,一条腿弯曲,脚掌向后抵在车门上。右手抬到颈侧摸着头发,看向镜头。
• 0.40–0.80:抬起的脚放回地面,变成双脚并拢站立,右手放下到胸前。
• 0.80–1.40:双手自然垂放,身体靠着车门,头微微低下。
• 1.40–1.97:右手抬到耳边,把头发往耳后拨,眼睛向下看。

镜头2|1.97–3.37秒|坐在座位上跷腿,侧脸看向左边

• 机位:略高的侧前方机位,中全景。人物在画面右侧,坐在地铁座椅上,左侧有一位戴眼镜、穿深色衣服的男乘客,低头看手机,旁边还站着一位乘客。
• 1.97–2.60:硬切进来。人物跷着二郎腿,黑色单肩包放在大腿上,双手放在包上,头转向画面左侧,侧脸朝镜头。
• 2.60–3.37:姿势不变,眼睛看着左前方,头发自然垂在背后,身体基本保持不动。

镜头3|3.37–5.33秒|手扶竖杆站着,拨头发

• 机位:正面平视中景,拍到大腿以上。人物站在车厢过道中间,左边是金属竖杆,背景是纵深的车厢和其他乘客。镜头缓慢往前推。
• 3.37–3.90:硬切进来。人物右手握着竖杆,左肩背着黑色包,看着镜头。
• 3.90–4.40:左手抬起来,把脸侧的头发往耳后拨。
• 4.40–5.33:左手停在耳边扶着头发,头微微向右歪,看着镜头,右手一直握着竖杆。

镜头4|5.33–7.27秒|背靠车厢隔板站着,手里拿奶茶

• 机位:平视全景,画面从车厢纵深方向拍过去。人物在画面右侧,背靠车门旁的白色隔板,左边是长长的车厢,里面有很多乘客和行李箱。
• 5.33–6.00:硬切进来。人物背靠隔板站着,双腿并拢,左手在胸前拿着一杯带吸管的奶茶,右手垂在身侧,黑色包放在脚边或挂在手臂上,看着镜头。
• 6.00–7.27:姿势基本不变,头微微转向车厢一侧,再转回来看着镜头,镜头有轻微的手持晃动。

镜头5|7.27–8.73秒|靠墙曲腿,拨头发后转头

• 机位:平视中全景,比镜头4离人物更近。人物还是靠着同一块白色隔板,左边背景是坐着的乘客和行李。
• 7.27–7.60:硬切进来。人物背靠隔板,一条腿弯曲,脚掌向后抵在隔板上。右手抬到头侧拨头发,左手拿着奶茶,头歪着看向镜头。
• 7.60–8.10:右手放下,叉在腰侧,还保持曲腿姿势。
• 8.10–8.73:抬起的脚放回地面,双腿并拢站直。头转向画面左侧,看向车厢里面,侧脸朝镜头。

(补充)镜头5延续|8.73–10.00

• 8.73–9.40:机位不变。人物保持站立,慢慢把头转回来看着镜头。
• 9.40–10.00:左手拿着奶茶放在胸前,右手自然垂下,身体轻轻靠着隔板,画面停在这个构图上直到结束。

风格:写实真人质感,手机竖屏随手拍的感觉,高清,自然生活场景,带轻微手持晃动。

音频:保留背景音乐,切镜点 1.97、3.37、5.33、7.27 秒对准音乐节拍。

参数:10.00 秒,9:16 竖屏,1080×1920,30fps。

负面提示词:换脸、五官变形、发型改变、服装颜色或款式变化、工牌消失、多出手指、肢体扭曲、腿部比例异常、路人看镜头、路人脸部畸形、画面闪烁、文字水印、背景变形、车厢结构错乱。
Muse Video が受け付けるものと受け付けないもの。対応していない解像度・比率・長さ・入力は、タスク作成前に 400 で拒否されるため、課金されません。
| 対応 | 非対応 | |
|---|---|---|
| 解像度 | 720p のみ(resolution: 720p、または省略) | 1080p、2K、4K、480p |
| アスペクト比 | 横長 16:9 の 1280×720(既定)、縦長 9:16 の 720×1280 | 正方形 1:1、4:3、3:4、21:9 などその他すべての比率 |
| 長さ | 4〜30 の整数秒。5・6・8・10・15・20・25・30 秒はその長さちょうどで出力され、それ以外は次の段階に切り上げ | 4 秒未満、30 秒超、8.5 のような小数 |
| 画像 | 先頭フレーム 1 枚か、同じ人物や被写体を保つための参照画像最大 4 枚のどちらか一方(併用不可)。PNG・JPEG・WebP、1 枚 20 MB まで、公開 URL か base64 | 先頭フレームと参照画像の併用、5 枚以上の参照画像、末尾フレーム |
| 動画・音声の入力 | なし(メディア入力は画像のみ) | 参照動画、動画の編集や延長、動きを駆動する音声、手持ちの音声に合わせたリップシンク |
| 音声 | 映像と一緒にモデルが生成 | 音声をオフにする設定はなし(generate_audio: false は拒否)。すべての動画に音声が付くとは限らない |
| その他の設定 | プロンプトは任意の言語で 4,000 文字まで。カメラの動きはプロンプトに書く | negative_prompt、seed(結果は再現できない)、カメラ制御パラメーター |
ほかの動画モデルと同じく、Muse Video の成功率は 100% ではありません。失敗したタスクは課金されません。
受け付けたあとでもタスクが失敗することはあります。モデルが内容を拒否することもあれば、生成中に一時的なエラーが起きることもあり、仕上がった動画の向きや長さがリクエストと合わない場合はその動画を破棄します。失敗したタスクは state が failed になり、理由は failMsg に入り、料金は返却されます。
ローンチ時のテストリクエスト 2 件はどちらも動画が返りましたが、2 件では成功率を約束するにはまったく足りないため、成功率はまだ公表していません。ときどき失敗する前提でパイプラインを組んでください。一時的なエラーは再試行し、拒否されたプロンプトは書き直し、初回で必ず動画が届くとは考えないでください。
モデルがプロンプトや入力画像を拒否することがあります。同じリクエストをそのまま再送してもほとんど効果はないので、プロンプトを書き直すか画像を変えてください。
リクエストの内容とは関係のない理由で生成が失敗することがあります。少し時間を置いて同じリクエストを再送すれば、たいていは成功します。
仕上がった動画の向きが違う場合や、リクエストより短い場合は、納品せずに破棄します。リクエストを再送してください。
Meta は映像と一緒に音声も生成すると説明していますが、テスト動画 2 本のうち 1 本は無音でした。音声が必要な場合は、MP4 ごとに音声トラックがあるか確認してください。
リクエスト秒数あたり $0.037。先頭フレームや参照画像を付けても追加料金はなく、失敗したタスクは課金されません。
| リクエスト | 実際の長さ | 料金 |
|---|---|---|
| 4 秒 | 5 秒 | $0.148 |
| 5 秒(既定) | 5 秒 | $0.185 |
| 6 秒 | 6 秒 | $0.222 |
| 7 秒 | 8 秒 | $0.259 |
| 8 秒 | 8 秒 | $0.296 |
| 10 秒 | 10 秒 | $0.37 |
| 15 秒 | 15 秒 | $0.555 |
| 20 秒 | 20 秒 | $0.74 |
| 25 秒 | 25 秒 | $0.925 |
| 30 秒(最大) | 30 秒 | $1.11 |
10 秒までの動画は通常 1〜2 分、15〜30 秒の動画は通常 3〜7 分で仕上がります。4 秒のテストリクエストは約 1 分半でした。10 秒を超える動画は、10 秒前後と 20 秒前後でカットが切り替わります。
フロントカメラで 1 人を間近から撮り、小さな仕草を重ね、暖色の暗めの照明と音楽を添える。上の作例のようなクリップです。
同じ人物の写真を images に最大 4 枚渡し、新しい場面をプロンプトに書きます。1 回のテストでは、若い女性の写真 4 枚と夕暮れのビーチのプロンプトから、88 秒で 5.0 秒・9:16・音声付きの動画が返りました。顔も髪型も同じで服装も近く、写真にあったピースサインや手で口元を隠して笑う仕草まで再現されました。動画は写真からではなくビーチから始まりました。1 回のテスト結果で、毎回そうなるとは限りません。
ショート動画のフィード向けの 9:16、ページや広告向けの 16:9 を、5〜30 秒・720p で。
商品写真やイラスト、写真を先頭フレームにして、動きをプロンプトで指示します。
Muse Video が出力できるのは 16:9 か 9:16 の 720p だけです。より高い解像度やほかの形が必要なら、APIMODELS のほかの動画モデルを選んでください。
画像は先頭フレームか参照画像として使えるだけです。末尾フレームも参照動画もなく、手持ちの音声に合わせたリップシンクもできません。
失敗するリクエストもあり、音声のない動画が返ることもあります。動画が 1 本欠けるだけでプロダクトが成り立たないなら、頼る前に再試行とチェックを組み込んでください。
Muse Video は Meta の動画生成 API です。Muse Video は Meta Superintelligence Labs の動画モデルです。APIMODELS では統合動画エンドポイント上の 1 つのモデル ID muse-video で、プロンプトだけを送ればテキストから動画、先頭フレームの画像を 1 枚加えればその画像から始まる動画になり、参照画像を最大 4 枚加えれば、その画像からは始めずに同じ人物や被写体を保った動画になります。 リクエストはシンプルです。prompt は必須(4,000 文字以内、言語は問いません)。duration で長さを 4〜30 の整数秒で指定します(OpenAI 形式の seconds でも可)。省略すると 5 秒です。aspect_ratio で横長 16:9(既定、1280×720)か縦長 9:16(720×1280)を選び、size に 1280x720 または 720x1280 を指定しても同じです。出力は常に 720p で、1080p や正方形はなく、指定するとタスクを作成する前に 400 が返ります。画像から動画にするときは、先頭フレームを image_url で渡します(first_frame_url、image、input_reference も可)。できれば動画と同じ向きの画像を使ってください。参照画像は images で最大 4 枚渡します(image_urls、reference_image_urls も可)。画像はどれも公開 URL か base64 の data URI で、PNG・JPEG・WebP のいずれかです。使えるのはどちらか一方だけで、先頭フレームと参照画像の同時指定、5 枚以上の参照画像、末尾フレーム、参照動画や参照音声、negative_prompt、seed、音声のオフは 400 で拒否されます。 動画の長さは段階式です。5・6・8・10・15・20・25・30 秒のリクエストはちょうどその長さで返り、それ以外の整数は次の段階に切り上げられます(4 → 5 秒、7 → 8 秒、11 → 15 秒)。そのため、支払った長さより短い動画が返ることはありません。動画は H.264 の MP4・24 fps で、Meta は Muse Video が映像と同時に音声も生成すると説明しています。参照画像のテストでは、同じ女性の画像 4 枚から 5 秒の海辺の動画ができ、顔と髪型は同じままでした。動画はどの画像からも始まっていません。 生成は非同期タスクで、作成したあとはポーリングするかコールバックで結果を受け取ります。10 秒までの動画は通常 1〜2 分、15〜30 秒は 3〜7 分ほどかかります。すべてのリクエストが成功するわけではありません。モデルが内容を拒否することも、生成が一時的なエラーになることもあり、向きや長さが違う動画は破棄されます。失敗したタスクは課金されません。料金はリクエストした秒数あたり $0.037 で、5 秒 $0.185、10 秒 $0.37、30 秒 $1.11 です。 APIMODELS のプラットフォーム経由なら、統一 API と明朗な従量課金でこのモデルを呼び出せます。 現在の料金: per second: $0.037, 5s (default): $0.185, 8s: $0.296, 10s: $0.37, 15s: $0.555, 20s: $0.74, 30s (maximum): $1.11。
広告キャンペーンや SNS 施策に向けたブランド動画を短時間で作ります。
TikTok、Instagram、YouTube 向けの縦型ショート動画を量産できます。
機能紹介やチュートリアル動画を作り、コンバージョンにつなげます。
講座の解説、知識の説明、研修用の動画を低コストで継続的に作れます。
Muse Video は APIMODELS 経由で per second: $0.037, 5s (default): $0.185, 8s: $0.296, 10s: $0.37, 15s: $0.555, 20s: $0.74, 30s (maximum): $1.11 で利用できます。課金は従量制で、生成した分だけの支払いです。
APIMODELS に登録して API キーを取得し、統一エンドポイントを呼ぶだけです。cURL / Python / Node.js のサンプルを含む詳しいドキュメントを用意しています。
APIMODELS は同じ Muse Video を集約プラットフォーム経由で提供します。統一された API インターフェースなので、プロバイダごとにアカウントを作る必要はありません。キー 1 本ですべてのモデルに届きます。
Muse Video は Meta Superintelligence Labs の動画モデルです。テキストプロンプトから 4〜30 秒・720p の動画を横長 16:9 か縦長 9:16 で作ります。先頭フレームの画像を 1 枚加えればその画像から動画が始まり、参照画像を最大 4 枚加えれば同じ人物や被写体を保てます。Meta は、映像と同時に音声も生成すると説明しています。apimodels.app では、Meta の Muse Video モデルを POST /v1/video/generations 上の 1 つのモデル ID muse-video で提供しています。失敗した生成は課金されず、料金はリクエストした秒数あたり $0.037 です。
Muse Video の制限をすべて挙げます。出力は 720p のみ(1080p・2K・4K・480p はなし)。形は横長 16:9 の 1280×720 か縦長 9:16 の 720×1280 のみ(正方形・4:3・21:9 などほかの比率はなし)。長さは 4〜30 の整数秒で、5・6・8・10・15・20・25・30 秒はそのまま、それ以外は切り上げ、小数は不可。画像は、先頭フレーム 1 枚か、同じ人物や被写体を保つ参照画像最大 4 枚のどちらか一方で、両方は不可。各画像は PNG・JPEG・WebP、20 MB まで(末尾フレームはなし、参照画像は 4 枚まで)。動画入力・音声入力、手持ちの音声へのリップシンク、動画の編集や延長はなし。Meta は音声も生成すると説明していますが、すべての動画に音声が付くとは限らず、音声をオフにすることもできません。negative_prompt、seed、カメラ制御パラメーターはなし(カメラの動きはプロンプトに書きます)。プロンプトは 4,000 文字まで。別の解像度や比率、先頭フレームと参照画像の同時指定、5 枚以上の参照画像、末尾フレーム、動画や音声の入力、negative_prompt、seed、generate_audio: false など対応外の入力は、タスク作成前に 400 で拒否されます。これらの範囲内でも、すべてのリクエストが成功するわけではありません。モデルが内容を拒否したり一時的なエラーになったりすることがあり、失敗したタスクは課金されません。
使えます。1 つのモデル ID muse-video に 3 つの入力モードがあり、送った内容でモードが決まります。プロンプトだけならテキストから動画です。先頭フレームの画像を 1 枚送ると、その画像から動画が始まります。image_url で渡します(first_frame_url、image、input_reference も可)。参照画像を 1〜4 枚送ると、動画はどの画像からも始まりませんが、同じ人物・被写体・スタイルが保たれるので、繰り返し登場するキャラクターに向いています。images に配列で渡します(image_urls、reference_image_urls も可)。配列はすべて参照画像として扱うため、要素が 1 つの image_urls は先頭フレームではなく参照画像 1 枚になります。先頭フレームと参照画像はどちらか一方だけで、両方を送ったり参照画像が 5 枚以上だったりすると、タスク作成前に 400 が返ります。画像はどれも公開 URL か base64 の data URI、形式は PNG・JPEG・WebP、20 MB までです。先頭フレームは動画と同じ向き、つまり 16:9 なら横長、9:16 なら縦長が向いています。末尾フレーム(last_frame_url)、参照動画、音声入力には対応していません。料金は 3 つのモードとも同じです。
参照画像は、誰が・何が映るべきかをモデルに伝えるもので、動画のフレームにはなりません。同じ人物や被写体の画像を 1〜4 枚 images に入れ、プロンプトには新しい場面を書き、「参照画像と同じ若い女性」のように参照画像を指して書きます。2026 年 10 月 30 日に 1 回テストしました。同じ若い女性の写真 4 枚(枕に寝そべる、笑顔、ピースサイン、手で口元を隠して笑う)と、プロンプト "The same young woman from the reference images walks barefoot along a beach at sunset, smiling back at the camera, handheld vertical shot"、4 秒、9:16 で送ったところ、88 秒で音声トラック付きの 5.0 秒・720×1280 の動画が返りました。動画はどの参照画像からも始まらず、最初から海辺の場面でした。女性の顔と髪型は同じで、服装も近い雰囲気でした(参照画像のクリーム色のキャミソールが白いスリップドレスに)。ピースサインや口元を隠して笑うしぐさも参照画像から引き継がれ、5 秒のあいだにアップ、引き、後ろ姿と何度かカットが切り替わりました。これは 1 回のテストで、似せ方やカット構成を保証するものではありません。特定の画像から必ず始めたい場合は先頭フレームを使ってください。参照画像に追加料金はなく、参照画像付きの 4 秒リクエストはテキストから動画の 4 秒とまったく同じ額で課金されました。
4〜30 秒で、duration に整数秒で指定します(OpenAI 形式の seconds も可)。省略すると 5 秒です。出力の長さは段階式で、5・6・8・10・15・20・25・30 秒のリクエストはちょうどその長さで返り、それ以外の整数は次の段階に切り上げられます。4 → 5 秒、7 → 8 秒、9 → 10 秒、11〜14 → 15 秒、16〜19 → 20 秒、21〜24 → 25 秒、26〜29 → 30 秒です。支払った長さより短い動画が返ることはありません。長さをきっちり合わせたいときは、段階の値でリクエストしてください。小数や 4〜30 の範囲外の値は、タスク作成前に 400 が返ります。
720p のみで、形は 2 種類です。横長 16:9 の 1280×720(既定)と、縦長 9:16 の 720×1280 です。aspect_ratio に 16:9 か 9:16 を指定するか、size に 1280x720 か 720x1280 を指定します。resolution は省略でき、指定できるのは 720p だけです。正方形やほかの比率、1080p はなく、指定するとタスク作成前に 400 が返ります。黙って別のサイズで納品することはありません。どの動画も H.264 の MP4、24 fps です。
Meta は、Muse Video が映像と同時に音声も生成すると説明しています。2026 年 10 月 30 日のローンチ時の自社テストでは、4 秒のリクエスト 2 件がどちらも 5.0 秒の動画で返り、横長のほうには AAC の音声トラックがありましたが、縦長のほうは無音でした。音声が必須のパイプラインでは、MP4 ごとに音声トラックの有無を確認し(ffprobe で確認できます)、音声のない動画には BGM やナレーションを付けるなどの代替策を用意してください。音声はオフにできません。generate_audio: false は 400("muse-video cannot turn sound off: the model decides whether a clip has sound")になり、generate_audio: true は受け付けますが、音声が付くことは保証されません。
10 秒までの動画は通常 1〜2 分、15〜30 秒の動画は通常 3〜7 分です。4 秒のテストリクエストは約 1.5 分で完了しました。呼び出しは非同期で、タスクを作成するとすぐに taskId が返ります。その後は 10〜15 秒ごとに GET /v1/video/generations?task_id= をポーリングするか、callback_url を渡して当社からの POST を待ちます。
リクエストした秒数あたり $0.037 で、送った duration に対して課金されます。4 秒 $0.148、5 秒(既定)$0.185、6 秒 $0.222、8 秒 $0.296、10 秒 $0.37、15 秒 $0.555、20 秒 $0.74、25 秒 $0.925、30 秒 $1.11 です。段階の間の長さは、リクエストした秒数で課金されます。たとえば 7 秒は $0.259 で、届く動画は 8 秒です。先頭フレームや参照画像に追加料金はなく、3 つのモードとも同じ料金です。アスペクト比によっても価格は変わりません。失敗した生成は課金されません。
すべての Muse Video リクエストが成功するわけではありません。生成が失敗する理由は 3 つあります。モデルが内容を拒否した場合、生成が一時的なエラーになった場合、そして完成した動画の向きが違う、またはリクエストより短いために破棄された場合です。失敗したタスクは state が failed になり、理由は failMsg に入り、課金されません。成功率はまだ公表していません。ローンチ時のテストリクエスト 2 件はどちらも動画が返りましたが、2 件では成功率を約束するには少なすぎます。一時的なエラーは再試行し、拒否されたプロンプトは書き直し、1 回目で必ず成功する前提のパイプラインは避けてください。Muse Video が処理できないリクエストはそもそもタスクになりません。prompt がない、または 4,000 文字を超える、duration が 4〜30 の整数でない、resolution が 720p 以外、アスペクト比が 16:9 でも 9:16 でもない、先頭フレームと参照画像を同時に指定、参照画像が 5 枚以上、末尾フレームがある、動画や音声の入力がある、negative_prompt や seed がある、generate_audio が false。これらはすべて、タスク作成前にわかりやすいエラーメッセージ付きの 400 が返ります。画像そのもののチェックは実行時に行います。PNG・JPEG・WebP 以外の画像や 20 MB を超える画像があると、タスクは理由付きで失敗し(例:"first-frame image must be PNG, JPEG or WebP"、"reference image 2 must be PNG, JPEG or WebP")、これも課金されません。
被写体が何か、どう動くか、カメラがどう動くかを書きます。たとえば「オレンジ色の猫が窓辺で伸びをし、日差しが差し込み、カメラがゆっくり寄っていく」のように書きます。プロンプトは 4,000 文字まで、言語は問いません。10 秒を超える動画は 10 秒前後と 20 秒前後でカットが切り替わるので、長いプロンプトは「最初の 10 秒は……、次に……」と区間ごとに書くとよいでしょう。画像から動画では、先頭フレームの向きを動画と合わせ、プロンプトにはその後に起こることを書きます。参照画像を使うときは「参照画像と同じ人物」と書いたうえで新しい場面を書きます。動画はどの参照画像からも始まらないためです。
apimodels.app でアカウントを作り、コンソールで API キーを発行します。キー 1 つとドル建ての残高 1 つで全モデルを使えます。次のように送信します:curl -X POST https://api.apimodels.app/v1/video/generations -H "Authorization: Bearer YOUR_API_KEY" -H "Content-Type: application/json" -d '{"model": "muse-video", "prompt": "オレンジ色の猫が窓辺で伸びをし、日差しが差し込み、カメラがゆっくり寄っていく", "duration": 5, "aspect_ratio": "16:9"}'。自分の先頭フレームから始めるには "image_url" を、同じ人物や被写体を保つには参照画像を最大 4 枚入れた "images" を加えます。レスポンスの taskId を使い、state が completed になるまで 10〜15 秒ごとに GET /v1/video/generations?task_id= をポーリングするか callback_url を渡し、30 日以内に resultUrls から MP4 をダウンロードしてください。
完全に無料ではありません。条件を満たす新規アカウントには $0.10 のトライアルクレジットが付きますが、Muse Video の最短リクエスト(4 秒)は $0.148 なので、最初のテストにはチャージが必要です。チャージは $10 からです。料金は従量課金で、サブスクリプションはありません。このページのプレイグラウンドでは Generate を押す前に料金が表示され、失敗した生成は課金されません。
APIMODELS では Muse Video が 60 以上のモデルと同じ API キー・同じ残高の上に並んでいるので、選択は「相性」の問題であって「囲い込み」の問題ではありません。Text to Video、Image to Video (First Frame)、Up to 4 Reference Images、720p · 16:9 / 9:16、4–30s · Exact at 5/6/8/10/15/20/25/30s、Sound with the Picture、Failed Generations Not Charged、$0.037/s に対応しており、他の動画生成モデルと価格・機能を並べて評価できます。乗り換えはモデル名の文字列を 1 つ書き換えるだけ。新しいアカウントも追加の実装も要りません。動画生成の選択肢と最新価格は apimodels.app/models で確認できます。
Muse Video は次に対応しています: Text to Video、Image to Video (First Frame)、Up to 4 Reference Images、720p · 16:9 / 9:16、4–30s · Exact at 5/6/8/10/15/20/25/30s、Sound with the Picture、Failed Generations Not Charged、$0.037/s。パラメータの全一覧と呼び出し例は APIMODELS のドキュメントをご覧ください。
はい。APIMODELS は Muse Video を単一の統一 API とキー 1 本で提供します。プロバイダごとのアカウントも、各社の地域ごとのネットワーク経路を自分で面倒みる必要もありません。
Stripe(Visa、Mastercard などの国際カード)と Alipay に対応しています。支払い後、残高はすぐ反映されます。
