grok-imagine-image-2Grok Imagine Image 2.0 is xAI's image model built for work you ship rather than pictures you look at. It plans typography and layout the way a designer would — on a 2K poster we asked for an exact headline, a date line and a small-print URL, and all three came back legible and character-for-character correct. It fuses up to three reference images in a single call, honouring which subject goes where. And across edits it holds the subject and the scene: change a product's colour and the object, the surface, the light and the surrounding props all carry over. One honest caveat, measured rather than assumed — it re-renders the frame rather than editing pixels in place, so composition and crop shift between passes. That makes it excellent for recolouring, restyling, adding or removing elements and multi-reference composites, and the wrong tool when a brief demands every other pixel stay untouched. Four price tiers from $0.03: 1K or 2K, low or medium quality.
Omitting quality in the API defaults to medium. Reference images are not charged extra.
Generated image will appear here
Enter a prompt and click Generate
Asked for an exact headline, a date line and a small-print URL on a 2K poster, all three came back legible and character-for-character correct — checked against the live model, not quoted from a launch post.
Send up to three reference images and say which goes where; the model keeps each subject identifiable rather than redrawing them from the text. A fourth is rejected outright instead of being silently dropped.
Recolour a product and the object, the surface, the lighting and the surrounding props all carry over. What does not carry over is the framing — see the next point.
Composition and crop shift between passes: the subject may sit closer, the camera angle may change. Ideal for recolouring, restyling, adding or removing elements. The wrong tool when the brief is "change this one thing and nothing else".
Ask for a transparent background and it paints the grey-and-white checkerboard as ordinary pixels; the PNG carries no alpha channel. The result looks like a cutout in a thumbnail and is not one. Use a dedicated background-removal step instead.
1K Low $0.03, 2K Low $0.04, 1K Medium $0.045, 2K Medium $0.06 — 25% under xAI list on three tiers and 33% under on 2K Low. Reference images cost nothing extra here, though xAI bills $0.01 each. Fourteen aspect ratios including 19.5:9 and 20:9.
Grok Imagine Image 2.0은(는) xAI의 이미지 생성 API입니다. Grok Imagine Image 2.0 is xAI's image model built for work you ship rather than pictures you look at. It plans typography and layout the way a designer would — on a 2K poster we asked for an exact headline, a date line and a small-print URL, and all three came back legible and character-for-character correct. It fuses up to three reference images in a single call, honouring which subject goes where. And across edits it holds the subject and the scene: change a product's colour and the object, the surface, the light and the surrounding props all carry over. One honest caveat, measured rather than assumed — it re-renders the frame rather than editing pixels in place, so composition and crop shift between passes. That makes it excellent for recolouring, restyling, adding or removing elements and multi-reference composites, and the wrong tool when a brief demands every other pixel stay untouched. Four price tiers from $0.03: 1K or 2K, low or medium quality. APIMODELS 플랫폼을 거치면 통합 API와 투명한 종량 과금으로 이 모델을 호출할 수 있습니다. 현재 가격: 1K Low: $0.03, 2K Low: $0.04, 1K Medium: $0.045, 2K Medium: $0.06.
온라인 스토어와 광고, 마케팅 자료에 쓸 고품질 상품 비주얼을 생성합니다.
눈길을 끄는 비주얼을 만들어 참여도와 브랜드 인지도를 끌어올립니다.
캐릭터와 배경, 소품의 콘셉트 아트를 뽑아 게임 개발의 초반 속도를 높입니다.
포스터와 배너, 프로모션 그래픽을 기존 디자인 비용의 일부만으로 준비합니다.
Grok Imagine Image 2.0은(는) APIMODELS를 통해 1K Low: $0.03, 2K Low: $0.04, 1K Medium: $0.045, 2K Medium: $0.06에 이용할 수 있습니다. 과금은 종량제라서 생성한 만큼만 냅니다.
APIMODELS에 가입해 API 키를 받고 통합 엔드포인트를 호출하면 됩니다. cURL / Python / Node.js 예제를 담은 상세 문서를 제공합니다.
APIMODELS는 같은 Grok Imagine Image 2.0을(를) 집약 플랫폼을 통해 제공합니다. API 인터페이스가 통합되어 있어 공급자마다 계정을 만들 필요가 없고, 키 하나로 모든 모델에 닿습니다.
등급은 resolution × quality로 결정됩니다. 1K low $0.03, 2K low $0.04, 1K medium $0.045, 2K medium $0.06(장당). quality는 low와 medium 두 값뿐이며 생략하면 medium이 적용됩니다 — 즉 지정하지 않는 것은 medium 등급을 사는 것입니다. 대량 초안에는 1K low를, 실제로 게시할 결과물에는 2K medium을 쓰세요. 참조 이미지는 추가 비용이 없습니다: xAI는 입력 이미지 1장당 $0.01을 청구하지만 저희는 전가하지 않습니다. 네 등급 모두 xAI 공식가보다 25% 저렴하고, 2K low는 33% 저렴합니다.
최대 3장입니다. 한 장이면 image_url(또는 image_base64), 여러 장이면 image_urls에 배열로 넘기고 prompt 안에서 <IMAGE_0>, <IMAGE_1>처럼 지칭합니다. 네 번째는 조용히 버려지지 않고 명확한 오류로 거부됩니다 — 조용히 버려지면 합성이 성공했다고 착각하게 되므로 이 차이가 중요합니다. 참조 이미지에는 추가 비용이 없습니다. 편집 시 aspect_ratio를 생략하면 출력 비율은 첫 번째 입력 이미지를 따릅니다. 서로 다른 세 물체로 실측한 결과 셋 다 개별적으로 식별 가능했고, 텍스트로부터 다시 그려진 것이 아니었습니다.
14가지입니다. 1:1, 16:9, 9:16, 4:3, 3:4, 3:2, 2:3, 2:1, 1:2에 초광각 19.5:9, 9:19.5, 20:9, 9:20, 그리고 auto. 초광각 네 가지는 사양표를 베낀 것이 아니라 실제 채널에서 하나씩 호출해 확인했습니다(19.5:9는 1248×576 반환). 편집 시 aspect_ratio를 생략하면 첫 번째 입력 이미지의 비율을 따릅니다.
피사체와 장면은 유지하지만 구도는 다시 그립니다. 실측 결과, 빨간 주전자 사진에 '짙은 남색으로'라고 지시하자 주전자 형태, 나뭇결, 창문 빛, 창가 화분, 뒤쪽 의자가 모두 남고 색만 바뀌었습니다. 매번 달라지는 것은 구도입니다 — 카메라 각도, 크롭, 피사체 크기가 움직입니다. 픽셀 단위 수정이 아니라 같은 장면을 다시 그리기 때문입니다. 색상·질감 변경, 요소 추가·제거, 다중 참조 합성에는 훌륭하지만 '이것만 바꾸고 다른 픽셀은 손대지 말라'는 요구에는 맞지 않습니다.
불가능합니다. '투명 배경, 알파 채널'을 요청하면 회색과 흰색 체크무늬를 일반 픽셀로 그려버립니다. 반환되는 PNG는 RGB이며 알파 채널이 아예 없습니다. 썸네일에서는 완성된 누끼처럼 보이지만 실제로는 아닙니다. 2K 편집과 2K 텍스트→이미지 두 경로 모두 같은 결과였습니다. 배경 제거가 필요하면 전용 단계를 따로 두세요.
2.0은 새 세대로 타이포그래피와 다중 참조 작업에 강합니다. 2K 포스터에서 정확한 헤드라인, 날짜 줄, 작은 글씨 URL을 요청했더니 셋 다 읽을 수 있고 한 글자도 틀리지 않았습니다. 한 번의 호출로 참조 이미지를 최대 3장까지 합성하며, 네 번째는 조용히 버리지 않고 명확히 거부합니다. 가격도 $0.03부터로 Pro의 $0.08(1K) / $0.12(2K)보다 저렴합니다. Pro는 1.0 엔진의 고정밀 등급으로 남아 있습니다. apimodels.app에서 둘은 엔드포인트와 키가 같으므로 전환은 model 문자열 하나만 바꾸면 됩니다.
APIMODELS에서는 Grok Imagine Image 2.0이(가) 60개가 넘는 모델과 같은 API 키, 같은 잔액 위에 나란히 놓입니다. 그래서 선택은 궁합의 문제이지 종속의 문제가 아닙니다. Text to Image、Multi-Image Editing (up to 3)、Typography & Layout、14 Aspect Ratios、1K/2K × Low/Medium、From $0.03을(를) 지원하며 다른 이미지 생성 모델과 가격·성능을 나란히 놓고 따져볼 수 있습니다. 갈아타기는 모델 이름 문자열 하나만 바꾸면 되고 새 계정도 추가 작업도 필요 없습니다. 이미지 생성 선택지와 실시간 가격은 apimodels.app/models에서 볼 수 있습니다.
Grok Imagine Image 2.0은(는) 다음을 지원합니다: Text to Image、Multi-Image Editing (up to 3)、Typography & Layout、14 Aspect Ratios、1K/2K × Low/Medium、From $0.03. 전체 파라미터와 호출 예제는 APIMODELS 문서를 참고하세요.
네. APIMODELS는 Grok Imagine Image 2.0을(를) 하나의 통합 API와 키 한 개로 제공합니다. 공급자별 계정도 필요 없고, 각 공급자의 지역별 네트워크 경로를 직접 챙길 필요도 없습니다.
Stripe(Visa, Mastercard 등 해외 카드)와 Alipay를 지원합니다. 결제 후 잔액은 즉시 반영됩니다.
Prompts shared by their authors — copy and adapt them. Each one credits its author and links back to the original post.
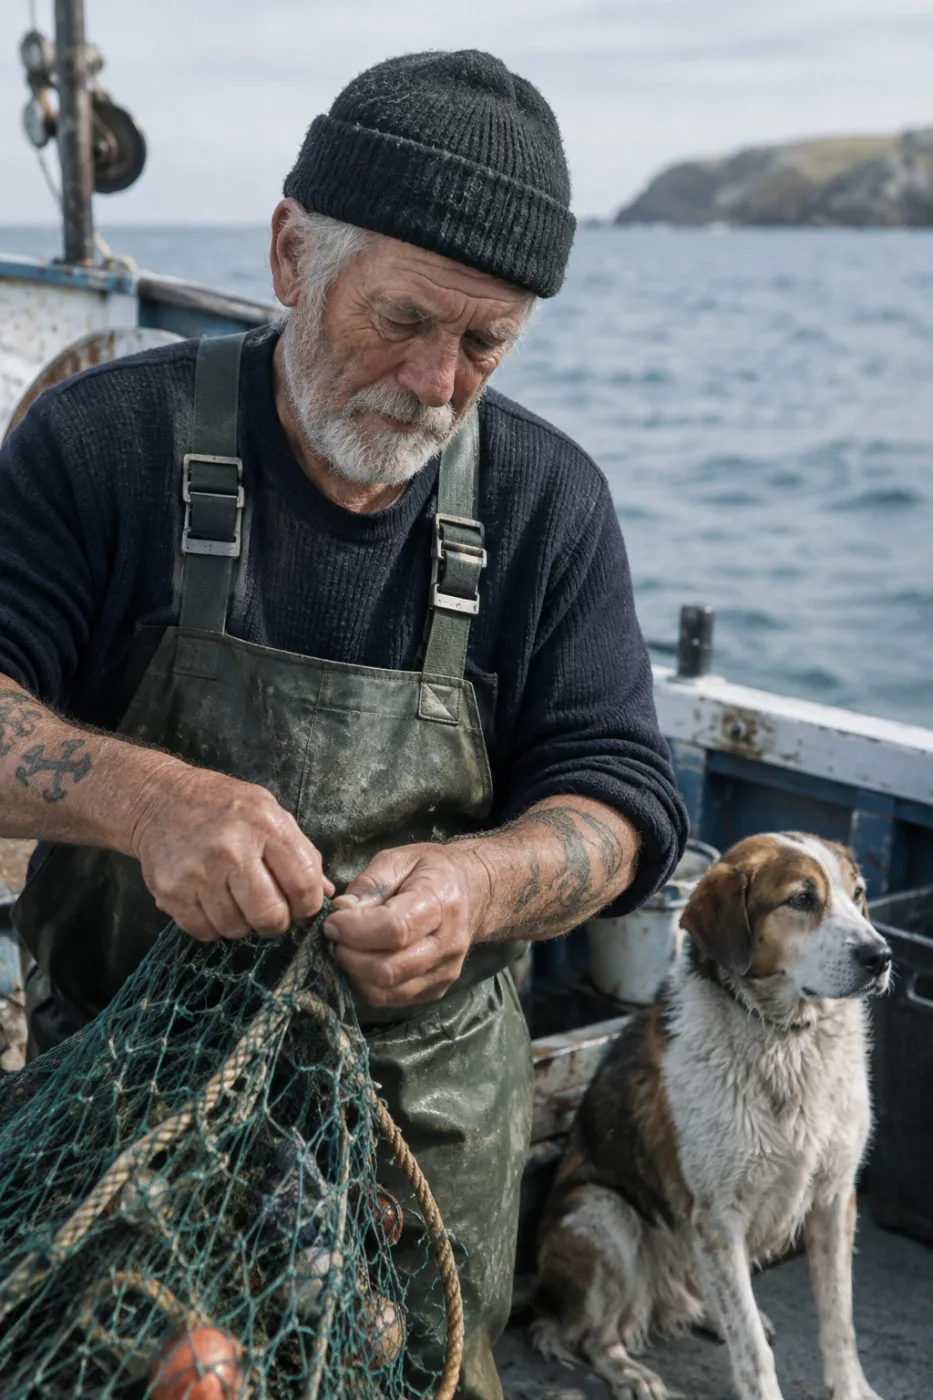
Weathered sailor on a fishing boat
Create a photorealistic candid photograph of an elderly sailor standing on a small fishing boat. He has weathered skin with visible wrinkles, pores, and sun texture, and a few faded traditional sailor tattoos on his arms. He is calmly adjusting a net while his dog sits nearby on the deck. Shot like a 35mm film photograph, medium close-up at eye level, using a 50mm lens. Soft coastal daylight, shallow depth of field, subtle film grain, natural color balance. The image should feel honest and unposed, with real skin texture, worn materials, and everyday detail. No glamorization, no heavy retouching.
by OpenAI
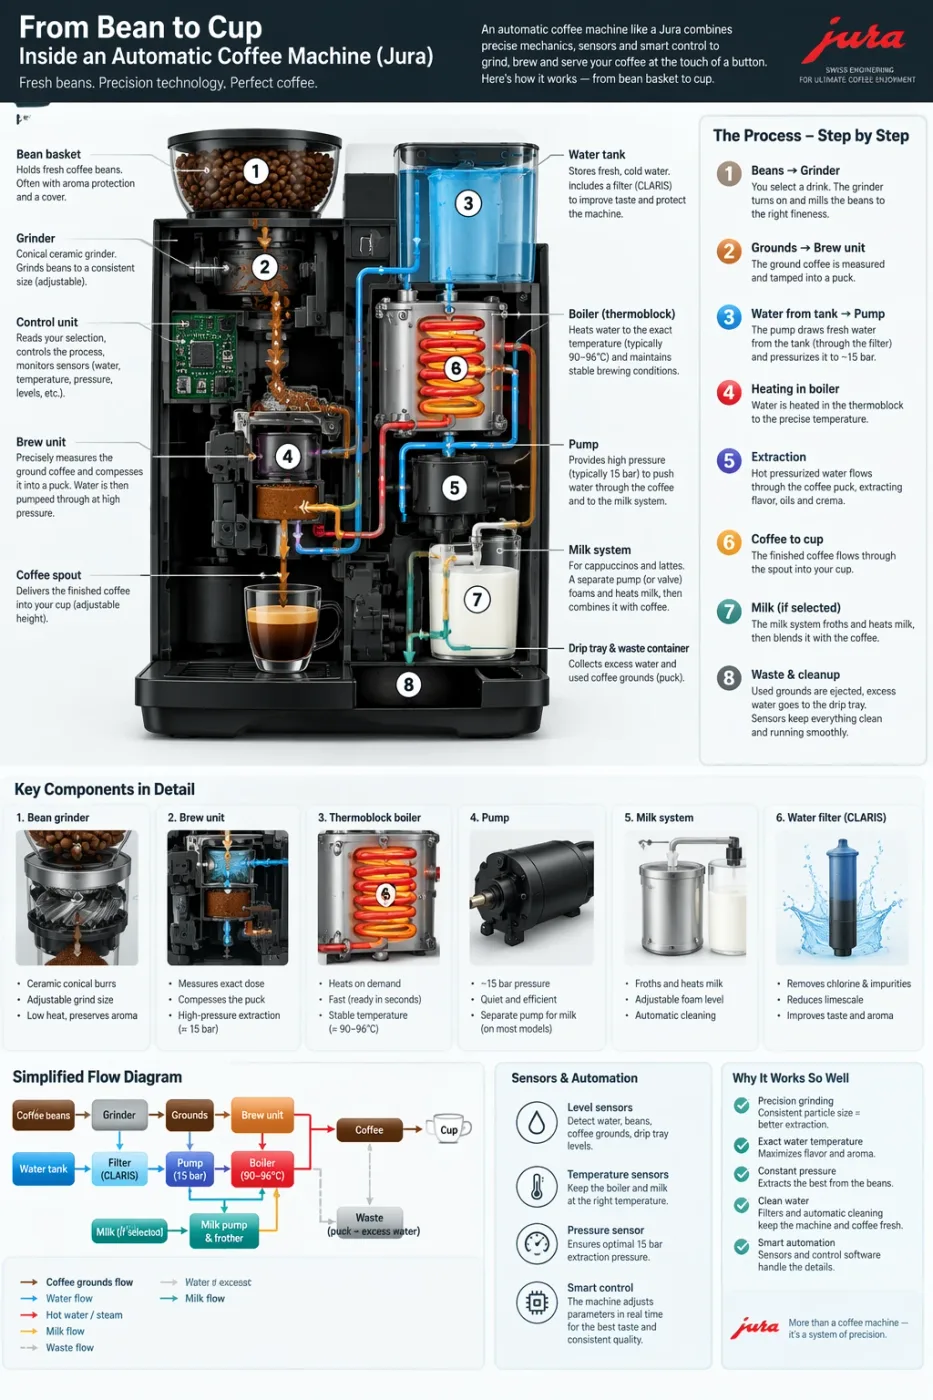
Automatic coffee machine workflow infographic
Create a detailed Infographic of the functioning and flow of an automatic coffee machine like a Jura. From bean basket, to grinding, to scale, water tank, boiler, etc. I'd like to understand technically and visually the flow.
by OpenAI
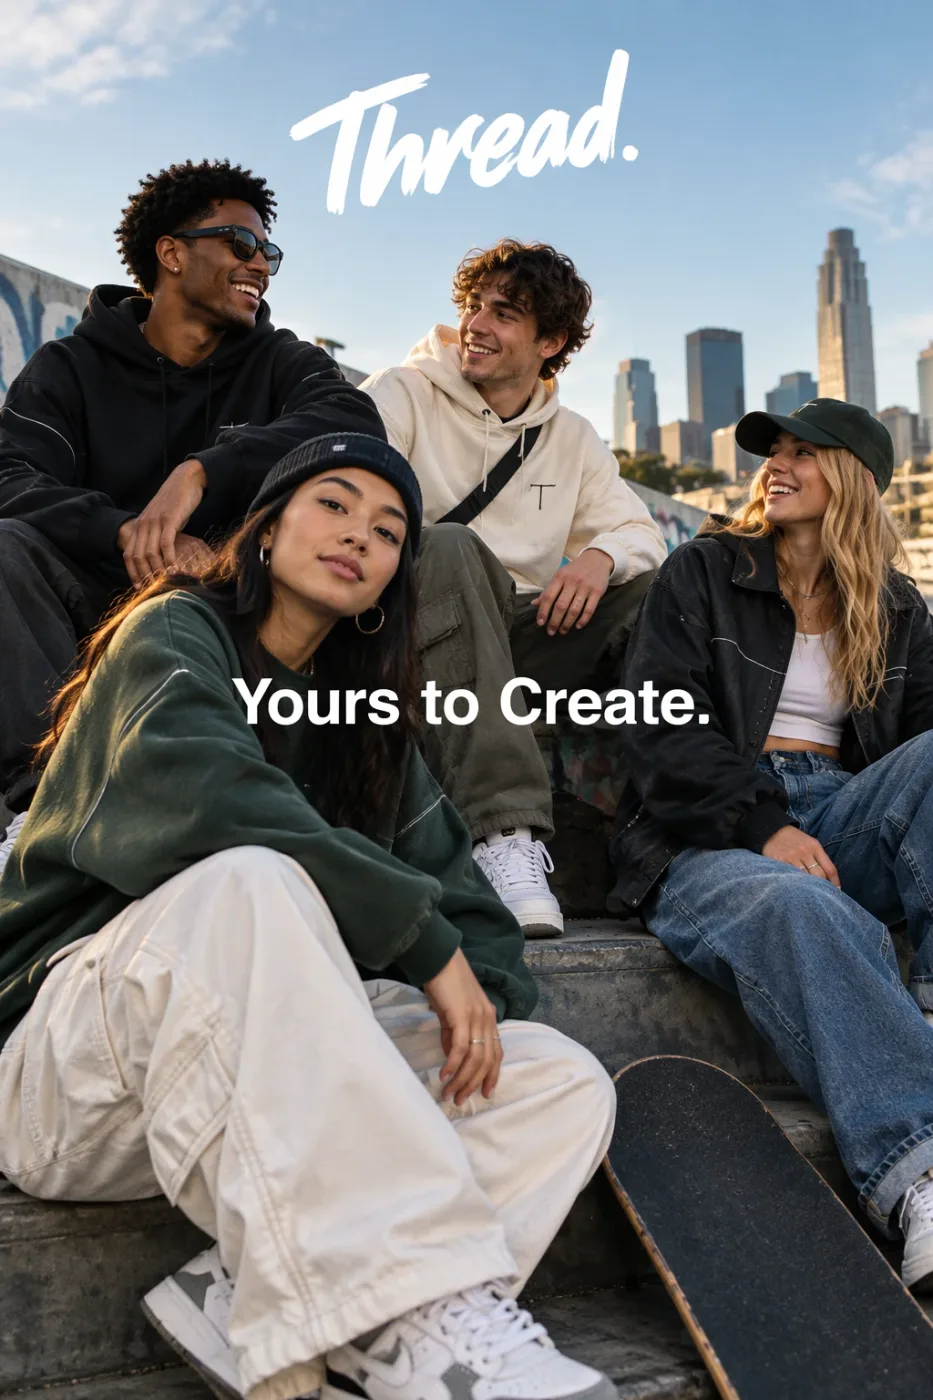
Thread streetwear ad with exact typography
Give me a cool in culture ad / fashion shot for a brand called Thread. It's a hip young street brand. The ad shows a group of friends hanging out together with the tagline "Yours to Create." Make it feel like a polished campaign image for a youth streetwear audience: stylish, contemporary, energetic, and tasteful. Use clean composition, strong color direction, natural poses, and premium fashion photography cues. Render the tagline exactly once, clearly and legibly, integrated into the ad layout. No extra text, no watermarks, no unrelated logos.
by OpenAI
We curate copy-ready prompt libraries — every entry shows its full text and a sample result, ready to adapt.
How to get access, regional availability, and how this model compares with its alternatives.
